我是芝士AI吃鱼,原创 NLP、LLM、超长文知识分享
热爱分享前沿技术知识,寻找志同道合小伙伴
公众号 :芝士AI吃鱼
欢迎来到我们提示工程系列的第四篇文章。在之前的文章中,我们探讨了各种基本的文本提示技术。今天,我们将把视野扩展到更广阔的领域:多语言提示技术。在这个日益全球化的世界中,能够处理和理解多种语言的AI系统变得越来越重要。让我们一起探索如何利用提示工程来克服语言障碍,创建真正的多语言AI应用。
1. 多语言提示技术的重要性
在开始深入技术细节之前,让我们先理解为什么多语言提示技术如此重要:
全球化需求:随着企业和组织的全球化发展,需要能够理解和生成多种语言的AI系统。 知识共享:多语言AI可以帮助跨语言知识共享,促进不同文化间的交流。 资源利用:许多语言的数字资源有限,多语言技术可以帮助低资源语言利用其他语言的资源。 公平性和包容性:确保AI系统能服务于不同语言的用户,促进技术使用的公平性。 复杂任务处理:某些任务本质上就是多语言的,如机器翻译、跨语言信息检索等。
2. 多语言提示的基本原理
多语言提示技术的核心是利用大型语言模型的跨语言理解和生成能力。这些模型通常在包含多种语言的大规模数据集上训练,因此具有一定的多语言能力。我们的目标是通过巧妙的提示设计,充分发挥这种能力。
2.1 多语言模型的工作原理
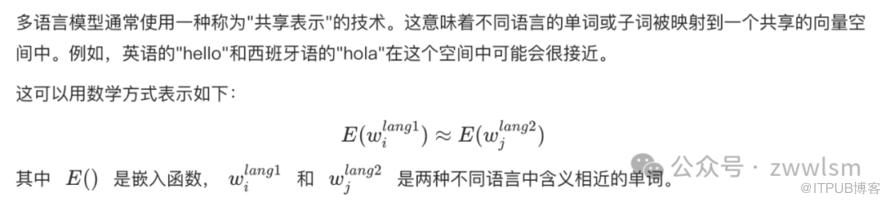
2.2 跨语言知识迁移
多语言模型的另一个重要特性是跨语言知识迁移。这意味着模型在一种语言中学到的知识可以部分地应用到另一种语言中。这个特性使得零样本跨语言迁移成为可能。
3. 多语言提示技术
现在,让我们深入探讨一些具体的多语言提示技术。

3.1 翻译提示(Translate-First Prompting)
这是最直接的多语言提示方法。它包括以下步骤:
将输入文本翻译成模型最擅长的语言(通常是英语) 在翻译后的文本上执行任务 如果需要,将结果翻译回原始语言
def translate_first_prompting(text, source_lang, target_lang, task):
    # 第一步:翻译到英语
    english_text = translate_to_english(text, source_lang)

    # 第二步:执行任务
    prompt = f"""
    Perform the following task on the given text:
    Task: {task}
    Text: "{english_text}"
    """
    result = openai.Completion.create(
        engine="text-davinci-002",
        prompt=prompt,
        max_tokens=100,
        temperature=0.7
    ).choices[0].text.strip()

    # 第三步:翻译回原语言(如果需要)
    if target_lang != "english":
        result = translate_from_english(result, target_lang)

    return result

# 使用示例
text = "这是一个需要分类的中文句子。"
task = "Classify the sentiment of this sentence as positive, negative, or neutral."
result = translate_first_prompting(text, "chinese", "chinese", task)
print(result)
这种方法的优点是简单直接,但可能会在翻译过程中丢失一些细微的语言特性。
3.2 多语言少样本学习(Multilingual Few-Shot Learning)
这种方法利用模型的跨语言迁移能力,通过在一种语言(通常是英语)中提供示例,来指导模型在其他语言中执行任务。
def multilingual_few_shot(text, lang, task):
    prompt = f"""
    Perform the given task on texts in different languages.

    Task: {task}

    Examples:
    Text (English): "This movie was fantastic! I loved every minute of it."
    Result: Positive

    Text (English): "The service at this restaurant was terrible. I'll never come back."
    Result: Negative

    Text (English): "The weather today is cloudy with a chance of rain."
    Result: Neutral

    Now perform the task on the following text:
    Text ({lang}): "{text}"
    Result:
    """

    response = openai.Completion.create(
        engine="text-davinci-002",
        prompt=prompt,
        max_tokens=50,
        temperature=0.7
    )

    return response.choices[0].text.strip()

# 使用示例
text = "Ce film était incroyable ! Je le recommande vivement."
task = "Classify the sentiment as Positive, Negative, or Neutral"
result = multilingual_few_shot(text, "French", task)
print(result)
这种方法的优势在于它可以利用模型的跨语言迁移能力,即使在没有目标语言示例的情况下也能执行任务。
3.3 多语言思维链(Multilingual Chain-of-Thought)
这种方法将思维链提示技术扩展到多语言环境中。它鼓励模型用目标语言展示推理过程。
def multilingual_cot(text, lang, task):
    prompt = f"""
    Solve the given task step by step in the specified language.

    Task: {task}

    Example (English):
    Question: If a shirt costs $15 and is on sale for 20% off, what is the final price?
    Step 1: Understand the given information
    - Original price: $15
    - Discount: 20%
    Step 2: Calculate the discount amount
    - Discount amount = $15 × 20% = $15 × 0.20 = $3
    Step 3: Subtract the discount from the original price
    - Final price = $15 - $3 = $12
    Therefore, the final price of the shirt is $12.

    Now solve this problem:
    Question ({lang}): {text}
    Step 1:
    """

    response = openai.Completion.create(
        engine="text-davinci-002",
        prompt=prompt,
        max_tokens=200,
        temperature=0.7
    )

    return response.choices[0].text.strip()

# 使用示例
text = "Si une chemise coûte 50 euros et est en solde avec une réduction de 30%, quel est le prix final ?"
task = "Solve this math problem"
result = multilingual_cot(text, "French", task)
print(result)
这种方法的优势在于它可以生成目标语言的详细推理过程,这对于教育应用或需要解释的决策特别有用。
3.4 跨语言提示(Cross-Lingual Prompting)
这种技术涉及在提示中混合使用多种语言,以充分利用模型的多语言能力。
def cross_lingual_prompting(text, source_lang, target_lang, task):
    prompt = f"""
    Perform the following task:
    Task (English): {task}

    Here are some examples in different languages:

    Input (English): "The company's profits increased by 15% last quarter."
    Output (French): "Les bénéfices de l'entreprise ont augmenté de 15% le trimestre dernier."

    Input (Spanish): "La nueva política ambiental ha generado mucho debate."
    Output (German): "Die neue Umweltpolitik hat viele Diskussionen ausgelöst."

    Now, perform the task on this input:
    Input ({source_lang}): {text}
    Output ({target_lang}):
    """

    response = openai.Completion.create(
        engine="text-davinci-002",
        prompt=prompt,
        max_tokens=100,
        temperature=0.7
    )

    return response.choices[0].text.strip()

# 使用示例
text = "人工智能正在改变我们的生活方式。"
task = "Translate the input text and then summarize its main idea."
result = cross_lingual_prompting(text, "Chinese", "English", task)
print(result)
这种方法的优势在于它可以同时处理输入语言和输出语言的转换,并且可以引导模型执行跨语言的复杂任务。
4. 高级技巧和最佳实践
在实际应用中,以下一些技巧可以帮助你更好地使用多语言提示技术:
4.1 语言标识
明确指定输入和期望输出的语言可以提高模型的准确性:
def language_identified_prompt(text, source_lang, target_lang, task):
    prompt = f"""
    Source language: {source_lang}
    Target language: {target_lang}
    Task: {task}

    Input: {text}

    Output:
    """
    # ... 使用这个提示调用模型 ...
4.2 多语言示例
在提示中包含多种语言的示例可以增强模型的跨语言能力:
multilingual_examples = """
English: The weather is nice today.
French: Il fait beau aujourd'hui.
Spanish: El tiempo está agradable hoy.
German: Das Wetter ist heute schön.

English: I love reading books.
French: J'aime lire des livres.
Spanish: Me encanta leer libros.
German: Ich liebe es, Bücher zu lesen.
"""

def multilingual_prompt(text, lang, task):
    prompt = f"""
    {multilingual_examples}

    Task: {task}

    {lang}: {text}
    """
    # ... 使用这个提示调用模型 ...
4.3 语言特定的上下文
为特定语言提供相关的文化或语言背景可以提高输出的准确性和适当性:
language_context = {
    "french": "Consider French cultural norms and expressions.",
    "japanese": "Be mindful of Japanese honorifics and levels of politeness.",
    "arabic": "Remember that Arabic is written from right to left."
}

def contextualized_prompt(text, lang, task):
    context = language_context.get(lang.lower(), "")
    prompt = f"""
    Language: {lang}
    Context: {context}
    Task: {task}

    Input: {text}

    Output:
    """
    # ... 使用这个提示调用模型 ...
5. 评估和优化
评估多语言提示的效果可能比单语言更复杂。以下是一些建议:
使用多语言基准:如XNLI(跨语言自然语言推理)或MLQA(多语言问答)来评估模型的跨语言性能。 人工评估:对于生成任务,考虑使用熟悉相关语言的人来评估输出质量。 回译评估:将输出翻译回原始语言,然后比较与原文的相似度。 多样性测试:在各种不同的语言和任务上测试你的提示,以确保其通用性。
以下是一个简单的回译评估函数示例:
def back_translation_evaluation(original_text, translated_text, source_lang, target_lang):
    # 将翻译后的文本再次翻译回原语言
    back_translated = translate(translated_text, target_lang, source_lang)

    # 计算原文和回译文本的相似度
    similarity = calculate_similarity(original_text, back_translated)

    return similarity

def calculate_similarity(text1, text2):
    # 这里可以使用各种文本相似度算法,如余弦相似度、BLEU分数等
    # 这里我们使用一个简化的实现
    return len(set(text1.split()) & set(text2.split())) / len(set(text1.split() + text2.split()))

# 使用示例
original = "人工智能正在改变我们的生活方式。"
translated = "Artificial intelligence is changing our way of life."
similarity = back_translation_evaluation(original, translated, "chinese", "english")
print(f"Back-translation similarity: {similarity}")
6. 实际应用案例:多语言客户服务聊天机器人
!https://cdn.nlark.com/yuque/0/2024/png/406504/1721310844151-f5a290c6-3c9d-4797-bbd5-477eef448f12.png
让我们通过一个实际的应用案例来综合运用我们学到的多语言提示技术。假设我们正在为一个国际电子商务平台开发一个多语言客户服务聊天机器人。这个机器人需要能够理解多种语言的客户查询,并以相应的语言回复。
import openai

def multilingual_customer_service_bot(query, lang):
    # 定义常见问题及其回答
    faq = {
        "return_policy": {
            "english": "Our return policy allows returns within 30 days of purchase.",
            "french": "Notre politique de retour permet les retours dans les 30 jours suivant l'achat.",
            "spanish": "Nuestra política de devolución permite devoluciones dentro de los 30 días posteriores a la compra."
        },
        "shipping_time": {
            "english": "Shipping usually takes 3-5 business days.",
            "french": "La livraison prend généralement 3 à 5 jours ouvrables.",
            "spanish": "El envío generalmente toma de 3 a 5 días hábiles."
        }
    }

    prompt = f"""
    You are a multilingual customer service AI for an international e-commerce platform.
    Respond to the customer's query in their language. If the query matches a common question, use the provided answer.
    If not, generate an appropriate response.

    Common questions and answers:
    1. Return Policy:
       EN: {faq['return_policy']['english']}
       FR: {faq['return_policy']['french']}
       ES: {faq['return_policy']['spanish']}

    2. Shipping Time:
       EN: {faq['shipping_time']['english']}
       FR: {faq['shipping_time']['french']}
       ES: {faq['shipping_time']['spanish']}

    Customer's language: {lang}
    Customer's query: {query}

    Your response in {lang}:
    """

    response = openai.Completion.create(
        engine="text-davinci-002",
        prompt=prompt,
        max_tokens=150,
        temperature=0.7
    )

    return response.choices[0].text.strip()

# 使用示例
queries = [
    ("What's your return policy?", "english"),
    ("Combien de temps prend la livraison ?", "french"),
    ("¿Tienen una tienda física en Madrid?", "spanish")
]

for query, lang in queries:
    response = multilingual_customer_service_bot(query, lang)
    print(f"Query ({lang}): {query}")
    print(f"Response: {response}\n")
这个示例展示了如何创建一个多语言客户服务聊天机器人。让我们分析一下这个实现的关键点:
多语言FAQ:我们预定义了一些常见问题及其多语言答案。这允许机器人对频繁询问的问题快速且准确地回应。 语言识别:我们要求用户指定查询的语言。在实际应用中,可以使用语言检测算法自动识别语言。 动态提示构建:我们构建了一个包含多语言FAQ和用户查询的复杂提示。这使模型能够理解上下文并生成适当的回复。 指令明确性:我们明确指示AI使用客户的语言回复,这有助于确保输出的一致性。 灵活性:如果查询不匹配预定义的FAQ,模型会生成一个适当的回复。这种灵活性使得机器人能够处理各种各样的查询。
7. 多语言提示技术的挑战与解决方案
尽管多语言提示技术极大地扩展了AI应用的范围,但它也面临一些独特的挑战:
7.1 语言不平衡
挑战:大多数大型语言模型在英语数据上训练得更多,可能在其他语言上表现不佳。
解决方案:
使用语言平衡的数据集微调模型 在提示中包含目标语言的额外上下文或示例 对低资源语言使用特殊的提示策略,如增加示例数量
7.2 文化差异
挑战:直接翻译或跨语言迁移可能忽视文化差异,导致不恰当或冒犯性的输出。
解决方案:
在提示中包含文化背景信息 使用文化适应的示例 实施后处理步骤以检查文化敏感性
def culturally_aware_prompt(text, source_lang, target_lang, task):
    cultural_context = {
        "japanese": "In Japanese culture, indirect communication and politeness are highly valued.",
        "german": "German communication style tends to be more direct and precise.",
        # 添加更多语言的文化上下文
    }

    prompt = f"""
    Source language: {source_lang}
    Target language: {target_lang}
    Cultural context: {cultural_context.get(target_lang.lower(), "")}
    Task: {task}

    Considering the cultural context, {task} for the following text:
    {text}

    Output:
    """
    # 使用这个提示调用模型
7.3 语言特定特性
挑战:某些语言特性(如语法性别、敬语等)在跨语言任务中可能丢失或错误处理。
解决方案:
在提示中明确指出需要注意的语言特性 使用展示相关语言特性的示例 对输出进行后处理以确保正确处理这些特性
7.4 评估的复杂性
挑战:评估多语言模型的性能需要多语言专业知识,这可能昂贵且耗时。
解决方案:
使用自动化的多语言评估指标(如多语言BLEU) 结合自动化指标和有限的人工评估 使用众包平台进行大规模多语言评估
8. 未来趋势
随着多语言AI的不断发展,我们可以期待看到以下趋势:
零样本跨语言迁移:模型将能够更有效地将在一种语言中学到的知识应用到从未见过的语言中。 多模态多语言模型:结合文本、图像、语音的多语言模型将能够处理更复杂的跨语言、跨模态任务。 语言特定的微调技术:针对特定语言或语言家族的高效微调方法将使模型在低资源语言上的表现显著提升。 实时多语言交互:AI将能够在多人多语言对话中实时翻译和调解,促进跨语言交流。 文化适应性AI:模型将更好地理解和适应不同文化的语言使用习惯和交流方式。
9. 结语
多语言提示技术为我们开启了一个令人兴奋的新领域,使AI能够跨越语言障碍,服务于更广泛的全球用户。通过本文介绍的技术和最佳实践,你应该能够开始构建强大的多语言AI应用。
然而,多语言AI仍然面临着许多挑战,需要我们不断创新和改进。随着技术的进步,我们期待看到更多令人惊叹的多语言AI应用,这些应用将帮助我们建立一个更加互联和理解的世界。
在下一篇文章中,我们将探讨多模态提示技术,看看如何将文本提示与图像、音频等其他形式的数据结合起来。敬请期待!
原文作者:芝士AI吃鱼;如有侵权,请联系管理员删除。

