最近一位朋友提了这个问题,MySQL中一条SQL执行计划,如下所示,其中有PRIMARY、<derived2>、DERIVED这些内容,他怎么和SQL对应上?
MySQL确实有些和Oracle不同的专业术语,但是背后的原理机制是相通的。
为了说明,模拟创建测试表,
create table t01(id int,code varchar(10),start_date datetime,title varchar(10),content varchar(30),class int,end_date datetime);
插入一些数据,
bisal@mysqldb: [test]> select * from t01;+------+--------+---------------------+---------+------------+-------+---------------------+| id | code | start_date | title | content | class | end_date |+------+--------+---------------------+---------+------------+-------+---------------------+| 1 | code1 | 2022-01-01 00:00:00 | title1 | content_1 | 1 | 2022-01-03 00:00:00 || 2 | code2 | 2022-01-02 00:00:00 | title2 | content_2 | 3 | 2022-01-03 00:00:00 || 3 | code3 | 2022-01-03 00:00:00 | title3 | content_3 | 2 | 2022-01-03 00:00:00 || 4 | code4 | 2022-01-04 00:00:00 | title4 | content_4 | 1 | 2022-01-06 00:00:00 || 5 | code5 | 2022-01-05 00:00:00 | title5 | content_5 | 1 | 2022-01-07 00:00:00 || 6 | code6 | 2022-01-06 00:00:00 | title6 | content_6 | 2 | 2022-01-10 00:00:00 || 7 | code7 | 2022-01-07 00:00:00 | title7 | content_7 | 1 | 2022-01-11 00:00:00 || 8 | code8 | 2022-01-08 00:00:00 | title8 | content_8 | 1 | 2022-01-12 00:00:00 || 9 | code9 | 2022-01-09 00:00:00 | title9 | content_9 | 3 | 2022-01-10 00:00:00 || 10 | code10 | 2022-01-10 00:00:00 | title10 | content_10 | 1 | 2022-01-13 00:00:00 |+------+--------+---------------------+---------+------------+-------+---------------------+10 rows in set (0.00 sec)
执行的是这条SQL,
bisal@mysqldb: [test]>-> select * from (-> (select id, code, start_date, title, content, concat('测试1:', start_date), class, end_date-> from t01 t-> where id=1 and code='code1' and title='title1' and start_date>='2022-01-01' and start_date<='2022-01-05'-> order by end_date desc limit 1)-> union all-> (select id, code, start_date, title, content, concat('测试2:', start_date), class, end_date-> from t01 t-> where id=2 and code='code2' and title='title2' and start_date>='2022-01-01' and start_date<='2022-01-05'-> order by end_date desc limit 1)-> union all-> (select id, code, start_date, title, content, concat('测试3:', start_date), class, end_date-> from t01 t-> where id=3 and code='code3' and title='title3' and start_date>='2022-01-01' and start_date<='2022-01-05'-> order by end_date desc limit 1)-> union all-> (select id, code, start_date, title, content, concat('测试4:', title), class, end_date-> from t01 t-> where id=4 and code='code4' and title='title4' and start_date>='2022-01-01' and start_date<='2022-01-05' and end_date<='2022-01-05')-> union all-> (select id, code, start_date, title, content, concat('测试5:', content), class, end_date-> from t01 t-> where id=5 and code='code5' and title='title5' and start_date>='2022-01-01' and start_date<='2022-01-05'and end_date<='2022-01-05')-> ) tt order by class, end_date desc;
他的执行计划,就和文章开始提到的基本一致,
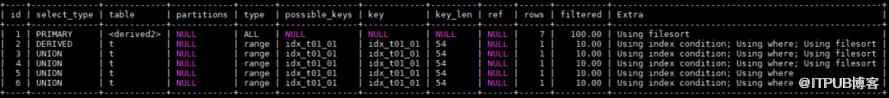
从官方文档中,我们可以了解到,什么是Derived Tables?简单来讲,就是会将FROM子句中出现的检索结果集当做一张表,例如FROM中的SELECT子查询就是一张derived table,而且每张FROM子句中的表都需要一个表别名,任何来自derived table的列必须有唯一的名称,其他要求和示例,可以参考链接,
https://dev.mysql.com/doc/refman/5.7/en/derived-tables.html
A derived table is an expression that generates a table within the scope of a query FROM clause. For example, a subquery in a SELECT statement FROM clause is a derived table:
SELECT … FROM (subquery) [AS] tbl_nameThe [AS] tbl_name clause is mandatory because every table in a FROM clause must have a name. Any columns in the derived table must have unique names
执行计划中的第一行<derived2>这张"表"是全表扫描,

原因就是上述SQL,实际可以理解为,对derived table的检索,实际上是没有任何检索条件的,
select * from ( ... ) tt order by class, end_date desc;其实仔细观察上面这个SQL,derived table中union all连接的前三个SQL检索条件基本是一致的,而union all连接的后两个SQL检索条件基本是一致的,只是SELECT中concat内容不同,因此能做改写。
以前三个SQL为例,concat通过case when判断不同的id和title条件下,应该输出的内容,where条件中带上之前所有的字段,改造完这就是独立的一条SQL,不存在子查询,
bisal@mysqldb: [test]> explain-> select id, code, start_date, content,-> (case when id=1 and code='code1' and title='title1' then concat('测试1:', start_date)-> when id=2 and code='code2' and title='title2' then concat('测试2:', start_date)-> when id=3 and code='code3' and title='title3' then concat('测试3:', start_date) end) c,-> class, end_date-> from t01-> where id in (1, 2, 3) and title in ('title1', 'title2', 'title3')-> and start_date>='2022-01-01' and start_date<='2022-01-05'-> order by class, end_date desc;+----+-------------+-------+------------+-------+---------------+------------+---------+------+------+----------+----------------------------------------------------+| id | select_type | table | partitions | type | possible_keys | key | key_len | ref | rows | filtered | Extra |+----+-------------+-------+------------+-------+---------------+------------+---------+------+------+----------+----------------------------------------------------+| 1 | SIMPLE | t01 | NULL | range | idx_t01_01 | idx_t01_01 | 5 | NULL | 3 | 10.00 | Using index condition; Using where; Using filesort |+----+-------------+-------+------------+-------+---------------+------------+---------+------+------+----------+----------------------------------------------------+1 row in set, 1 warning (0.00 sec)
优化法则之一,就是少做事儿。如果改写成这个,最大的优势,就是同一张表只需要读取一次,而之前derived table中每个union all的子查询都需要读取一次表t01。
小白学习MySQL
《小白学习MySQL - Generated Columns功能》
《小白学习MySQL - 增量统计SQL的需求 - 开窗函数的方案》
《小白学习MySQL - varchar类型字段为什么经常定义成255?》
《小白学习MySQL - TIMESTAMP类型字段非空和默认值属性的影响》
《小白学习MySQL - InnoDB支持optimize table?》
《小白学习MySQL - table_open_cache的作用》
《小白学习MySQL - only_full_group_by的校验规则》
《小白学习MySQL - max_allowed_packet》
《小白学习MySQL - mysqldump保证数据一致性的参数差异》
《小白学习MySQL - MySQL会不会受到“高水位”的影响?》
如果您认为这篇文章有些帮助,还请不吝点下文章末尾的"点赞"和"在看",或者直接转发pyq,
近期更新的文章:
《小白学习MySQL - Generated Columns功能》
近期的热文:
文章分类和索引:
原文作者:bisal的个人杂货铺;如有侵权,请联系管理员删除。

