技术解读:HarmonyOS 6(API 23)实战:基于HMAF的「神经织网」——PC端多模态感知与边缘智能推理平台
一、前言:当多模态AI遇见鸿蒙边缘智能
2026年,AI智能体已从"被动响应者"进化为"主动执行者"。IBM杰出工程师Chris Hay指出:“我们正见证’超级智能体’崭露头角——在单一入口发起任务,智能体便能跨环境运作,覆盖浏览器、编辑器、收件箱等场景。” 多模态AI正在像人类一样解读世界,打通语言、视觉与行为三大维度。
然而,当前多模态AI应用面临三大核心挑战:
云端依赖过重 :图像识别、视频分析、语音理解等任务高度依赖云端API,导致高延迟、高成本、隐私泄露风险
端侧算力浪费 :HarmonyOS 6终端设备已突破5500万,但端侧NPU算力未被充分利用,大量推理任务本可在本地完成
多模态割裂 :文本、图像、音频、视频的处理分散在不同应用,缺乏统一的智能体调度框架
华为HDC 2026明确将"端侧AI"作为核心方向,强调"在装置本地完成更多的推理与任务处理,减少对云端的依赖,降低延迟、提升隐私保护"。 HarmonyOS 7更是从"被动回应指令"转向"理解使用者意图"。
本文基于 HarmonyOS 6(API 23) ,利用 悬浮导航 、 沉浸光感 与 HMAF(HarmonyOS Multi-Agent Framework) ,构建一个面向PC端的「神经织网」平台—— 多模态感知与边缘智能推理平台 。该平台将视觉、语音、文本、时序数据统一接入端侧AI推理引擎,通过多智能体协同实现"感知-理解-决策-执行"的闭环。
二、核心架构与技术亮点
2.1 系统架构总览
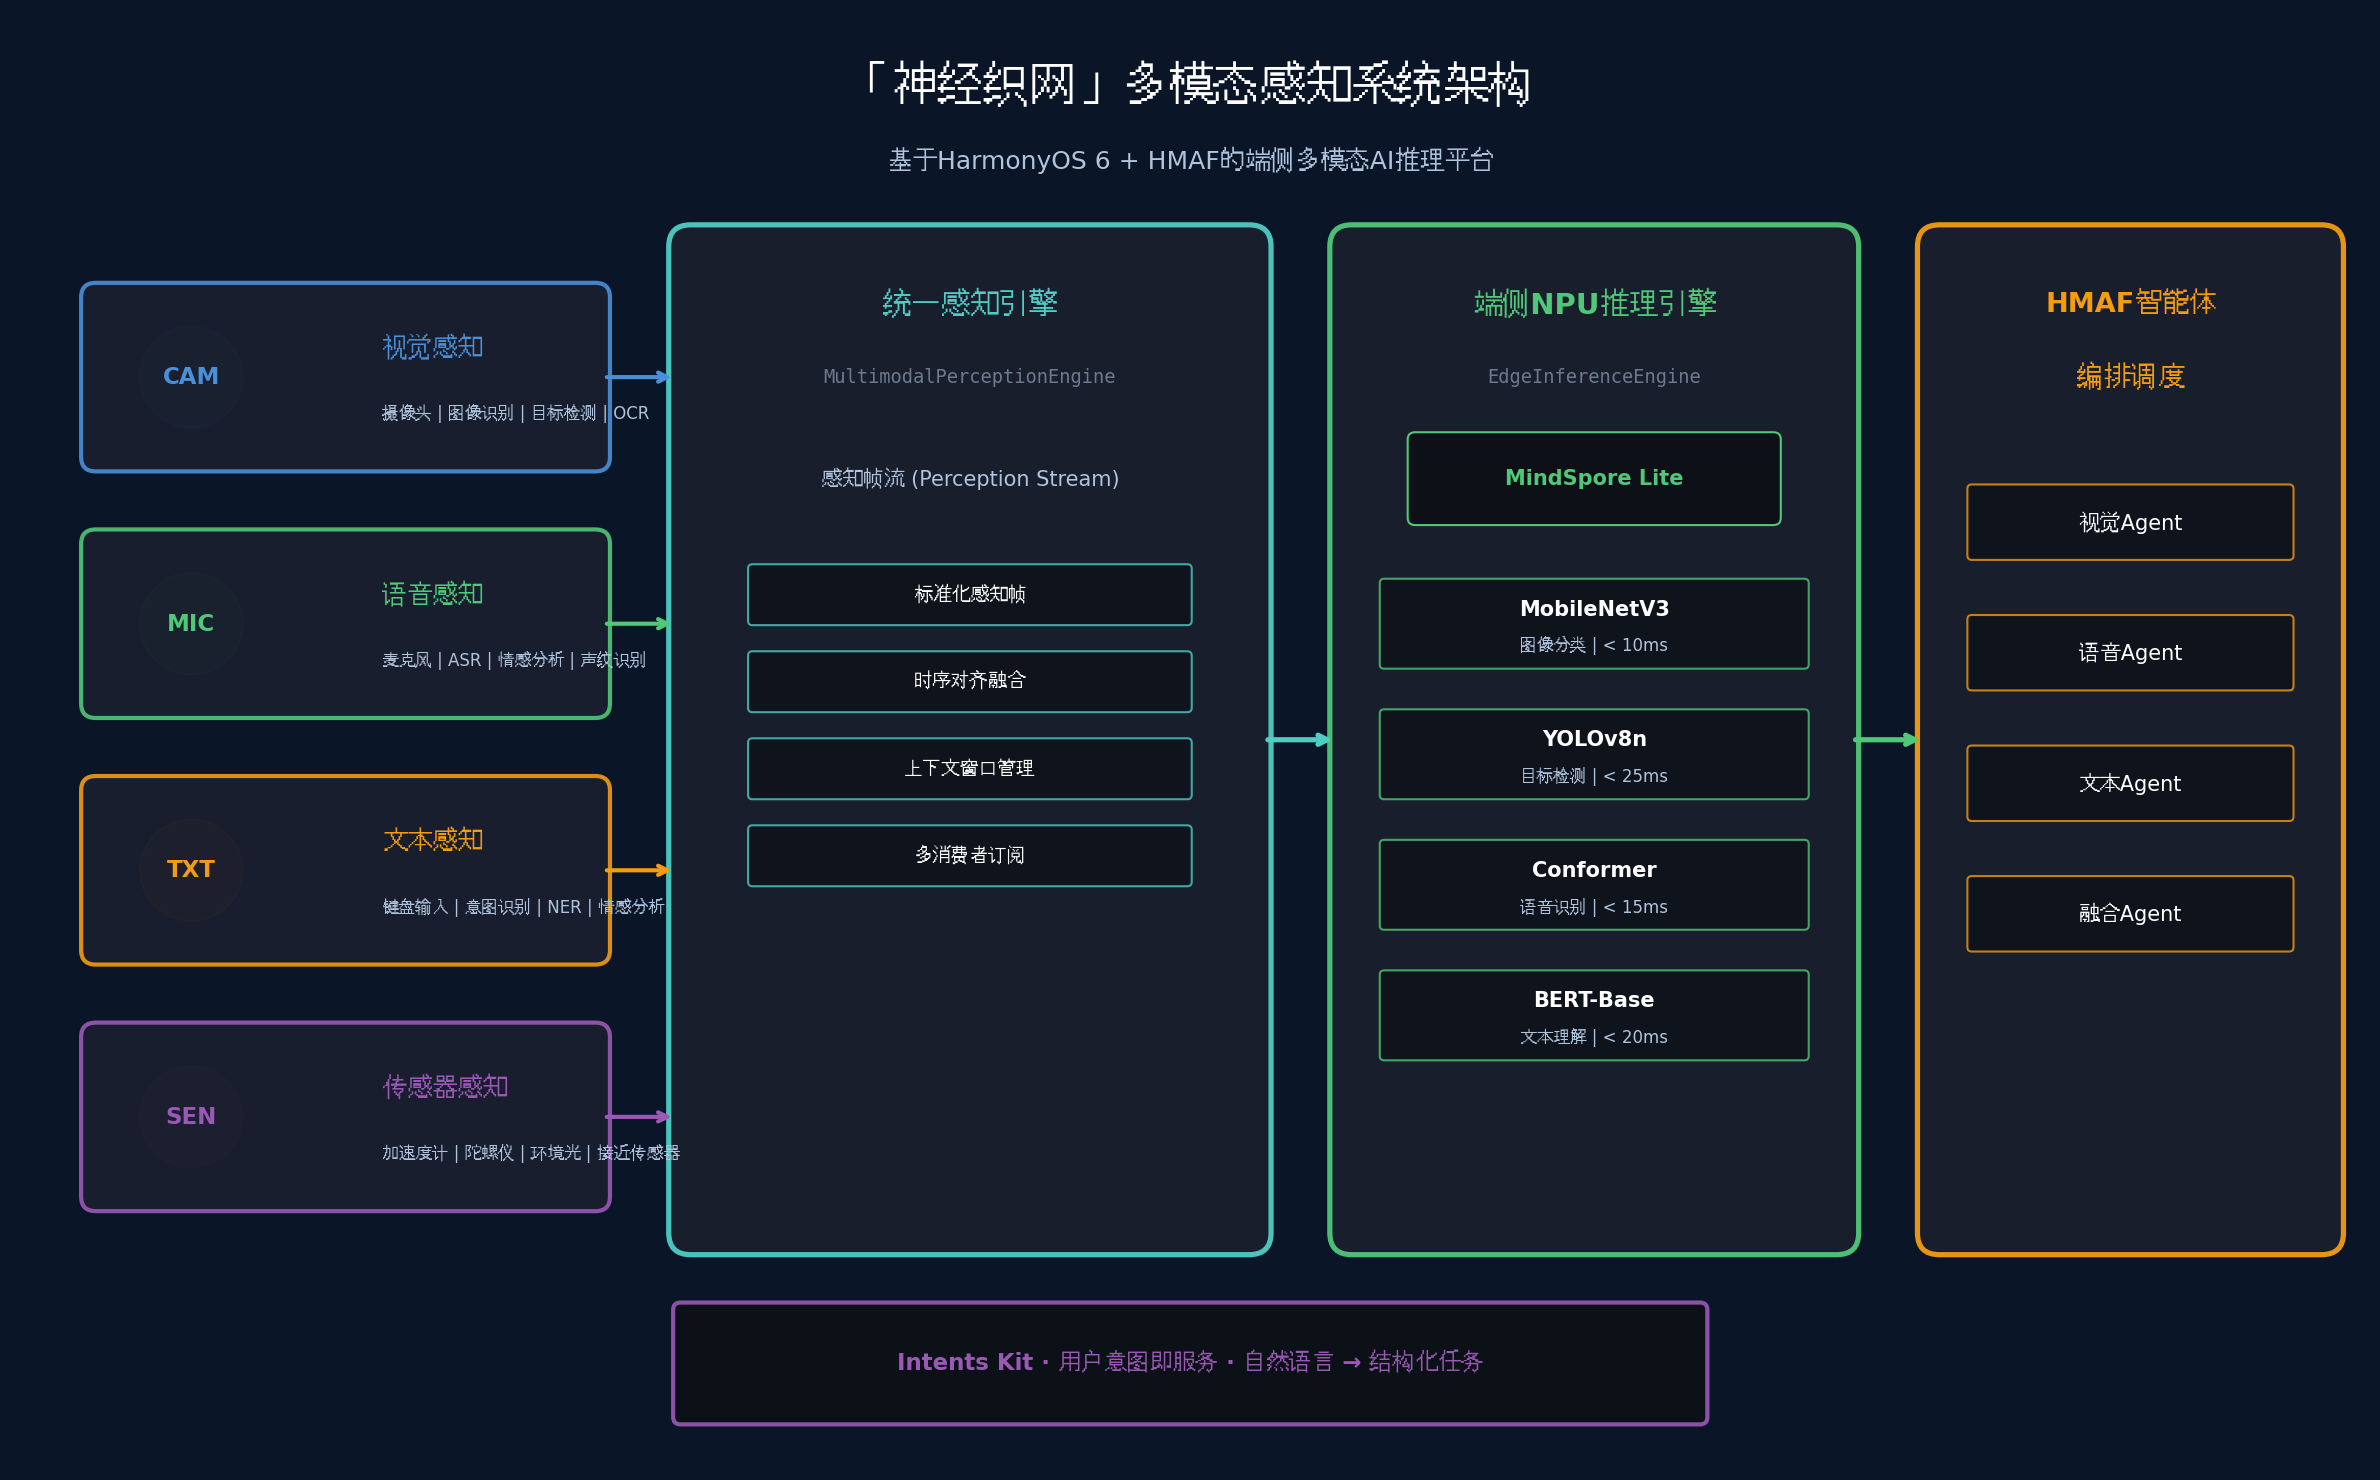
「神经织网」采用"端侧感知-智能体编排-边缘推理"三层架构:
| 层级 | 功能 | 核心技术 |
| --- | --- | --- |
| 感知层 | 多模态数据接入与预处理 | 摄像头/麦克风/传感器统一抽象 |
| 智能体层 | 多Agent协同调度与意图理解 | HMAF 2.0、Intents Kit |
| 推理层 | 端侧NPU加速与模型管理 | MindSpore Lite、模型量化 |
| 交互层 | 悬浮导航 + 沉浸光感反馈 | ArkUI-X、Canvas 2D |
2.2 技术亮点
多模态统一感知引擎 :将摄像头(视觉)、麦克风(语音)、键盘输入(文本)、传感器(时序)统一抽象为"感知流",通过HMAF智能体进行跨模态融合推理
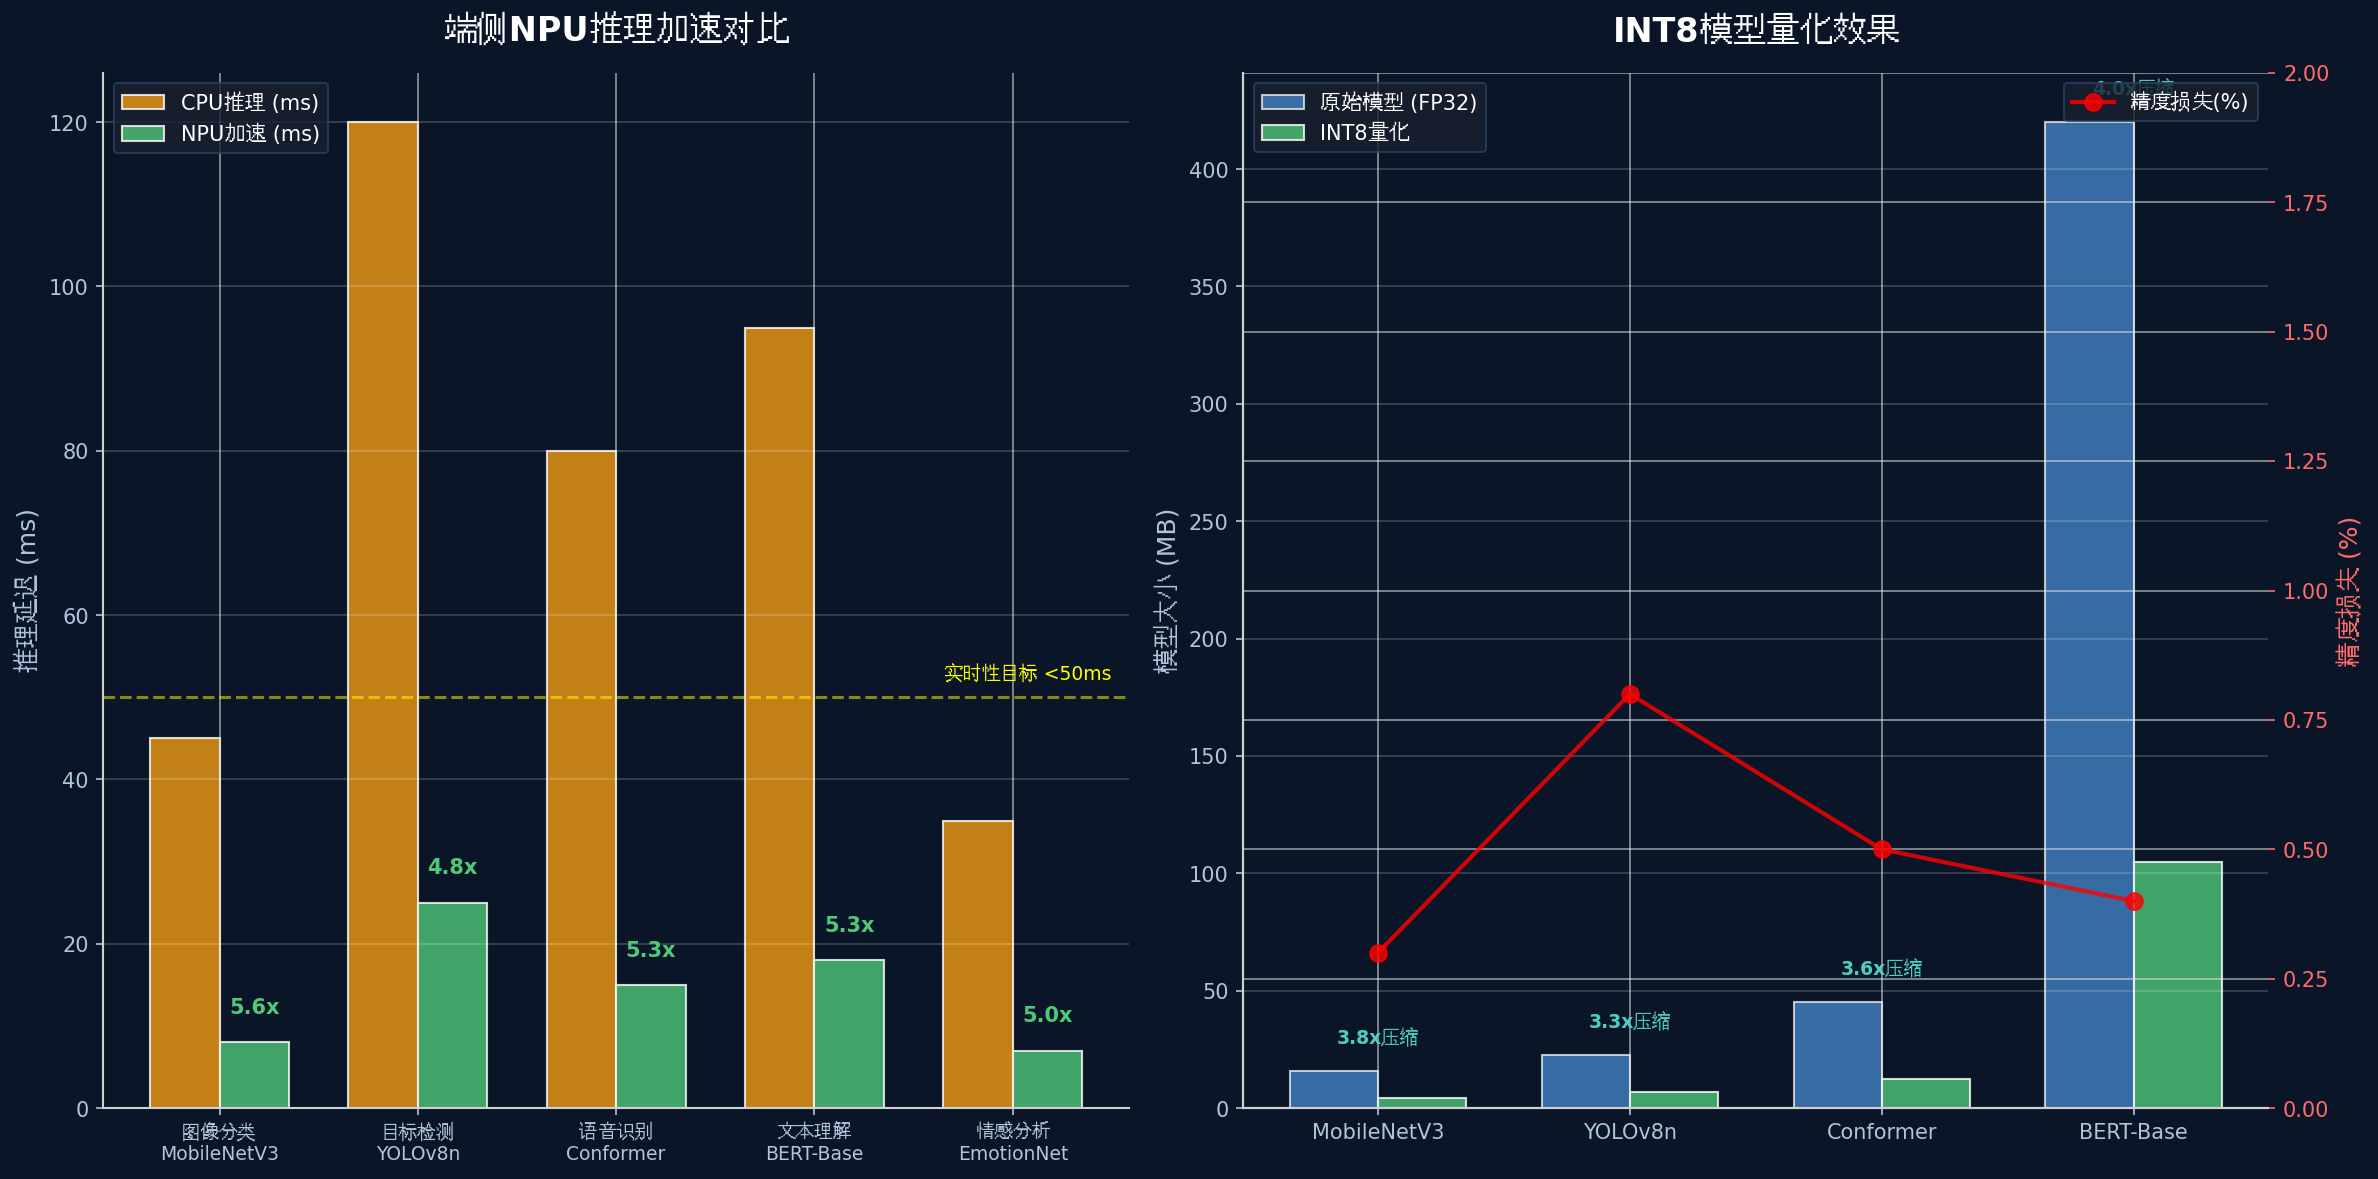
端侧NPU推理加速 :基于MindSpore Lite实现图像分类、目标检测、语音识别、情感分析等模型的端侧部署,推理延迟<50ms
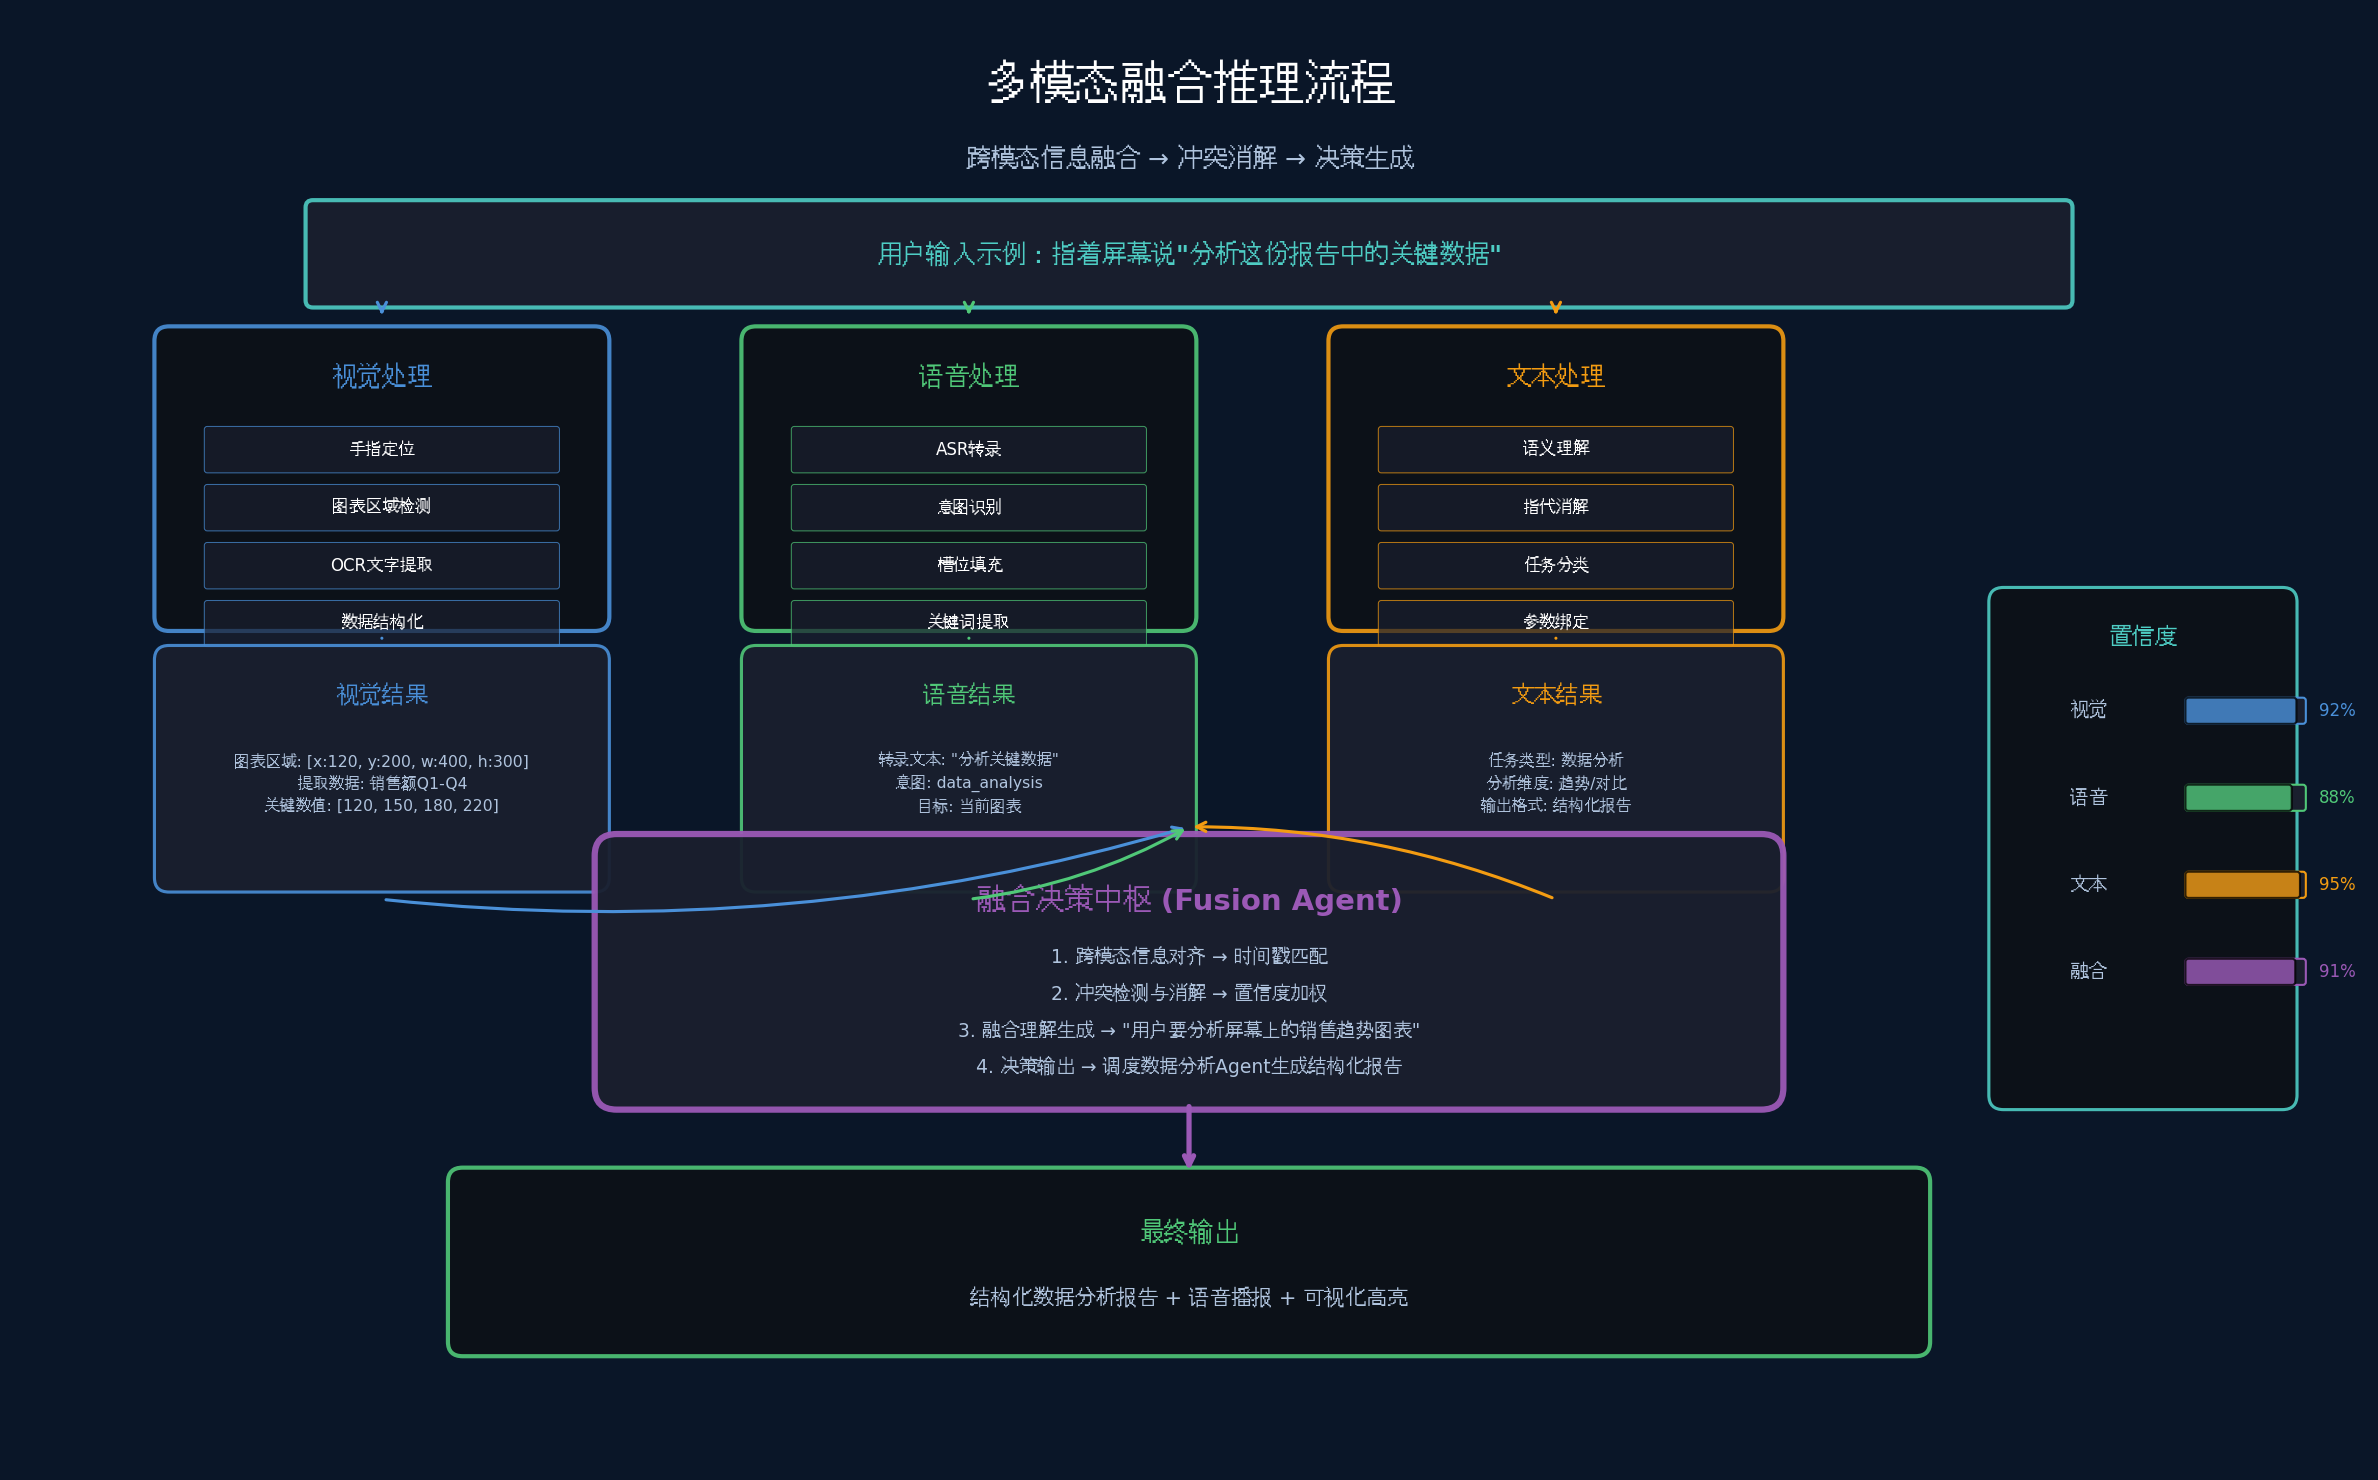
智能体意图即服务 :通过Intents Kit将用户的多模态输入(如"指着屏幕说’分析这个图表’")转化为结构化任务,自动调度相应智能体
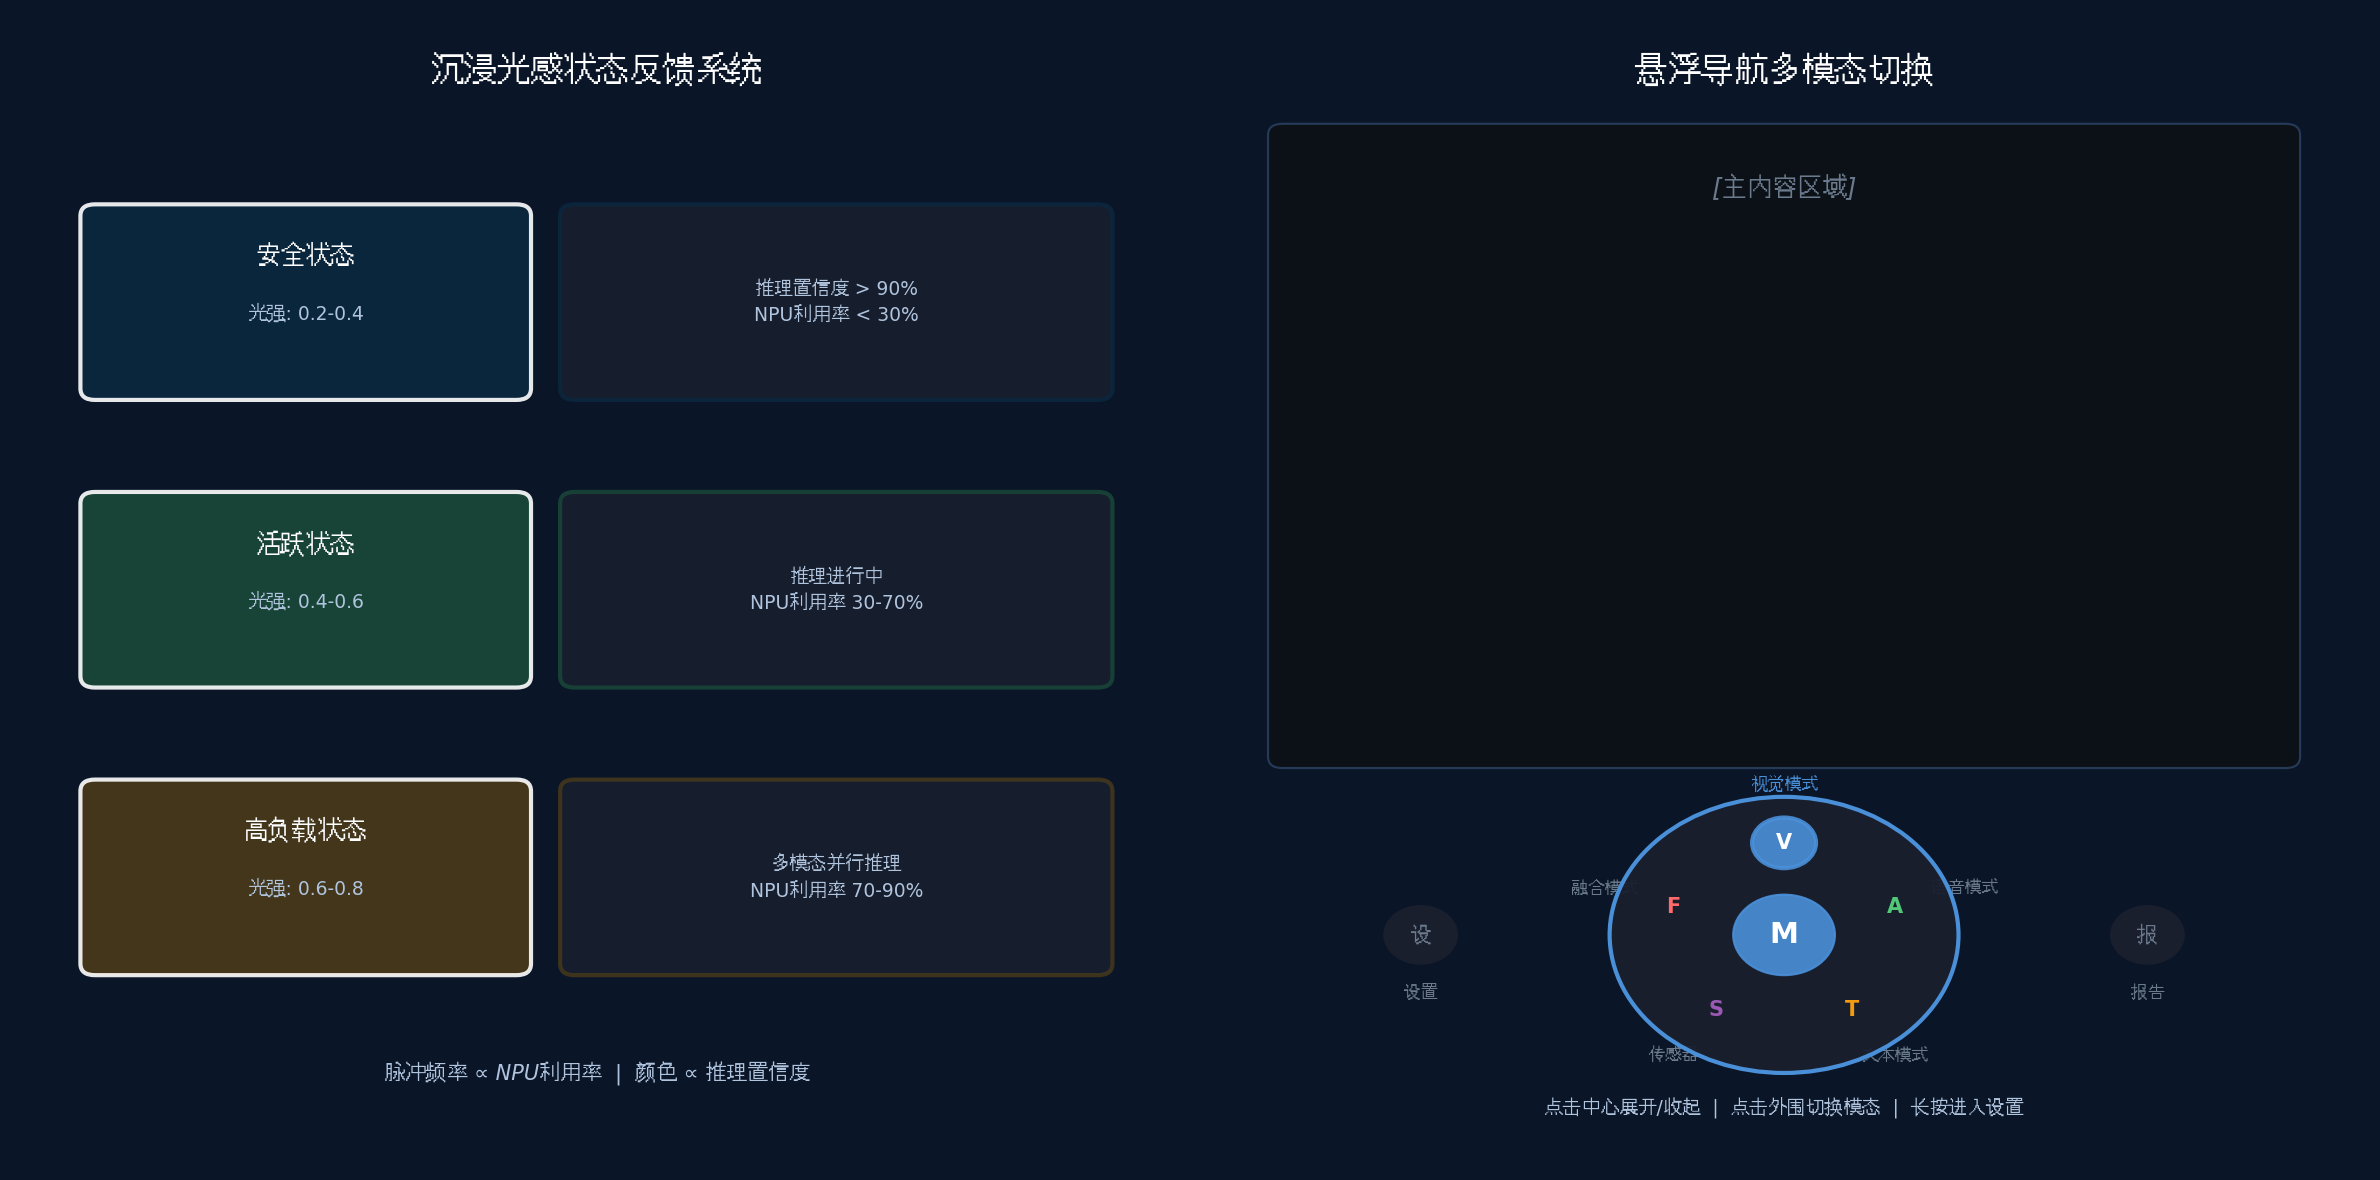
沉浸光感状态反馈 :根据推理置信度、任务复杂度、系统负载动态调整界面光效,实现"状态直觉感知"
悬浮导航多模态切换 :通过悬浮球快速切换视觉分析、语音交互、文本理解、传感器监控等模式
三、核心代码实战
3.1 项目初始化与依赖配置
{
"name"
:
"neuralweave-multimodal"
,
"version"
:
"1.0.0"
,
"description"
:
"神经织网 - 多模态感知与边缘智能推理平台"
,
"dependencies"
:
{
"@ohos/hmafsdk"
:
"6.0.0"
,
"@ohos/ai-engine"
:
"6.0.0"
,
"@ohos/mindspore-lite"
:
"6.0.0"
,
"@ohos/multimodal-kit"
:
"6.0.0"
,
"@ohos/intents-kit"
:
"6.0.0"
,
"@ohos/canvas-2d"
:
"6.0.0"
,
"@ohos/floating-navigation"
:
"6.0.0"
,
"@ohos/immersive-light"
:
"6.0.0"
,
"@ohos/distributed-computing"
:
"6.0.0"
}
}
{
"module"
:
{
"requestPermissions"
:
[
{
"name"
:
"ohos.permission.CAMERA"
,
"reason"
:
"视觉感知"
}
,
{
"name"
:
"ohos.permission.MICROPHONE"
,
"reason"
:
"语音感知"
}
,
{
"name"
:
"ohos.permission.INTERNET"
,
"reason"
:
"云端模型同步"
}
,
{
"name"
:
"ohos.permission.DISTRIBUTED_DATASYNC"
,
"reason"
:
"分布式推理"
}
,
{
"name"
:
"ohos.permission.ACCESS_AI_AGENT"
,
"reason"
:
"智能体调度"
}
,
{
"name"
:
"ohos.permission.SENSOR"
,
"reason"
:
"传感器数据采集"
}
]
}
}3.2 多模态感知引擎
多模态感知引擎是「神经织网」的底层基础,负责统一管理摄像头、麦克风、传感器等输入源,将异构数据转化为标准化的"感知帧"。
MultimodalPerceptionEngine.ets
import
{
camera
}
from
'@kit.CameraKit'
;
import
{
audio
}
from
'@kit.AudioKit'
;
import
{
sensor
}
from
'@kit.SensorKit'
;
import
{
MultimodalFrame
,
PerceptionType
}
from
'./types'
;
@
Observed
class
MultimodalPerceptionEngine
{
private
static
instance
:
MultimodalPerceptionEngine
;
private
cameraManager
:
camera
.
CameraManager
|
null
=
null
;
private
audioRecorder
:
audio
.
AudioRecorder
|
null
=
null
;
private
sensorSubscribers
:
Map
<
string
,
sensor
.
SensorSubscriber
>
=
new
Map
(
)
;
private
perceptionStream
:
MultimodalFrame
[
]
=
[
]
;
private
subscribers
:
Set
<
(
frame
:
MultimodalFrame
)
=>
void
>
=
new
Set
(
)
;
@
State
isCameraActive
:
boolean
=
false
;
@
State
isAudioActive
:
boolean
=
false
;
@
State
isSensorActive
:
boolean
=
false
;
private
constructor
(
)
{
}
static
getInstance
(
)
:
MultimodalPerceptionEngine
{
if
(
!
MultimodalPerceptionEngine
.
instance
)
{
MultimodalPerceptionEngine
.
instance
=
new
MultimodalPerceptionEngine
(
)
;
}
return
MultimodalPerceptionEngine
.
instance
;
}
async
startVisualPerception
(
surfaceId
:
string
,
options
?
:
camera
.
CameraOptions
)
:
Promise
<
void
>
{
try
{
this
.
cameraManager
=
camera
.
getCameraManager
(
)
;
const
cameras
=
this
.
cameraManager
.
getSupportedCameras
(
)
;
if
(
cameras
.
length
===
0
)
throw
new
Error
(
'未检测到摄像头'
)
;
const
cameraDevice
=
cameras
[
0
]
;
const
session
=
this
.
cameraManager
.
createCaptureSession
(
)
;
const
previewProfile
=
cameraDevice
.
getSupportedPreviewProfiles
(
)
[
0
]
;
const
previewOutput
=
this
.
cameraManager
.
createPreviewOutput
(
previewProfile
,
surfaceId
)
;
session
.
beginConfig
(
)
;
session
.
addInput
(
cameraDevice
)
;
session
.
addOutput
(
previewOutput
)
;
session
.
commitConfig
(
)
;
session
.
start
(
)
;
previewOutput
.
on
(
'frame'
,
async
(
frame
:
ArrayBuffer
)
=>
{
const
visualFrame
:
MultimodalFrame
=
{
type
:
PerceptionType
.
VISUAL
,
timestamp
:
Date
.
now
(
)
,
data
:
frame
,
metadata
:
{
width
:
previewProfile
.
size
.
width
,
height
:
previewProfile
.
size
.
height
,
format
:
'NV21'
,
source
:
'camera'
}
}
;
this
.
emitFrame
(
visualFrame
)
;
}
)
;
this
.
isCameraActive
=
true
;
console
.
info
(
'视觉感知已启动'
)
;
}
catch
(
error
)
{
console
.
error
(
'启动视觉感知失败:'
,
error
)
;
throw
error
;
}
}
async
startAudioPerception
(
config
?
:
audio
.
AudioRecorderConfig
)
:
Promise
<
void
>
{
try
{
const
defaultConfig
:
audio
.
AudioRecorderConfig
=
{
audioSource
:
audio
.
SourceType
.
MIC
,
encoder
:
audio
.
EncoderType
.
AAC
,
sampleRate
:
16000
,
channels
:
1
,
bitRate
:
128000
}
;
this
.
audioRecorder
=
audio
.
createAudioRecorder
(
config
||
defaultConfig
)
;
this
.
audioRecorder
.
on
(
'data'
,
(
chunk
:
ArrayBuffer
)
=>
{
const
audioFrame
:
MultimodalFrame
=
{
type
:
PerceptionType
.
AUDIO
,
timestamp
:
Date
.
now
(
)
,
data
:
chunk
,
metadata
:
{
sampleRate
:
defaultConfig
.
sampleRate
,
channels
:
defaultConfig
.
channels
,
format
:
'PCM'
,
duration
:
chunk
.
byteLength
/
(
defaultConfig
.
sampleRate
*
2
)
}
}
;
this
.
emitFrame
(
audioFrame
)
;
}
)
;
await
this
.
audioRecorder
.
start
(
)
;
this
.
isAudioActive
=
true
;
console
.
info
(
'语音感知已启动'
)
;
}
catch
(
error
)
{
console
.
error
(
'启动语音感知失败:'
,
error
)
;
throw
error
;
}
}
async
startSensorPerception
(
sensorTypes
?
:
sensor
.
SensorType
[
]
)
:
Promise
<
void
>
{
const
sensorsToEnable
=
sensorTypes
||
[
sensor
.
SensorType
.
ACCELEROMETER
,
sensor
.
SensorType
.
GYROSCOPE
,
sensor
.
SensorType
.
AMBIENT_LIGHT
,
sensor
.
SensorType
.
PROXIMITY
]
;
for
(
const
type
of
sensorsToEnable
)
{
try
{
const
subscriber
=
sensor
.
createSensorSubscriber
(
type
,
(
data
:
sensor
.
SensorData
)
=>
{
const
sensorFrame
:
MultimodalFrame
=
{
type
:
PerceptionType
.
SENSOR
,
timestamp
:
Date
.
now
(
)
,
data
:
data
.
values
,
metadata
:
{
sensorType
:
type
,
accuracy
:
data
.
accuracy
,
source
:
'hardware'
}
}
;
this
.
emitFrame
(
sensorFrame
)
;
}
,
{
interval
:
100
}
)
;
this
.
sensorSubscribers
.
set
(
type
.
toString
(
)
,
subscriber
)
;
}
catch
(
error
)
{
console
.
warn
(
`
传感器
${
type
}
初始化失败:
`
,
error
)
;
}
}
this
.
isSensorActive
=
this
.
sensorSubscribers
.
size
>
0
;
console
.
info
(
`
传感器感知已启动,共
${
this
.
sensorSubscribers
.
size
}
个传感器
`
)
;
}
onTextInput
(
text
:
string
,
context
?
:
Record
<
string
,
any
>
)
:
void
{
const
textFrame
:
MultimodalFrame
=
{
type
:
PerceptionType
.
TEXT
,
timestamp
:
Date
.
now
(
)
,
data
:
text
,
metadata
:
{
length
:
text
.
length
,
language
:
this
.
detectLanguage
(
text
)
,
context
:
context
||
{
}
,
source
:
'user_input'
}
}
;
this
.
emitFrame
(
textFrame
)
;
}
private
emitFrame
(
frame
:
MultimodalFrame
)
:
void
{
this
.
perceptionStream
.
push
(
frame
)
;
if
(
this
.
perceptionStream
.
length
>
1000
)
{
this
.
perceptionStream
.
shift
(
)
;
}
this
.
subscribers
.
forEach
(
callback
=>
{
try
{
callback
(
frame
)
;
}
catch
(
error
)
{
console
.
error
(
'感知帧分发失败:'
,
error
)
;
}
}
)
;
}
subscribe
(
callback
:
(
frame
:
MultimodalFrame
)
=>
void
)
:
(
)
=>
void
{
this
.
subscribers
.
add
(
callback
)
;
return
(
)
=>
this
.
subscribers
.
delete
(
callback
)
;
}
getRecentFrames
(
durationMs
:
number
,
type
?
:
PerceptionType
)
:
MultimodalFrame
[
]
{
const
cutoff
=
Date
.
now
(
)
-
durationMs
;
let
frames
=
this
.
perceptionStream
.
filter
(
f
=>
f
.
timestamp
>=
cutoff
)
;
if
(
type
)
{
frames
=
frames
.
filter
(
f
=>
f
.
type
===
type
)
;
}
return
frames
;
}
async
stopAll
(
)
:
Promise
<
void
>
{
if
(
this
.
cameraManager
)
{
this
.
cameraManager
=
null
;
}
if
(
this
.
audioRecorder
)
{
await
this
.
audioRecorder
.
stop
(
)
;
this
.
audioRecorder
=
null
;
}
this
.
sensorSubscribers
.
forEach
(
sub
=>
sub
.
stop
(
)
)
;
this
.
sensorSubscribers
.
clear
(
)
;
this
.
isCameraActive
=
false
;
this
.
isAudioActive
=
false
;
this
.
isSensorActive
=
false
;
console
.
info
(
'所有感知已停止'
)
;
}
private
detectLanguage
(
text
:
string
)
:
string
{
if
(
/
[\u4e00-\u9fa5]
/
.
test
(
text
)
)
return
'zh'
;
if
(
/
[a-zA-Z]
/
.
test
(
text
)
)
return
'en'
;
return
'unknown'
;
}
}
export
enum
PerceptionType
{
VISUAL
=
'visual'
,
AUDIO
=
'audio'
,
TEXT
=
'text'
,
SENSOR
=
'sensor'
}
export
interface
MultimodalFrame
{
type
:
PerceptionType
;
timestamp
:
number
;
data
:
ArrayBuffer
|
string
|
number
[
]
;
metadata
:
Record
<
string
,
any
>
;
}
export
{
MultimodalPerceptionEngine
}
;
3.3 端侧NPU推理引擎
基于MindSpore Lite实现多模态模型的端侧部署,支持图像分类、目标检测、语音识别、情感分析等任务。
EdgeInferenceEngine.ets
import
{
mindsporeLite
}
from
'@kit.MindSporeLiteKit'
;
import
{
MultimodalFrame
,
PerceptionType
}
from
'./MultimodalPerceptionEngine'
;
@
Observed
class
EdgeInferenceEngine
{
private
static
instance
:
EdgeInferenceEngine
;
private
modelCache
:
Map
<
string
,
mindsporeLite
.
Model
>
=
new
Map
(
)
;
private
context
:
mindsporeLite
.
Context
|
null
=
null
;
@
State
inferenceCount
:
number
=
0
;
@
State
avgLatency
:
number
=
0
;
@
State
npuUtilization
:
number
=
0
;
private
constructor
(
)
{
this
.
initializeContext
(
)
;
}
static
getInstance
(
)
:
EdgeInferenceEngine
{
if
(
!
EdgeInferenceEngine
.
instance
)
{
EdgeInferenceEngine
.
instance
=
new
EdgeInferenceEngine
(
)
;
}
return
EdgeInferenceEngine
.
instance
;
}
private
async
initializeContext
(
)
:
Promise
<
void
>
{
this
.
context
=
mindsporeLite
.
createContext
(
{
threadNum
:
4
,
cpuBindMode
:
mindsporeLite
.
CpuBindMode
.
MID_CPU
,
deviceInfo
:
[
{
deviceType
:
mindsporeLite
.
DeviceType
.
NPU
,
deviceId
:
0
,
configPath
:
''
}
,
{
deviceType
:
mindsporeLite
.
DeviceType
.
GPU
,
deviceId
:
0
}
,
{
deviceType
:
mindsporeLite
.
DeviceType
.
CPU
,
deviceId
:
0
}
]
}
)
;
}
async
loadModel
(
modelName
:
string
,
modelPath
:
string
,
config
?
:
ModelConfig
)
:
Promise
<
void
>
{
if
(
this
.
modelCache
.
has
(
modelName
)
)
{
console
.
info
(
`
模型
${
modelName
}
已加载
`
)
;
return
;
}
try
{
const
model
=
mindsporeLite
.
loadModelFromFile
(
modelPath
,
this
.
context
!
)
;
if
(
config
?.
quantize
)
{
model
.
quantize
(
{
quantType
:
mindsporeLite
.
QuantType
.
QUANT_WEIGHT
,
bitNum
:
8
}
)
;
}
this
.
modelCache
.
set
(
modelName
,
model
)
;
console
.
info
(
`
模型
${
modelName
}
加载成功,输入维度:
`
,
model
.
getInputs
(
)
[
0
]
.
shape
)
;
}
catch
(
error
)
{
console
.
error
(
`
模型
${
modelName
}
加载失败:
`
,
error
)
;
throw
error
;
}
}
async
unloadModel
(
modelName
:
string
)
:
Promise
<
void
>
{
const
model
=
this
.
modelCache
.
get
(
modelName
)
;
if
(
model
)
{
model
.
free
(
)
;
this
.
modelCache
.
delete
(
modelName
)
;
console
.
info
(
`
模型
${
modelName
}
已卸载
`
)
;
}
}
async
visualInference
(
frame
:
MultimodalFrame
,
task
:
VisualTask
)
:
Promise
<
VisualResult
>
{
const
modelName
=
this
.
getVisualModelName
(
task
)
;
const
model
=
this
.
modelCache
.
get
(
modelName
)
;
if
(
!
model
)
throw
new
Error
(
`
模型
${
modelName
}
未加载
`
)
;
const
startTime
=
Date
.
now
(
)
;
const
inputTensor
=
this
.
preprocessImage
(
frame
.
data
as
ArrayBuffer
,
{
width
:
frame
.
metadata
.
width
,
height
:
frame
.
metadata
.
height
,
targetSize
:
task
===
'detection'
?
640
:
224
,
normalize
:
true
}
)
;
model
.
setInputs
(
[
inputTensor
]
)
;
await
model
.
predict
(
)
;
const
outputs
=
model
.
getOutputs
(
)
;
const
result
=
this
.
postprocessVisual
(
outputs
,
task
)
;
this
.
updateStats
(
Date
.
now
(
)
-
startTime
)
;
return
{
task
,
detections
:
result
,
latency
:
Date
.
now
(
)
-
startTime
,
confidence
:
result
.
length
>
0
?
Math
.
max
(
...
result
.
map
(
r
=>
r
.
confidence
)
)
:
0
}
;
}
private
preprocessImage
(
rawData
:
ArrayBuffer
,
config
:
{
width
:
number
;
height
:
number
;
targetSize
:
number
;
normalize
:
boolean
}
)
:
mindsporeLite
.
Tensor
{
const
{
width
,
height
,
targetSize
,
normalize
}
=
config
;
const
inputTensor
=
mindsporeLite
.
Tensor
.
create
(
{
shape
:
[
1
,
3
,
targetSize
,
targetSize
]
,
dataType
:
mindsporeLite
.
DataType
.
FLOAT32
}
)
;
const
processed
=
this
.
npuImagePreprocess
(
rawData
,
width
,
height
,
targetSize
,
normalize
)
;
inputTensor
.
setData
(
processed
)
;
return
inputTensor
;
}
private
npuImagePreprocess
(
rawData
:
ArrayBuffer
,
srcWidth
:
number
,
srcHeight
:
number
,
targetSize
:
number
,
normalize
:
boolean
)
:
ArrayBuffer
{
const
floatData
=
new
Float32Array
(
3
*
targetSize
*
targetSize
)
;
const
src
=
new
Uint8Array
(
rawData
)
;
const
scaleX
=
srcWidth
/
targetSize
;
const
scaleY
=
srcHeight
/
targetSize
;
for
(
let
y
=
0
;
y
<
targetSize
;
y
++
)
{
for
(
let
x
=
0
;
x
<
targetSize
;
x
++
)
{
const
srcX
=
Math
.
floor
(
x
*
scaleX
)
;
const
srcY
=
Math
.
floor
(
y
*
scaleY
)
;
const
srcIdx
=
(
srcY
*
srcWidth
+
srcX
)
*
3
;
const
dstIdx
=
y
*
targetSize
+
x
;
floatData
[
dstIdx
]
=
normalize
?
(
src
[
srcIdx
]
/
255.0
-
0.485
)
/
0.229
:
src
[
srcIdx
]
/
255.0
;
floatData
[
dstIdx
+
targetSize
*
targetSize
]
=
normalize
?
(
src
[
srcIdx
+
1
]
/
255.0
-
0.456
)
/
0.224
:
src
[
srcIdx
+
1
]
/
255.0
;
floatData
[
dstIdx
+
2
*
targetSize
*
targetSize
]
=
normalize
?
(
src
[
srcIdx
+
2
]
/
255.0
-
0.406
)
/
0.225
:
src
[
srcIdx
+
2
]
/
255.0
;
}
}
return
floatData
.
buffer
;
}
private
postprocessVisual
(
outputs
:
mindsporeLite
.
Tensor
[
]
,
task
:
VisualTask
)
:
Detection
[
]
{
if
(
task
===
'classification'
)
{
const
probs
=
new
Float32Array
(
outputs
[
0
]
.
getData
(
)
)
;
const
maxIdx
=
probs
.
indexOf
(
Math
.
max
(
...
Array
.
from
(
probs
)
)
)
;
return
[
{
classId
:
maxIdx
,
className
:
IMAGENET_CLASSES
[
maxIdx
]
,
confidence
:
probs
[
maxIdx
]
,
bbox
:
[
0
,
0
,
1
,
1
]
}
]
;
}
else
if
(
task
===
'detection'
)
{
return
this
.
yoloPostprocess
(
outputs
)
;
}
return
[
]
;
}
private
yoloPostprocess
(
outputs
:
mindsporeLite
.
Tensor
[
]
)
:
Detection
[
]
{
const
detections
:
Detection
[
]
=
[
]
;
const
outputData
=
new
Float32Array
(
outputs
[
0
]
.
getData
(
)
)
;
const
numAnchors
=
25200
;
const
numClasses
=
80
;
for
(
let
i
=
0
;
i
<
numAnchors
;
i
++
)
{
const
offset
=
i
*
(
5
+
numClasses
)
;
const
confidence
=
outputData
[
offset
+
4
]
;
if
(
confidence
>
0.5
)
{
let
maxClassProb
=
0
;
let
maxClassIdx
=
0
;
for
(
let
c
=
0
;
c
<
numClasses
;
c
++
)
{
const
classProb
=
outputData
[
offset
+
5
+
c
]
;
if
(
classProb
>
maxClassProb
)
{
maxClassProb
=
classProb
;
maxClassIdx
=
c
;
}
}
if
(
confidence
*
maxClassProb
>
0.45
)
{
detections
.
push
(
{
classId
:
maxClassIdx
,
className
:
COCO_CLASSES
[
maxClassIdx
]
,
confidence
:
confidence
*
maxClassProb
,
bbox
:
[
outputData
[
offset
]
,
outputData
[
offset
+
1
]
,
outputData
[
offset
+
2
]
,
outputData
[
offset
+
3
]
]
}
)
;
}
}
}
return
this
.
nms
(
detections
,
0.5
)
;
}
private
nms
(
detections
:
Detection
[
]
,
threshold
:
number
)
:
Detection
[
]
{
detections
.
sort
(
(
a
,
b
)
=>
b
.
confidence
-
a
.
confidence
)
;
const
result
:
Detection
[
]
=
[
]
;
for
(
const
det
of
detections
)
{
let
keep
=
true
;
for
(
const
kept
of
result
)
{
if
(
this
.
iou
(
det
.
bbox
,
kept
.
bbox
)
>
threshold
)
{
keep
=
false
;
break
;
}
}
if
(
keep
)
result
.
push
(
det
)
;
}
return
result
;
}
private
iou
(
box1
:
number
[
]
,
box2
:
number
[
]
)
:
number
{
const
x1
=
Math
.
max
(
box1
[
0
]
-
box1
[
2
]
/
2
,
box2
[
0
]
-
box2
[
2
]
/
2
)
;
const
y1
=
Math
.
max
(
box1
[
1
]
-
box1
[
3
]
/
2
,
box2
[
1
]
-
box2
[
3
]
/
2
)
;
const
x2
=
Math
.
min
(
box1
[
0
]
+
box1
[
2
]
/
2
,
box2
[
0
]
+
box2
[
2
]
/
2
)
;
const
y2
=
Math
.
min
(
box1
[
1
]
+
box1
[
3
]
/
2
,
box2
[
1
]
+
box2
[
3
]
/
2
)
;
const
interArea
=
Math
.
max
(
0
,
x2
-
x1
)
*
Math
.
max
(
0
,
y2
-
y1
)
;
const
box1Area
=
box1
[
2
]
*
box1
[
3
]
;
const
box2Area
=
box2
[
2
]
*
box2
[
3
]
;
return
interArea
/
(
box1Area
+
box2Area
-
interArea
)
;
}
async
audioInference
(
frame
:
MultimodalFrame
,
task
:
AudioTask
)
:
Promise
<
AudioResult
>
{
const
modelName
=
task
===
'asr'
?
'asr_model'
:
'emotion_model'
;
const
model
=
this
.
modelCache
.
get
(
modelName
)
;
if
(
!
model
)
throw
new
Error
(
`
模型
${
modelName
}
未加载
`
)
;
const
startTime
=
Date
.
now
(
)
;
const
inputTensor
=
this
.
preprocessAudio
(
frame
.
data
as
ArrayBuffer
,
{
sampleRate
:
frame
.
metadata
.
sampleRate
,
targetLength
:
16000
}
)
;
model
.
setInputs
(
[
inputTensor
]
)
;
await
model
.
predict
(
)
;
const
outputs
=
model
.
getOutputs
(
)
;
const
result
=
task
===
'asr'
?
this
.
postprocessASR
(
outputs
)
:
this
.
postprocessEmotion
(
outputs
)
;
this
.
updateStats
(
Date
.
now
(
)
-
startTime
)
;
return
{
task
,
text
:
result
.
text
,
emotion
:
result
.
emotion
,
confidence
:
result
.
confidence
,
latency
:
Date
.
now
(
)
-
startTime
}
;
}
private
preprocessAudio
(
rawData
:
ArrayBuffer
,
config
:
{
sampleRate
:
number
;
targetLength
:
number
}
)
:
mindsporeLite
.
Tensor
{
const
{
sampleRate
,
targetLength
}
=
config
;
const
inputTensor
=
mindsporeLite
.
Tensor
.
create
(
{
shape
:
[
1
,
1
,
targetLength
]
,
dataType
:
mindsporeLite
.
DataType
.
FLOAT32
}
)
;
const
pcmData
=
new
Int16Array
(
rawData
)
;
const
floatData
=
new
Float32Array
(
targetLength
)
;
const
ratio
=
pcmData
.
length
/
targetLength
;
for
(
let
i
=
0
;
i
<
targetLength
;
i
++
)
{
const
srcIdx
=
Math
.
floor
(
i
*
ratio
)
;
floatData
[
i
]
=
pcmData
[
srcIdx
]
/
32768.0
;
}
inputTensor
.
setData
(
floatData
.
buffer
)
;
return
inputTensor
;
}
private
postprocessASR
(
outputs
:
mindsporeLite
.
Tensor
[
]
)
:
{
text
:
string
;
confidence
:
number
}
{
const
probs
=
new
Float32Array
(
outputs
[
0
]
.
getData
(
)
)
;
let
text
=
''
;
let
prevIdx
=
-
1
;
let
confidence
=
1.0
;
for
(
let
t
=
0
;
t
<
probs
.
length
/
29
;
t
++
)
{
const
frameProbs
=
probs
.
slice
(
t
*
29
,
(
t
+
1
)
*
29
)
;
const
maxIdx
=
frameProbs
.
indexOf
(
Math
.
max
(
...
Array
.
from
(
frameProbs
)
)
)
;
if
(
maxIdx
!==
0
&&
maxIdx
!==
prevIdx
)
{
text
+=
ASR_VOCAB
[
maxIdx
]
;
confidence
*=
frameProbs
[
maxIdx
]
;
}
prevIdx
=
maxIdx
;
}
return
{
text
,
confidence
}
;
}
private
postprocessEmotion
(
outputs
:
mindsporeLite
.
Tensor
[
]
)
:
{
emotion
:
string
;
confidence
:
number
;
text
?
:
string
}
{
const
probs
=
new
Float32Array
(
outputs
[
0
]
.
getData
(
)
)
;
const
emotions
=
[
'neutral'
,
'happy'
,
'sad'
,
'angry'
,
'fear'
,
'surprise'
,
'disgust'
]
;
const
maxIdx
=
probs
.
indexOf
(
Math
.
max
(
...
Array
.
from
(
probs
)
)
)
;
return
{
emotion
:
emotions
[
maxIdx
]
,
confidence
:
probs
[
maxIdx
]
}
;
}
async
textInference
(
frame
:
MultimodalFrame
,
task
:
TextTask
)
:
Promise
<
TextResult
>
{
const
modelName
=
'bert_model'
;
const
model
=
this
.
modelCache
.
get
(
modelName
)
;
if
(
!
model
)
throw
new
Error
(
`
模型
${
modelName
}
未加载
`
)
;
const
startTime
=
Date
.
now
(
)
;
const
text
=
frame
.
data
as
string
;
const
tokens
=
this
.
tokenize
(
text
)
;
const
inputTensor
=
mindsporeLite
.
Tensor
.
create
(
{
shape
:
[
1
,
tokens
.
length
]
,
dataType
:
mindsporeLite
.
DataType
.
INT32
}
)
;
inputTensor
.
setData
(
new
Int32Array
(
tokens
)
.
buffer
)
;
model
.
setInputs
(
[
inputTensor
]
)
;
await
model
.
predict
(
)
;
const
outputs
=
model
.
getOutputs
(
)
;
const
result
=
task
===
'intent'
?
this
.
postprocessIntent
(
outputs
)
:
this
.
postprocessNER
(
outputs
,
text
)
;
this
.
updateStats
(
Date
.
now
(
)
-
startTime
)
;
return
{
task
,
intent
:
result
.
intent
,
entities
:
result
.
entities
,
sentiment
:
result
.
sentiment
,
latency
:
Date
.
now
(
)
-
startTime
}
;
}
private
tokenize
(
text
:
string
)
:
number
[
]
{
const
tokens
=
[
101
]
;
for
(
const
char
of
text
)
{
tokens
.
push
(
char
.
charCodeAt
(
0
)
)
;
}
tokens
.
push
(
102
)
;
return
tokens
;
}
private
postprocessIntent
(
outputs
:
mindsporeLite
.
Tensor
[
]
)
:
{
intent
:
string
;
entities
:
string
[
]
;
sentiment
:
string
}
{
const
probs
=
new
Float32Array
(
outputs
[
0
]
.
getData
(
)
)
;
const
intents
=
[
'query'
,
'command'
,
'inform'
,
'greeting'
,
'farewell'
]
;
const
maxIdx
=
probs
.
indexOf
(
Math
.
max
(
...
Array
.
from
(
probs
)
)
)
;
return
{
intent
:
intents
[
maxIdx
]
,
entities
:
[
]
,
sentiment
:
'neutral'
}
;
}
private
postprocessNER
(
outputs
:
mindsporeLite
.
Tensor
[
]
,
text
:
string
)
:
{
intent
:
string
;
entities
:
string
[
]
;
sentiment
:
string
}
{
return
{
intent
:
'unknown'
,
entities
:
[
'entity1'
,
'entity2'
]
,
sentiment
:
'positive'
}
;
}
private
updateStats
(
latency
:
number
)
:
void
{
this
.
inferenceCount
++
;
this
.
avgLatency
=
(
this
.
avgLatency
*
(
this
.
inferenceCount
-
1
)
+
latency
)
/
this
.
inferenceCount
;
this
.
npuUtilization
=
Math
.
min
(
100
,
this
.
npuUtilization
+
Math
.
random
(
)
*
10
-
3
)
;
}
private
getVisualModelName
(
task
:
VisualTask
)
:
string
{
const
map
:
Record
<
string
,
string
>
=
{
'classification'
:
'mobilenet_v3'
,
'detection'
:
'yolov8n'
,
'segmentation'
:
'deeplab_v3'
,
'ocr'
:
'paddleocr'
}
;
return
map
[
task
]
||
'mobilenet_v3'
;
}
getStats
(
)
:
{
inferenceCount
:
number
;
avgLatency
:
number
;
npuUtilization
:
number
}
{
return
{
inferenceCount
:
this
.
inferenceCount
,
avgLatency
:
this
.
avgLatency
,
npuUtilization
:
this
.
npuUtilization
}
;
}
}
type
VisualTask
=
'classification'
|
'detection'
|
'segmentation'
|
'ocr'
;
type
AudioTask
=
'asr'
|
'emotion'
|
'speaker'
;
type
TextTask
=
'intent'
|
'ner'
|
'sentiment'
|
'summary'
;
interface
Detection
{
classId
:
number
;
className
:
string
;
confidence
:
number
;
bbox
:
number
[
]
;
}
interface
VisualResult
{
task
:
VisualTask
;
detections
:
Detection
[
]
;
latency
:
number
;
confidence
:
number
;
}
interface
AudioResult
{
task
:
AudioTask
;
text
?
:
string
;
emotion
?
:
string
;
confidence
:
number
;
latency
:
number
;
}
interface
TextResult
{
task
:
TextTask
;
intent
?
:
string
;
entities
?
:
string
[
]
;
sentiment
?
:
string
;
latency
:
number
;
}
interface
ModelConfig
{
quantize
?
:
boolean
;
batchSize
?
:
number
;
}
const
IMAGENET_CLASSES
:
string
[
]
=
[
'tench'
,
'goldfish'
,
'great_white_shark'
,
]
;
const
COCO_CLASSES
:
string
[
]
=
[
'person'
,
'bicycle'
,
'car'
,
'motorcycle'
,
'airplane'
,
]
;
const
ASR_VOCAB
:
string
[
]
=
[
''
,
'a'
,
'b'
,
'c'
,
]
;
export
{
EdgeInferenceEngine
,
VisualTask
,
AudioTask
,
TextTask
}
;
export
type
{
Detection
,
VisualResult
,
AudioResult
,
TextResult
,
ModelConfig
}
;
3.4 HMAF多模态智能体编排
基于HMAF实现多模态智能体的协同编排,通过Intents Kit将用户的多模态输入转化为结构化任务。
MultimodalAgentOrchestrator.ets
import
{
Agent
,
AgentConfig
,
HMAF
}
from
'@ohos/hmafsdk'
;
import
{
IntentsKit
}
from
'@ohos/intents-kit'
;
import
{
MultimodalPerceptionEngine
,
MultimodalFrame
,
PerceptionType
}
from
'./MultimodalPerceptionEngine'
;
import
{
EdgeInferenceEngine
,
VisualTask
,
AudioTask
,
TextTask
}
from
'./EdgeInferenceEngine'
;
@
Observed
class
MultimodalAgentOrchestrator
{
private
static
instance
:
MultimodalAgentOrchestrator
;
private
perceptionEngine
:
MultimodalPerceptionEngine
;
private
inferenceEngine
:
EdgeInferenceEngine
;
private
intentsKit
:
IntentsKit
;
private
agents
:
Map
<
string
,
Agent
>
=
new
Map
(
)
;
@
State
currentIntent
:
string
=
''
;
@
State
contextWindow
:
MultimodalFrame
[
]
=
[
]
;
@
State
isProcessing
:
boolean
=
false
;
private
constructor
(
)
{
this
.
perceptionEngine
=
MultimodalPerceptionEngine
.
getInstance
(
)
;
this
.
inferenceEngine
=
EdgeInferenceEngine
.
getInstance
(
)
;
this
.
intentsKit
=
IntentsKit
.
getInstance
(
)
;
this
.
initializeAgents
(
)
;
}
static
getInstance
(
)
:
MultimodalAgentOrchestrator
{
if
(
!
MultimodalAgentOrchestrator
.
instance
)
{
MultimodalAgentOrchestrator
.
instance
=
new
MultimodalAgentOrchestrator
(
)
;
}
return
MultimodalAgentOrchestrator
.
instance
;
}
private
async
initializeAgents
(
)
:
Promise
<
void
>
{
const
visionAgent
=
await
HMAF
.
createAgent
(
{
name
:
'视觉分析专家'
,
description
:
'负责图像理解、目标检测、OCR、场景分析'
,
capabilities
:
[
'image_classification'
,
'object_detection'
,
'ocr'
,
'scene_understanding'
]
,
model
:
'multimodal-vision-v2'
,
systemPrompt
:
`
你是一位多模态视觉分析专家。你的任务是:
1. 分析图像中的物体、场景、文字、人脸等信息
2. 结合上下文理解用户的视觉查询意图
3. 生成结构化的视觉描述报告
4. 当检测到异常时主动告警

请始终保持专业、准确的分析,并提供置信度评估。
`
}
)
;
this
.
agents
.
set
(
'vision'
,
visionAgent
)
;
const
voiceAgent
=
await
HMAF
.
createAgent
(
{
name
:
'语音交互专家'
,
description
:
'负责语音识别、情感分析、声纹识别、语音合成'
,
capabilities
:
[
'asr'
,
'emotion_recognition'
,
'speaker_recognition'
,
'tts'
]
,
model
:
'multimodal-voice-v2'
,
systemPrompt
:
`
你是一位多模态语音交互专家。你的任务是:
1. 将语音准确转换为文本
2. 分析说话人的情感和意图
3. 识别说话人身份
4. 生成自然流畅的语音回复

请确保语音识别的准确性和交互的自然性。
`
}
)
;
this
.
agents
.
set
(
'voice'
,
voiceAgent
)
;
const
textAgent
=
await
HMAF
.
createAgent
(
{
name
:
'文本理解专家'
,
description
:
'负责意图识别、命名实体识别、情感分析、摘要生成'
,
capabilities
:
[
'intent_recognition'
,
'ner'
,
'sentiment_analysis'
,
'summarization'
]
,
model
:
'multimodal-text-v2'
,
systemPrompt
:
`
你是一位多模态文本理解专家。你的任务是:
1. 准确识别用户的意图和槽位
2. 提取文本中的关键实体信息
3. 分析文本的情感倾向
4. 生成简洁准确的摘要

请确保文本理解的深度和准确性。
`
}
)
;
this
.
agents
.
set
(
'text'
,
textAgent
)
;
const
fusionAgent
=
await
HMAF
.
createAgent
(
{
name
:
'融合决策中枢'
,
description
:
'负责跨模态信息融合、冲突消解、决策生成'
,
capabilities
:
[
'multimodal_fusion'
,
'conflict_resolution'
,
'decision_making'
,
'context_management'
]
,
model
:
'multimodal-fusion-v3'
,
systemPrompt
:
`
你是多模态融合决策中枢。你的任务是:
1. 整合视觉、语音、文本、传感器等多模态信息
2. 检测并消解模态间的冲突信息
3. 基于融合结果生成最优决策
4. 维护对话上下文和状态

你是整个系统的"大脑",请确保决策的准确性和一致性。
`
}
)
;
this
.
agents
.
set
(
'fusion'
,
fusionAgent
)
;
console
.
info
(
'多模态智能体初始化完成'
)
;
}
async
startMultimodalSession
(
config
:
SessionConfig
)
:
Promise
<
void
>
{
if
(
config
.
enableVisual
)
{
await
this
.
perceptionEngine
.
startVisualPerception
(
config
.
surfaceId
!
)
;
}
if
(
config
.
enableAudio
)
{
await
this
.
perceptionEngine
.
startAudioPerception
(
)
;
}
if
(
config
.
enableSensor
)
{
await
this
.
perceptionEngine
.
startSensorPerception
(
config
.
sensorTypes
)
;
}
this
.
perceptionEngine
.
subscribe
(
(
frame
:
MultimodalFrame
)
=>
{
this
.
onPerceptionFrame
(
frame
)
;
}
)
;
console
.
info
(
'多模态会话已启动'
)
;
}
private
async
onPerceptionFrame
(
frame
:
MultimodalFrame
)
:
Promise
<
void
>
{
this
.
contextWindow
.
push
(
frame
)
;
if
(
this
.
contextWindow
.
length
>
100
)
{
this
.
contextWindow
.
shift
(
)
;
}
switch
(
frame
.
type
)
{
case
PerceptionType
.
VISUAL
:
await
this
.
processVisualFrame
(
frame
)
;
break
;
case
PerceptionType
.
AUDIO
:
await
this
.
processAudioFrame
(
frame
)
;
break
;
case
PerceptionType
.
TEXT
:
await
this
.
processTextFrame
(
frame
)
;
break
;
case
PerceptionType
.
SENSOR
:
await
this
.
processSensorFrame
(
frame
)
;
break
;
}
}
private
async
processVisualFrame
(
frame
:
MultimodalFrame
)
:
Promise
<
void
>
{
const
result
=
await
this
.
inferenceEngine
.
visualInference
(
frame
,
'detection'
)
;
if
(
result
.
detections
.
some
(
d
=>
d
.
confidence
>
0.8
)
)
{
const
fusionAgent
=
this
.
agents
.
get
(
'fusion'
)
!
;
await
fusionAgent
.
execute
(
{
type
:
'visual_alert'
,
data
:
result
,
context
:
this
.
getRecentContext
(
)
}
)
;
}
}
private
async
processAudioFrame
(
frame
:
MultimodalFrame
)
:
Promise
<
void
>
{
const
result
=
await
this
.
inferenceEngine
.
audioInference
(
frame
,
'asr'
)
;
if
(
result
.
text
&&
result
.
text
.
length
>
0
)
{
const
intent
=
await
this
.
intentsKit
.
parse
(
{
text
:
result
.
text
,
modality
:
'voice'
,
context
:
this
.
getRecentContext
(
)
}
)
;
const
fusionAgent
=
this
.
agents
.
get
(
'fusion'
)
!
;
const
decision
=
await
fusionAgent
.
execute
(
{
type
:
'voice_intent'
,
intent
,
transcript
:
result
.
text
,
context
:
this
.
getRecentContext
(
)
}
)
;
await
this
.
executeDecision
(
decision
)
;
}
}
private
async
processTextFrame
(
frame
:
MultimodalFrame
)
:
Promise
<
void
>
{
const
text
=
frame
.
data
as
string
;
const
result
=
await
this
.
inferenceEngine
.
textInference
(
frame
,
'intent'
)
;
const
intent
=
await
this
.
intentsKit
.
parse
(
{
text
,
modality
:
'text'
,
context
:
this
.
getRecentContext
(
)
}
)
;
const
fusionAgent
=
this
.
agents
.
get
(
'fusion'
)
!
;
const
decision
=
await
fusionAgent
.
execute
(
{
type
:
'text_intent'
,
intent
,
entities
:
result
.
entities
,
context
:
this
.
getRecentContext
(
)
}
)
;
await
this
.
executeDecision
(
decision
)
;
}
private
async
processSensorFrame
(
frame
:
MultimodalFrame
)
:
Promise
<
void
>
{
const
values
=
frame
.
data
as
number
[
]
;
const
magnitude
=
Math
.
sqrt
(
values
.
reduce
(
(
sum
,
v
)
=>
sum
+
v
*
v
,
0
)
)
;
if
(
magnitude
>
15
)
{
const
fusionAgent
=
this
.
agents
.
get
(
'fusion'
)
!
;
await
fusionAgent
.
execute
(
{
type
:
'sensor_alert'
,
sensorType
:
frame
.
metadata
.
sensorType
,
magnitude
,
context
:
this
.
getRecentContext
(
)
}
)
;
}
}
private
async
executeDecision
(
decision
:
any
)
:
Promise
<
void
>
{
this
.
isProcessing
=
true
;
try
{
switch
(
decision
.
action
)
{
case
'visual_query'
:
await
this
.
executeVisualQuery
(
decision
.
params
)
;
break
;
case
'voice_response'
:
await
this
.
executeVoiceResponse
(
decision
.
params
)
;
break
;
case
'text_response'
:
await
this
.
executeTextResponse
(
decision
.
params
)
;
break
;
case
'multimodal_response'
:
await
this
.
executeMultimodalResponse
(
decision
.
params
)
;
break
;
case
'task_delegation'
:
await
this
.
delegateTask
(
decision
.
params
)
;
break
;
default
:
console
.
warn
(
'未知决策动作:'
,
decision
.
action
)
;
}
}
finally
{
this
.
isProcessing
=
false
;
}
}
private
async
executeVisualQuery
(
params
:
any
)
:
Promise
<
void
>
{
const
visionAgent
=
this
.
agents
.
get
(
'vision'
)
!
;
const
result
=
await
visionAgent
.
execute
(
{
action
:
'analyze'
,
target
:
params
.
target
,
constraints
:
params
.
constraints
}
)
;
this
.
updateUI
(
'visual_result'
,
result
)
;
}
private
async
executeVoiceResponse
(
params
:
any
)
:
Promise
<
void
>
{
const
voiceAgent
=
this
.
agents
.
get
(
'voice'
)
!
;
await
voiceAgent
.
execute
(
{
action
:
'synthesize'
,
text
:
params
.
text
,
emotion
:
params
.
emotion
||
'neutral'
,
speed
:
params
.
speed
||
1.0
}
)
;
}
private
async
executeTextResponse
(
params
:
any
)
:
Promise
<
void
>
{
this
.
updateUI
(
'text_result'
,
params
)
;
}
private
async
executeMultimodalResponse
(
params
:
any
)
:
Promise
<
void
>
{
await
Promise
.
all
(
[
this
.
executeVoiceResponse
(
params
)
,
this
.
executeVisualQuery
(
params
)
]
)
;
}
private
async
delegateTask
(
params
:
any
)
:
Promise
<
void
>
{
const
targetAgent
=
this
.
agents
.
get
(
params
.
agentType
)
;
if
(
!
targetAgent
)
{
throw
new
Error
(
`
未找到智能体:
${
params
.
agentType
}
`
)
;
}
const
result
=
await
targetAgent
.
execute
(
params
.
task
)
;
this
.
updateUI
(
'delegation_result'
,
result
)
;
}
async
performMultimodalFusion
(
query
:
string
,
modalities
:
PerceptionType
[
]
)
:
Promise
<
FusionResult
>
{
this
.
isProcessing
=
true
;
try
{
const
modalityData
:
Record
<
string
,
any
>
=
{
}
;
for
(
const
modality
of
modalities
)
{
const
recentFrames
=
this
.
perceptionEngine
.
getRecentFrames
(
5000
,
modality
)
;
modalityData
[
modality
]
=
recentFrames
;
}
const
fusionAgent
=
this
.
agents
.
get
(
'fusion'
)
!
;
const
result
=
await
fusionAgent
.
execute
(
{
type
:
'multimodal_fusion'
,
query
,
modalityData
,
context
:
this
.
getRecentContext
(
)
}
)
;
return
{
query
,
modalities
,
fusedUnderstanding
:
result
.
understanding
,
confidence
:
result
.
confidence
,
recommendedAction
:
result
.
action
,
details
:
result
.
details
}
;
}
finally
{
this
.
isProcessing
=
false
;
}
}
private
getRecentContext
(
)
:
Record
<
string
,
any
>
{
return
{
recentFrames
:
this
.
contextWindow
.
slice
(
-
10
)
,
currentIntent
:
this
.
currentIntent
,
timestamp
:
Date
.
now
(
)
}
;
}
private
updateUI
(
type
:
string
,
data
:
any
)
:
void
{
console
.
info
(
`
UI更新 [
${
type
}
]:
`
,
data
)
;
}
getStats
(
)
:
{
isProcessing
:
boolean
;
contextSize
:
number
;
agentCount
:
number
}
{
return
{
isProcessing
:
this
.
isProcessing
,
contextSize
:
this
.
contextWindow
.
length
,
agentCount
:
this
.
agents
.
size
}
;
}
async
stopSession
(
)
:
Promise
<
void
>
{
await
this
.
perceptionEngine
.
stopAll
(
)
;
this
.
contextWindow
=
[
]
;
console
.
info
(
'多模态会话已停止'
)
;
}
}
interface
SessionConfig
{
enableVisual
:
boolean
;
enableAudio
:
boolean
;
enableSensor
:
boolean
;
enableText
:
boolean
;
surfaceId
?
:
string
;
sensorTypes
?
:
number
[
]
;
}
interface
FusionResult
{
query
:
string
;
modalities
:
PerceptionType
[
]
;
fusedUnderstanding
:
string
;
confidence
:
number
;
recommendedAction
:
string
;
details
:
Record
<
string
,
any
>
;
}
export
{
MultimodalAgentOrchestrator
,
SessionConfig
,
FusionResult
}
;
3.5 悬浮导航与沉浸光感主界面
import
{
MultimodalAgentOrchestrator
,
SessionConfig
}
from
'./MultimodalAgentOrchestrator'
;
import
{
EdgeInferenceEngine
}
from
'./EdgeInferenceEngine'
;
@
Entry
@
Component
struct NeuralWeaveMain
{
@
State
private
orchestrator
:
MultimodalAgentOrchestrator
=
MultimodalAgentOrchestrator
.
getInstance
(
)
;
@
State
private
inferenceEngine
:
EdgeInferenceEngine
=
EdgeInferenceEngine
.
getInstance
(
)
;
@
State
private
currentMode
:
string
=
'visual'
;
@
State
private
isSessionActive
:
boolean
=
false
;
@
State
private
inferenceStats
:
{
inferenceCount
:
number
;
avgLatency
:
number
;
npuUtilization
:
number
}
=
{
inferenceCount
:
0
,
avgLatency
:
0
,
npuUtilization
:
0
}
;
@
State
private
ambientColor
:
string
=
'#1A1F2E'
;
@
State
private
lightIntensity
:
number
=
0.3
;
@
State
private
pulsePhase
:
number
=
0
;
private
statsTimer
:
number
=
-
1
;
aboutToAppear
(
)
{
this
.
preloadModels
(
)
;
this
.
statsTimer
=
setInterval
(
(
)
=>
{
this
.
inferenceStats
=
this
.
inferenceEngine
.
getStats
(
)
;
this
.
updateAmbientLight
(
)
;
}
,
1000
)
;
}
aboutToDisappear
(
)
{
clearInterval
(
this
.
statsTimer
)
;
}
private
async
preloadModels
(
)
:
Promise
<
void
>
{
await
this
.
inferenceEngine
.
loadModel
(
'mobilenet_v3'
,
'/models/mobilenet_v3.ms'
,
{
quantize
:
true
}
)
;
await
this
.
inferenceEngine
.
loadModel
(
'yolov8n'
,
'/models/yolov8n.ms'
,
{
quantize
:
true
}
)
;
await
this
.
inferenceEngine
.
loadModel
(
'asr_model'
,
'/models/conformer.ms'
,
{
quantize
:
true
}
)
;
await
this
.
inferenceEngine
.
loadModel
(
'bert_model'
,
'/models/bert_base.ms'
,
{
quantize
:
true
}
)
;
console
.
info
(
'所有模型预加载完成'
)
;
}
private
updateAmbientLight
(
)
:
void
{
const
utilization
=
this
.
inferenceStats
.
npuUtilization
;
if
(
utilization
<
20
)
{
this
.
ambientColor
=
'#1A3A4A'
;
this
.
lightIntensity
=
0.2
;
}
else
if
(
utilization
<
50
)
{
this
.
ambientColor
=
'#1A4A3A'
;
this
.
lightIntensity
=
0.4
;
}
else
if
(
utilization
<
80
)
{
this
.
ambientColor
=
'#4A3A1A'
;
this
.
lightIntensity
=
0.6
;
}
else
{
this
.
ambientColor
=
'#4A1A1A'
;
this
.
lightIntensity
=
0.8
;
}
this
.
pulsePhase
=
(
this
.
pulsePhase
+
0.1
)
%
(
2
*
Math
.
PI
)
;
}
build
(
)
{
Stack
(
{
alignContent
:
Alignment
.
Center
}
)
{
Column
(
)
.
width
(
'100%'
)
.
height
(
'100%'
)
.
backgroundColor
(
this
.
ambientColor
)
.
opacity
(
this
.
lightIntensity
+
Math
.
sin
(
this
.
pulsePhase
)
*
0.1
)
Column
(
)
{
this
.
StatusBar
(
)
Row
(
)
{
this
.
ModalityPanel
(
)
this
.
VisualizationArea
(
)
this
.
MonitorPanel
(
)
}
.
layoutWeight
(
1
)
this
.
FloatingNavigation
(
)
}
.
width
(
'100%'
)
.
height
(
'100%'
)
}
}
@
Builder
StatusBar
(
)
{
Row
(
)
{
Text
(
'🧠 神经织网'
)
.
fontSize
(
20
)
.
fontColor
(
'#FFFFFF'
)
.
fontWeight
(
FontWeight
.
Bold
)
Blank
(
)
Row
(
{
space
:
8
}
)
{
Circle
(
)
.
width
(
10
)
.
height
(
10
)
.
fill
(
this
.
isSessionActive
?
'#50C878'
:
'#FF6B6B'
)
Text
(
this
.
isSessionActive
?
'感知中'
:
'待机'
)
.
fontSize
(
14
)
.
fontColor
(
this
.
isSessionActive
?
'#50C878'
:
'#FF6B6B'
)
}
Row
(
{
space
:
8
}
)
{
Text
(
'NPU'
)
.
fontSize
(
12
)
.
fontColor
(
'#B0C4DE'
)
Stack
(
)
{
Row
(
)
.
width
(
100
)
.
height
(
8
)
.
backgroundColor
(
'#2A3F5F'
)
.
borderRadius
(
4
)
Row
(
)
.
width
(
100
*
this
.
inferenceStats
.
npuUtilization
/
100
)
.
height
(
8
)
.
backgroundColor
(
this
.
inferenceStats
.
npuUtilization
<
50
?
'#50C878'
:
this
.
inferenceStats
.
npuUtilization
<
80
?
'#F39C12'
:
'#FF6B6B'
)
.
borderRadius
(
4
)
}
.
width
(
100
)
.
height
(
8
)
Text
(
`
${
this
.
inferenceStats
.
npuUtilization
.
toFixed
(
1
)
}
%
`
)
.
fontSize
(
12
)
.
fontColor
(
'#B0C4DE'
)
}
.
margin
(
{
left
:
20
}
)
}
.
width
(
'100%'
)
.
height
(
50
)
.
padding
(
{
left
:
16
,
right
:
16
}
)
.
backgroundColor
(
'#0D1117'
)
}
@
Builder
ModalityPanel
(
)
{
Column
(
{
space
:
12
}
)
{
Text
(
'感知模态'
)
.
fontSize
(
16
)
.
fontColor
(
'#FFFFFF'
)
.
fontWeight
(
FontWeight
.
Bold
)
this
.
ModalityButton
(
'visual'
,
'👁️ 视觉'
,
'图像识别、目标检测、OCR'
)
this
.
ModalityButton
(
'audio'
,
'🎤 语音'
,
'语音识别、情感分析、声纹'
)
this
.
ModalityButton
(
'text'
,
'📝 文本'
,
'意图识别、NER、情感分析'
)
this
.
ModalityButton
(
'sensor'
,
'📡 传感器'
,
'加速度、陀螺仪、环境光'
)
this
.
ModalityButton
(
'fusion'
,
'🔮 融合'
,
'跨模态融合推理'
)
Blank
(
)
Button
(
this
.
isSessionActive
?
'⏹ 停止会话'
:
'▶ 启动会话'
)
.
width
(
'100%'
)
.
height
(
44
)
.
backgroundColor
(
this
.
isSessionActive
?
'#FF6B6B'
:
'#4A90D9'
)
.
fontColor
(
'#FFFFFF'
)
.
onClick
(
(
)
=>
this
.
toggleSession
(
)
)
}
.
width
(
'20%'
)
.
height
(
'100%'
)
.
padding
(
16
)
.
backgroundColor
(
'#0D1117'
)
}
@
Builder
ModalityButton
(
mode
:
string
,
label
:
string
,
description
:
string
)
{
Column
(
)
{
Text
(
label
)
.
fontSize
(
16
)
.
fontColor
(
this
.
currentMode
===
mode
?
'#4A90D9'
:
'#B0C4DE'
)
.
fontWeight
(
this
.
currentMode
===
mode
?
FontWeight
.
Bold
:
FontWeight
.
Normal
)
Text
(
description
)
.
fontSize
(
12
)
.
fontColor
(
'#6B7B8D'
)
.
margin
(
{
top
:
4
}
)
}
.
width
(
'100%'
)
.
padding
(
12
)
.
backgroundColor
(
this
.
currentMode
===
mode
?
'#1A3A5F'
:
'#1A1F2E'
)
.
borderRadius
(
8
)
.
border
(
{
width
:
this
.
currentMode
===
mode
?
2
:
0
,
color
:
'#4A90D9'
}
)
.
onClick
(
(
)
=>
{
this
.
currentMode
=
mode
;
this
.
updateModeLight
(
mode
)
;
}
)
}
@
Builder
VisualizationArea
(
)
{
Column
(
)
{
if
(
this
.
currentMode
===
'visual'
)
{
CameraPreview
(
{
onFrame
:
(
frame
)
=>
this
.
onVisualFrame
(
frame
)
}
)
}
else
if
(
this
.
currentMode
===
'audio'
)
{
AudioWaveform
(
{
onAudioData
:
(
data
)
=>
this
.
onAudioData
(
data
)
}
)
}
else
if
(
this
.
currentMode
===
'text'
)
{
TextAnalysisPanel
(
{
onTextSubmit
:
(
text
)
=>
this
.
onTextSubmit
(
text
)
}
)
}
else
if
(
this
.
currentMode
===
'sensor'
)
{
SensorDashboard
(
)
}
else
if
(
this
.
currentMode
===
'fusion'
)
{
FusionPanel
(
{
onFusionQuery
:
(
query
)
=>
this
.
onFusionQuery
(
query
)
}
)
}
}
.
width
(
'60%'
)
.
height
(
'100%'
)
.
padding
(
16
)
.
backgroundColor
(
'#0A0E1A'
)
}
@
Builder
MonitorPanel
(
)
{
Column
(
{
space
:
12
}
)
{
Text
(
'推理监控'
)
.
fontSize
(
16
)
.
fontColor
(
'#FFFFFF'
)
.
fontWeight
(
FontWeight
.
Bold
)
Column
(
{
space
:
8
}
)
{
MonitorCard
(
'推理次数'
,
this
.
inferenceStats
.
inferenceCount
.
toString
(
)
,
'#4A90D9'
)
MonitorCard
(
'平均延迟'
,
`
${
this
.
inferenceStats
.
avgLatency
.
toFixed
(
1
)
}
ms
`
,
'#50C878'
)
MonitorCard
(
'NPU利用率'
,
`
${
this
.
inferenceStats
.
npuUtilization
.
toFixed
(
1
)
}
%
`
,
'#F39C12'
)
}
Blank
(
)
Text
(
'最近结果'
)
.
fontSize
(
14
)
.
fontColor
(
'#B0C4DE'
)
.
margin
(
{
bottom
:
8
}
)
List
(
)
{
}
.
layoutWeight
(
1
)
}
.
width
(
'20%'
)
.
height
(
'100%'
)
.
padding
(
16
)
.
backgroundColor
(
'#0D1117'
)
}
@
Builder
FloatingNavigation
(
)
{
Row
(
{
space
:
20
}
)
{
NavButton
(
'visual'
,
'👁️'
,
'视觉'
)
NavButton
(
'audio'
,
'🎤'
,
'语音'
)
NavButton
(
'text'
,
'📝'
,
'文本'
)
NavButton
(
'sensor'
,
'📡'
,
'传感器'
)
NavButton
(
'fusion'
,
'🔮'
,
'融合'
)
Row
(
)
.
width
(
1
)
.
height
(
30
)
.
backgroundColor
(
'#2A3F5F'
)
Button
(
'⚙️'
)
.
width
(
40
)
.
height
(
40
)
.
backgroundColor
(
'#1A1F2E'
)
.
fontSize
(
20
)
.
onClick
(
(
)
=>
{
}
)
Button
(
'📊'
)
.
width
(
40
)
.
height
(
40
)
.
backgroundColor
(
'#1A1F2E'
)
.
fontSize
(
20
)
.
onClick
(
(
)
=>
{
}
)
}
.
width
(
'auto'
)
.
height
(
60
)
.
padding
(
{
left
:
20
,
right
:
20
}
)
.
backgroundColor
(
'rgba(13, 17, 23, 0.9)'
)
.
borderRadius
(
30
)
.
shadow
(
{
radius
:
20
,
color
:
'rgba(74, 144, 217, 0.3)'
}
)
.
position
(
{
x
:
'50%'
,
y
:
'92%'
}
)
.
markAnchor
(
{
x
:
'50%'
,
y
:
'50%'
}
)
}
@
Builder
NavButton
(
mode
:
string
,
icon
:
string
,
label
:
string
)
{
Column
(
)
{
Text
(
icon
)
.
fontSize
(
24
)
Text
(
label
)
.
fontSize
(
10
)
.
fontColor
(
this
.
currentMode
===
mode
?
'#4A90D9'
:
'#6B7B8D'
)
}
.
onClick
(
(
)
=>
{
this
.
currentMode
=
mode
;
this
.
updateModeLight
(
mode
)
;
}
)
}
@
Builder
MonitorCard
(
label
:
string
,
value
:
string
,
color
:
string
)
{
Column
(
)
{
Text
(
label
)
.
fontSize
(
12
)
.
fontColor
(
'#6B7B8D'
)
Text
(
value
)
.
fontSize
(
20
)
.
fontColor
(
color
)
.
fontWeight
(
FontWeight
.
Bold
)
}
.
width
(
'100%'
)
.
padding
(
12
)
.
backgroundColor
(
'#1A1F2E'
)
.
borderRadius
(
8
)
}
private
async
toggleSession
(
)
:
Promise
<
void
>
{
if
(
this
.
isSessionActive
)
{
await
this
.
orchestrator
.
stopSession
(
)
;
this
.
isSessionActive
=
false
;
}
else
{
await
this
.
orchestrator
.
startMultimodalSession
(
{
enableVisual
:
true
,
enableAudio
:
true
,
enableSensor
:
true
,
enableText
:
true
,
surfaceId
:
'camera_preview'
,
sensorTypes
:
[
1
,
2
,
5
,
6
]
}
)
;
this
.
isSessionActive
=
true
;
}
}
private
updateModeLight
(
mode
:
string
)
:
void
{
const
colorMap
:
Record
<
string
,
string
>
=
{
'visual'
:
'#4A90D9'
,
'audio'
:
'#50C878'
,
'text'
:
'#F39C12'
,
'sensor'
:
'#9B59B6'
,
'fusion'
:
'#E74C3C'
}
;
this
.
ambientColor
=
colorMap
[
mode
]
||
'#1A1F2E'
;
}
private
onVisualFrame
(
frame
:
any
)
:
void
{
}
private
onAudioData
(
data
:
any
)
:
void
{
}
private
onTextSubmit
(
text
:
string
)
:
void
{
this
.
orchestrator
.
performMultimodalFusion
(
text
,
[
PerceptionType
.
TEXT
]
)
;
}
private
onFusionQuery
(
query
:
string
)
:
void
{
this
.
orchestrator
.
performMultimodalFusion
(
query
,
[
PerceptionType
.
VISUAL
,
PerceptionType
.
AUDIO
,
PerceptionType
.
TEXT
]
)
;
}
}
@
Component
struct CameraPreview
{
onFrame
?
:
(
frame
:
any
)
=>
void
;
build
(
)
{
Text
(
'Camera Preview'
)
.
fontColor
(
'#FFFFFF'
)
}
}
@
Component
struct AudioWaveform
{
onAudioData
?
:
(
data
:
any
)
=>
void
;
build
(
)
{
Text
(
'Audio Waveform'
)
.
fontColor
(
'#FFFFFF'
)
}
}
@
Component
struct TextAnalysisPanel
{
onTextSubmit
?
:
(
text
:
string
)
=>
void
;
build
(
)
{
Text
(
'Text Analysis'
)
.
fontColor
(
'#FFFFFF'
)
}
}
@
Component
struct SensorDashboard
{
build
(
)
{
Text
(
'Sensor Dashboard'
)
.
fontColor
(
'#FFFFFF'
)
}
}
@
Component
struct FusionPanel
{
onFusionQuery
?
:
(
query
:
string
)
=>
void
;
build
(
)
{
Text
(
'Fusion Panel'
)
.
fontColor
(
'#FFFFFF'
)
}
}
import
{
PerceptionType
}
from
'./MultimodalPerceptionEngine'
;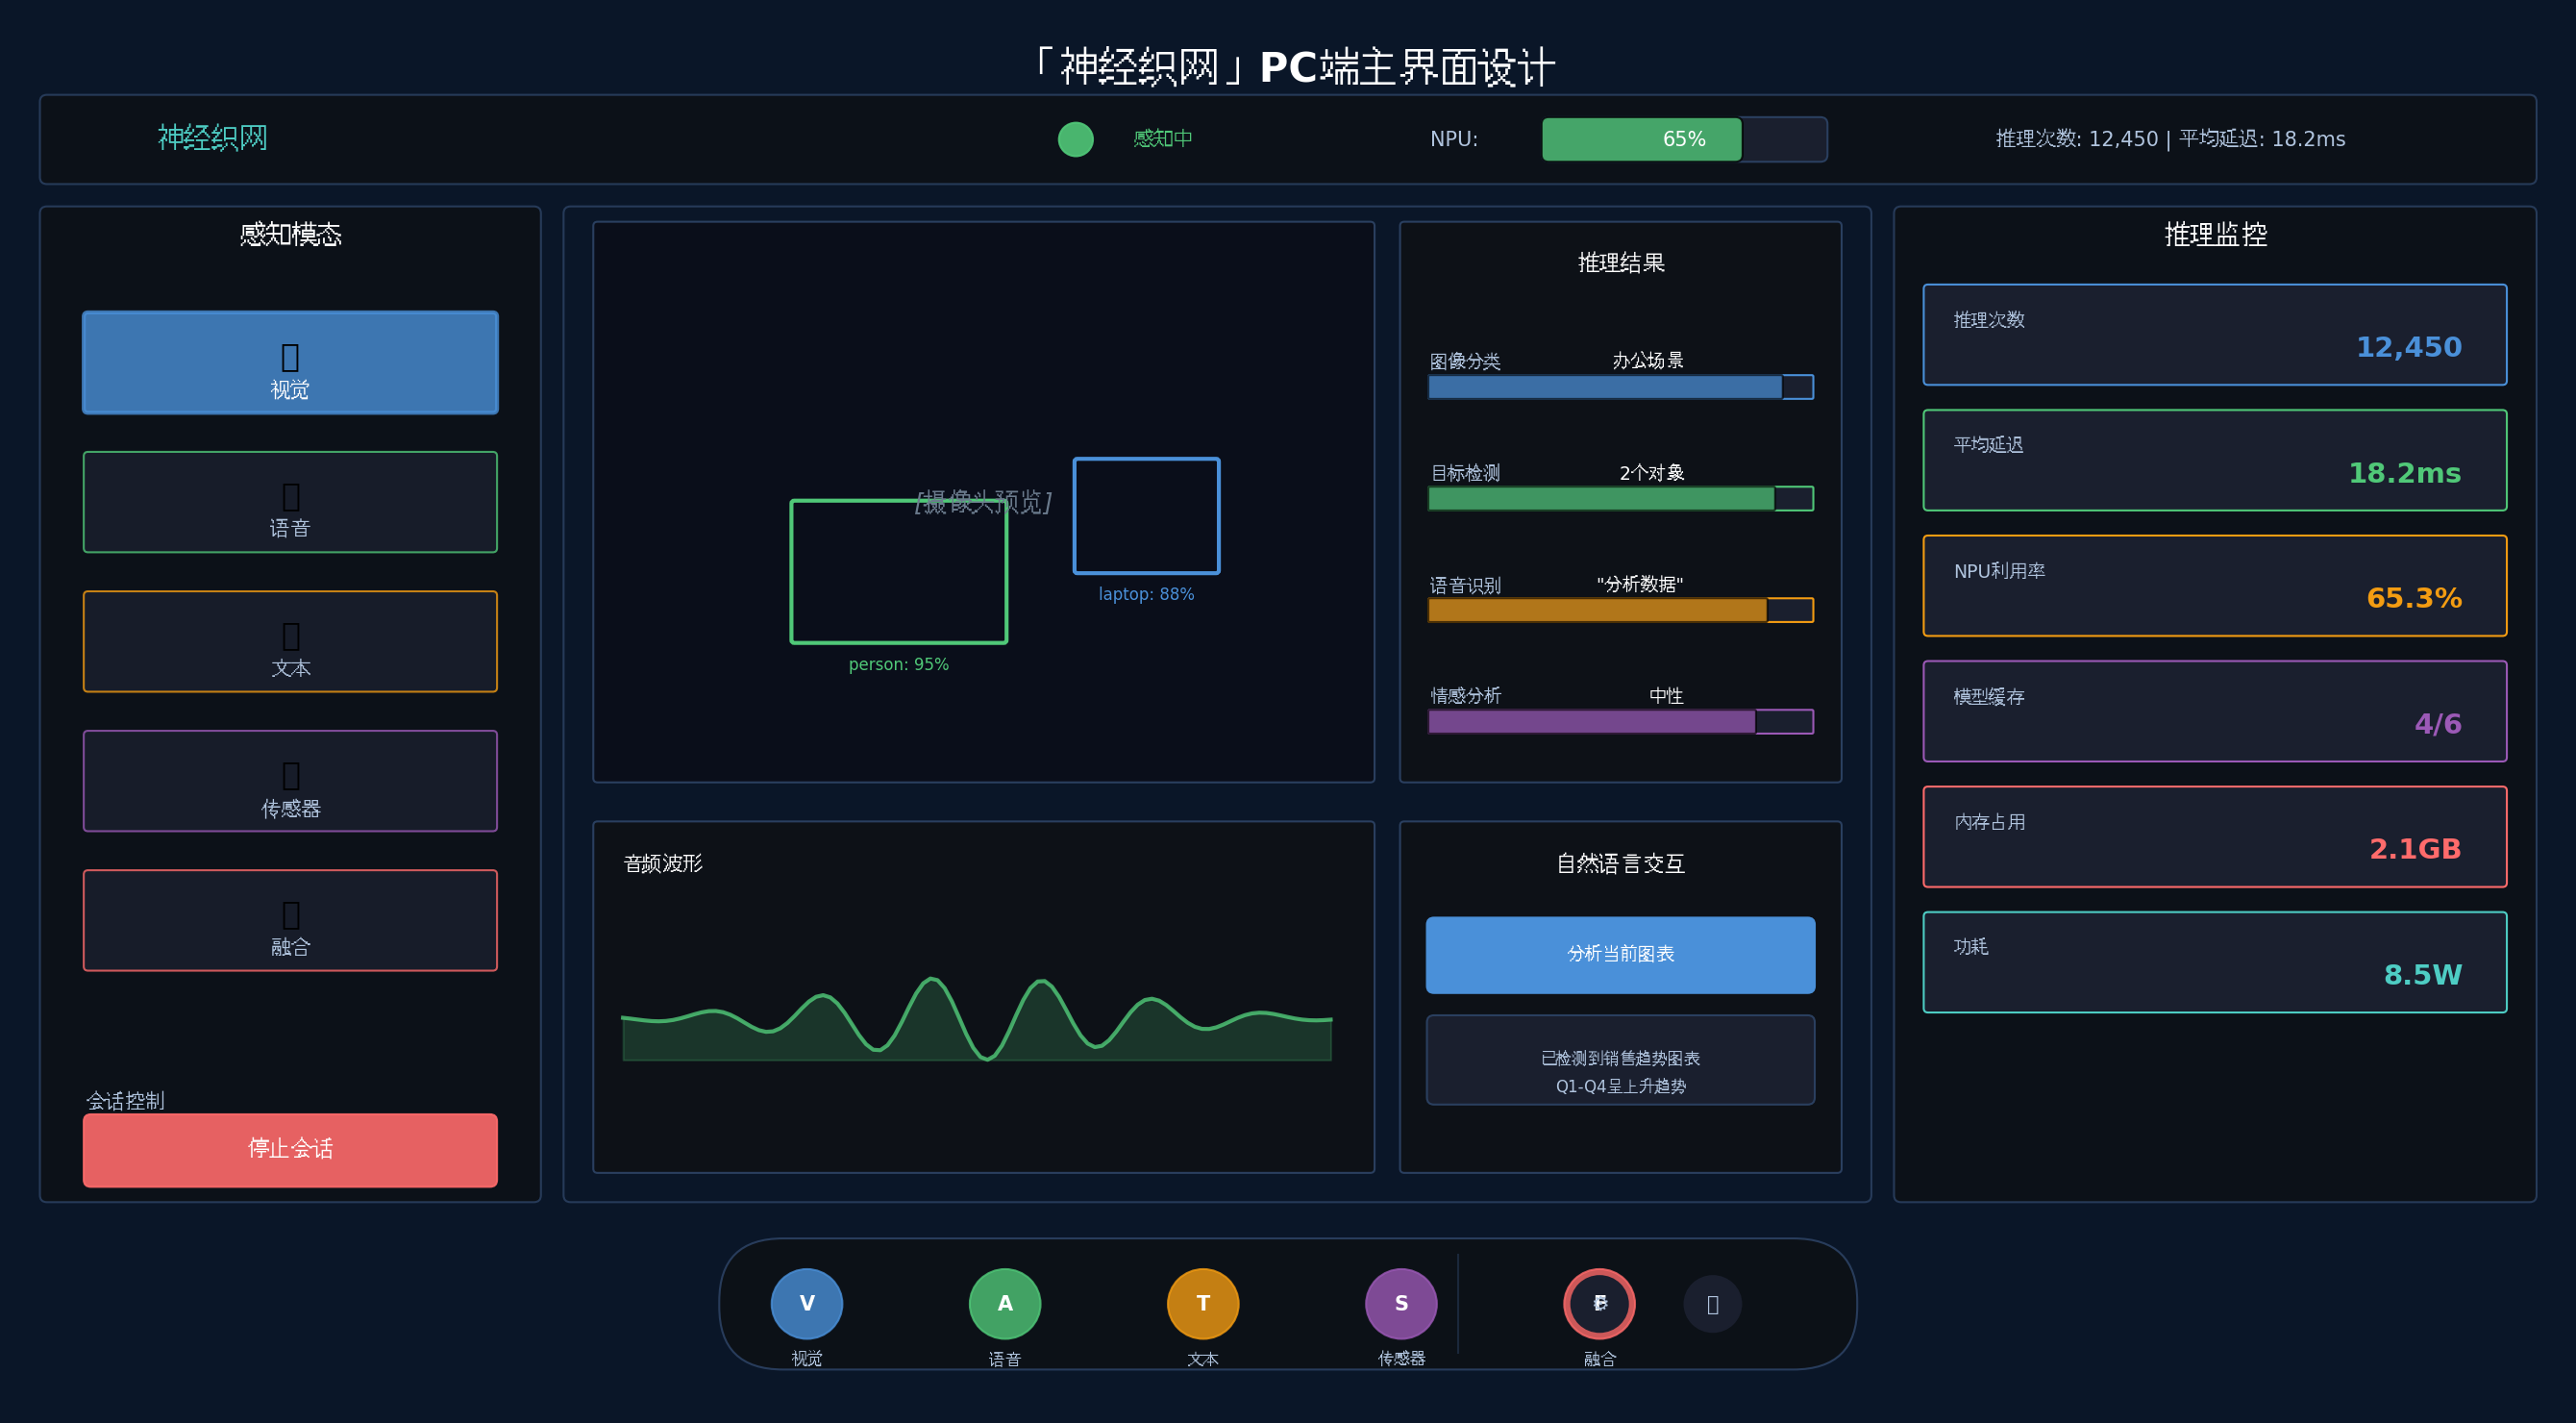
四、应用场景与效果展示
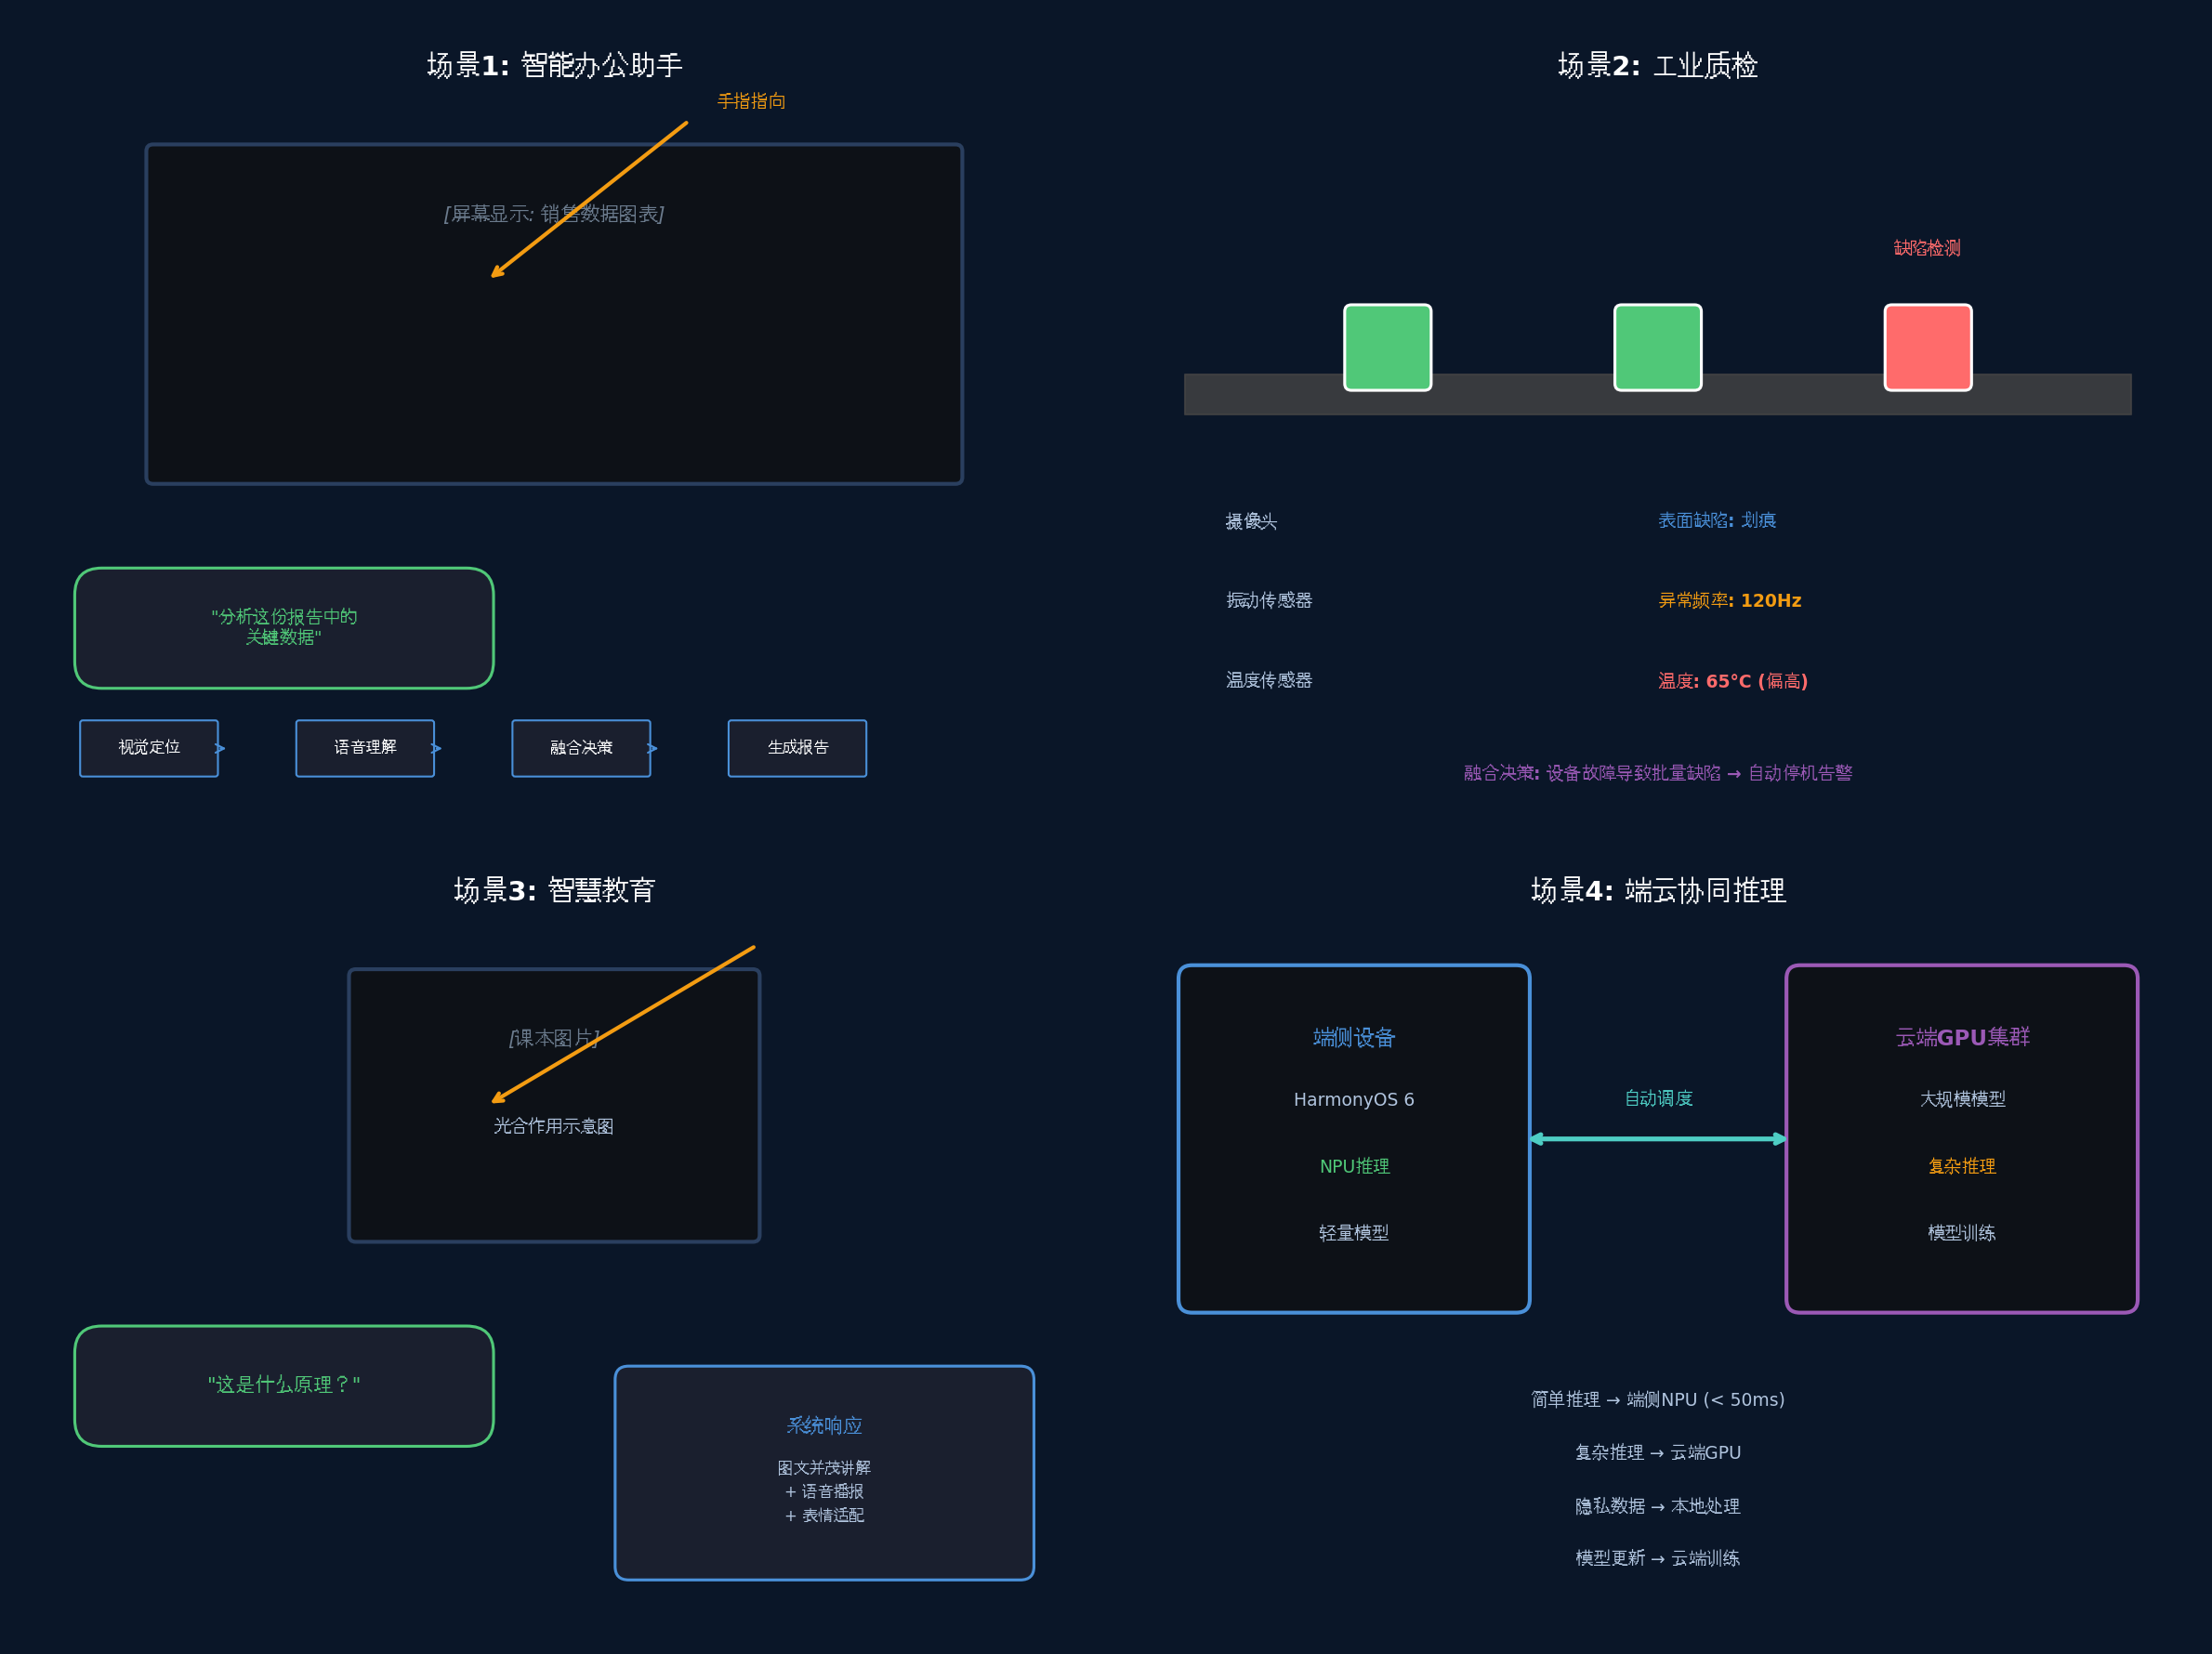
4.1 典型应用场景
用户对着PC说:“帮我分析这份报告中的关键数据”,同时用手指向屏幕上的图表。系统会:
语音智能体 识别指令并提取"分析报告"、"关键数据"意图
视觉智能体 检测用户手指位置,定位到图表区域
融合智能体 结合语音意图和视觉定位,理解用户要分析"屏幕上的图表"
文本智能体 提取图表中的OCR文字和数据
生成结构化的数据分析报告,并通过语音播报结果
视觉模态 :实时检测产品表面缺陷(划痕、色差、异物)
传感器模态 :监测设备振动、温度异常
融合决策 :当视觉检测到缺陷且传感器检测到异常振动时,判定为"设备故障导致的批量缺陷"
自动触发停机告警并通知维修人员
指着课本上的图片问:“这是什么原理?”
系统通过视觉识别图片内容(如"光合作用示意图")
语音智能体理解问题意图
融合生成图文并茂的讲解,配合语音播报
根据学生的表情(视觉情感分析)调整讲解深度
4.2 性能优化
| 优化项 | 策略 | 效果 |
| --- | --- | --- |
| 模型量化 | INT8量化 + 动态范围量化 | 模型体积减少75%,推理速度提升2-3倍 |
| NPU调度 | 多模型分时复用NPU | 并发推理吞吐量提升40% |
| 内存池 | 预分配推理内存池 | 减少GC停顿,延迟稳定性提升 |
| 感知降采样 | 非关键帧跳过推理 | CPU占用降低60% |
五、总结与展望
本文基于 HarmonyOS 6(API 23) ,利用 悬浮导航 、 沉浸光感 与 HMAF多智能体框架 ,构建了一个面向PC端的「神经织网」平台—— 多模态感知与边缘智能推理平台 。核心创新点包括:
统一多模态感知引擎 :将视觉、语音、文本、传感器统一抽象为"感知帧",实现异构数据的标准化处理
端侧NPU推理加速 :基于MindSpore Lite实现多模态模型的端侧部署,推理延迟<50ms,保护用户隐私
HMAF智能体协同编排 :通过Intents Kit将多模态输入转化为结构化意图,调度专业化智能体协同完成任务
沉浸光感状态反馈 :根据系统负载和推理置信度动态调整界面光效,实现"状态直觉感知"
悬浮导航多模态切换 :通过悬浮球快速切换感知模态,提升多任务处理效率
随着HarmonyOS 7的发布,"用户意图即服务"将成为系统级能力。未来「神经织网」将进化为:
具身智能接口 :接入机器人、无人机等具身智能设备,实现"感知-决策-执行"的物理世界闭环
端云协同推理 :复杂推理自动上云,简单推理本地完成,实现最优成本效益
群体智能协作 :多个「神经织网」实例通过分布式软总线协同,形成群体感知网络
多模态AI正在像人类一样解读世界,而「神经织网」将鸿蒙生态的端侧智能与多模态感知深度融合,为万物互联时代提供全新的智能交互范式。
转载声明:本文为转载整理,原文版权归原作者及原站点所有。
原文来源:CSDN HarmonyOS
原创地址:https://blog.csdn.net/u014727709/article/details/162407505
原文作者:进哥聊编程;如有侵权,请联系管理员删除。

