【Rust日报】2021-01-14 rustdoc的性能有了很大的提升!
在过去四个月,rustdoc的性能有了很大的提升!
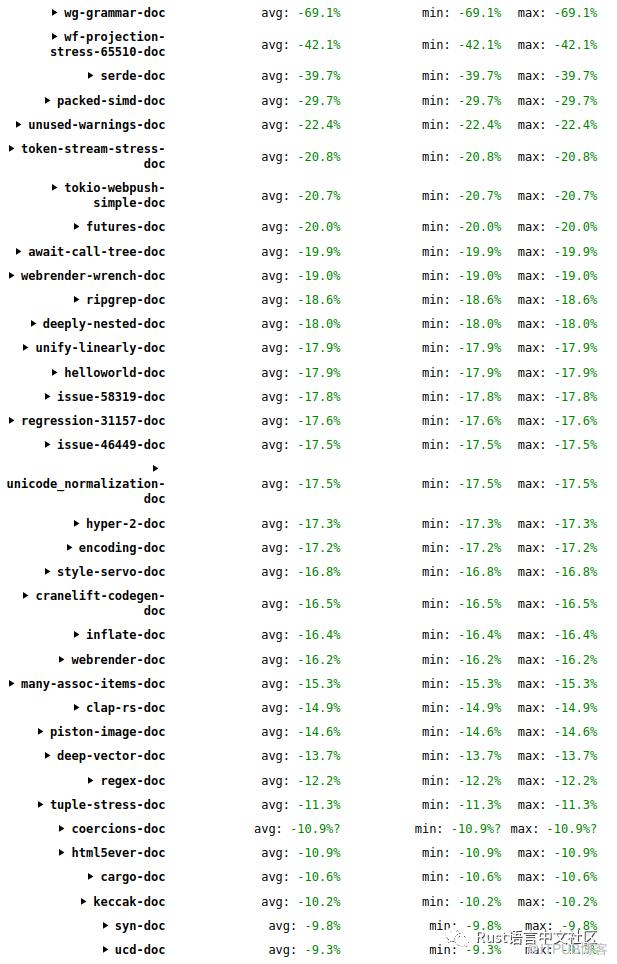
据jynelson回复,在接下来的几天,他将要发表一篇博客,给大家介绍这些性能提升是来自哪些地方。
Read
More: https://www.reddit.com/r/rust/comments/kwlpv3/great_improvement_in_rustdoc_performance_in_the/
Rust 书籍宝库
glynnormington整理了网络上大部分有关rust的mdbook,有官方的,也有非官方的。值得注意的一点是大家关注的rust宏小册很多人以为一直没有更新,但是其实有另一个团队重新在原来的基础上,更新了新的版本,目前已收录到该书库中。
Rust 书记宝库: https://lborb.github.io/book/title-page.html
Read More: https://www.reddit.com/r/rust/comments/kwiwb8/the_little_book_of_rust_books/
Ultron - 由rust编写的基于web的文本编辑器
Ultron是基于Web的单空间文本编辑器,具有语法突出显示功能,完全用rust编写。
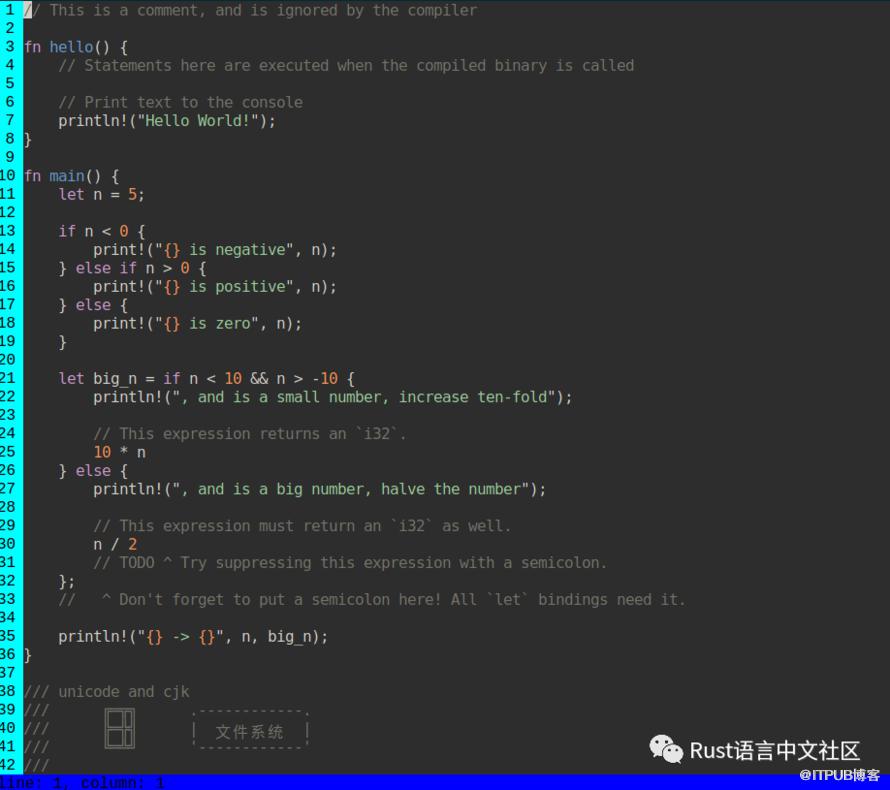
Github: https://github.com/ivanceras/ultron
为什么Iterator::any和Iterator::filter期望不同的闭包?
原帖主在使用迭代器的过程中,发现这两个api期望的闭包参数不一致:
fn any<F>(&mut self, f: F) -> boolwhereF: FnMut(Self::Item) -> boolfn filter<P>(self, predicate: P) -> Filter<Self, P>whereP: FnMut(&Self::Item) -> bool
而且发现在使用过程中这样的差异会导致代码不好看:any:
vec![1, 0, 30].iter().any(|&x| x > 0)
filter:
vec![1, 0, 30].iter(). filter(|&&x| x > 0)
于是就在reddit上发帖询问这样设计的原由。
高赞回复:
因为any会消耗迭代器,所以在使用之后不需要返回迭代器中的项(这就是为什么它需要一个Self::Item)。对于filter,过滤之后仍然需要在后续操作中继续使用它的项,如果通过闭包消耗掉它们,后续就无法使用它的项了。所以它需要一个 &Self::Item,以便它可以在之后返回 Self::Item。(Sinceany will consume the iterator, it doesn't need to return the items init after use (which is why it takes a Self::Item). For filter, theresulting iterator still needs to return its items after use, and itcan't do that if it consumes them through the closure. So it takes an&Self::Item, so it can return Self::Item later.)Read More: https://www.reddit.com/r/rust/comments/kw91u1/why_do_iteratorany_and_iteratorfilter_expect/
小编私货
今天是新的一年里我第一次发日报,过去几个月都是用Downtime的花名参与,不过从新的一年里都用Cupnfish了,以后的日子里请大家多多指教。最近一直在尝试bevy,下下周发文之前希望自己也能顺便写个使用感受。
From 日报小组 Cupnfish Jancd
社区学习交流平台订阅:
Rust.cc 论坛: 支持 rss
微信公众号:Rust 语言学习交流
原文作者:Rust语言中文社区;如有侵权,请联系管理员删除。

