前言
在数据库的使用过程中,有很多场合是要自行去构造大规模数据,以供测试、性能功能验证使用。我在前边一文:PostgreSQL - 大规模随机数据生成方法里介绍了PostgreSQL中生成大规模随机数据的方法。这种方法,生成数据比较快,但是数据大多是对业务场景没有太大意义的数据,或者说对业务不够友好。
本文再介绍通过一些第三方库,插入一些相对友好的随机数据 。那就是通过Python faker库来生成数据 。Faker是一个Python软件包,可为您生成伪造数据。无论您是需要引导数据库,创建美观的XML文档,填充持久性以进行压力测试还是匿名化来自生产服务的数据,Faker都是您的理想之选之一。不论您这边需要创建多少条数据,无非是一个for循环就解决问题了。
实作
基本安装
使用pip安装即可 pip install Faker
pip -V
pip 21.3.1 from /usr/local/lib/python3.6/site-packages/pip (python 3.6)

pip install Faker
Defaulting to user installation because normal site-packages is not writeable
Collecting Faker
  Downloading Faker-14.2.1-py3-none-any.whl (1.6 MB)
     |████████████████████████████████| 1.6 MB 1.1 MB/s
Requirement already satisfied: typing-extensions>=3.7.4.3 in /usr/local/lib/python3.6/site-packages (from Faker) (4.1.1)
Requirement already satisfied: python-dateutil>=2.4 in /usr/local/lib/python3.6/site-packages (from Faker) (2.8.2)
Requirement already satisfied: six>=1.5 in /usr/local/lib/python3.6/site-packages (from python-dateutil>=2.4->Faker) (1.16.0)
Installing collected packages: Faker
........................
github地址:https://github.com/joke2k/faker 可以直接从tags里找到各个版本的Faker下载。https://github.com/joke2k/faker/tags
API简介
我们可以用dir(fake)查看一下,它能fake近300种东西出来,并且faker还支持上几十种语言简直不能太强大。
简单示例:
>>> from faker import Faker
>>> fake = Faker('zh_CN')
>>> fake.country()
'福克兰群岛'
>>> fake.country()
'日本'
>>> fake.country()
'以色列'
>>> fake.country()
'保加利亚'
>>> fake.country()
'马拉维'
下边以PostgreSQL数据库为例,看看如何用Faker方便的生成数据, 设有表:
 create table customer(id bigserial primary key, name varchar(32) not null, job varchar(64),
      company varchar(128), phone_num varchar(24), email varchar(128), address varchar(128));
下面我们可以用Faker直接造些数据.
方式一:直接生成数据文件
# -*- coding:utf-8 -*-

from faker import Faker

class DataGenerator(object):
    def __init__(self):
        # 选择中文
        fake = Faker('zh_CN')
        # 生成数据改变循环体来控制数据量rang(?)
        self.data_total = [
            [fake.name(), fake.job(), fake.company(), fake.phone_number(), fake.company_email(), fake.address(),
             fake.date_time(tzinfo=None)] for x in range(100)]
        print(self.data_total)
    # 写入txt
    def deal_txt(self):
        with open('data_total.txt', 'w', errors='ignore', encoding='utf-8') as output:
            output.write('name,job,company,phone_number,company_email,address\n')
            for row in self.data_total:
                rowtxt = '{},{},{},{},{},{}'.format(row[0], row[1], row[2], row[3], row[4], row[5], row[6])
                output.write(rowtxt)
                output.write('\n')
            output.close()
        print("Processing completed to txt")


if __name__ == '__main__':
    data = DataGenerator()
    data.deal_txt()
运行python3 datagen.py,我们打开数据文件:data_total.txt, 能看到100条数据:
name,job,company,phone_number,company_email,address
裴婷,产品专员,华泰通安科技有限公司,15540283808,weijin@guiyingyin.cn,江苏省潮州市和平深圳街f座 815057
陈成,激光/光电子技术,毕博诚网络有限公司,15983545054,xyan@xiuyingjing.cn,新疆维吾尔自治区莹市梁平毛街T座 733404
王兰英,水质检测员,创汇网络有限公司,13732772337,chao42@yansu.cn,浙江省哈尔滨县秀英深圳街g座 828060
陈秀梅,寻呼员/话务员,凌颖信息网络有限公司,15181833465,sgu@liyong.cn,宁夏回族自治区鹏县门头沟陈路W座 179856
...............
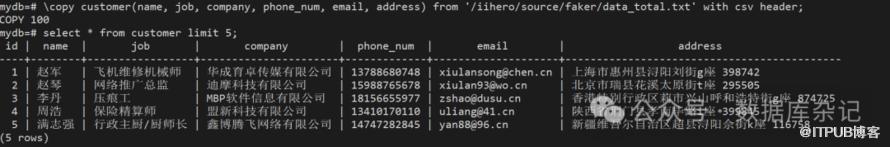
既然文件有了,使用\copy命令,可以秒入数据到表CUSTOMER中:
mydb=# \copy customer(name, job, company, phone_num, email, address) from '/iihero/source/faker/data_total.txt' with csv header;
COPY 100
看看效果:
方式二:直接边生成数据边入库
我们把上边的代码稍改动一下, 加入连接pg并入库的操作
pip3 install psycopg2-binary

# -*- coding:utf-8 -*-

from faker import Faker

import psycopg2

class DataGenerator(object):
    def __init__(self):
        # 选择中文
        fake = Faker('zh_CN')
        # 生成数据改变循环体来控制数据量rang(?)
        self.data_total = [
            [fake.name(), fake.job(), fake.company(), fake.phone_number(), fake.company_email(), fake.address(),
             fake.date_time(tzinfo=None)] for x in range(100)]
        print(self.data_total)
    # 写入txt
    def deal_txt(self):
        with open('data_total.txt', 'w', errors='ignore', encoding='utf-8') as output:
            output.write('name,job,company,phone_number,company_email,address\n')
            for row in self.data_total:
                rowtxt = '{},{},{},{},{},{}'.format(row[0], row[1], row[2], row[3], row[4], row[5])
                output.write(rowtxt)
                output.write('\n')
            output.close()
        print("Processing completed to txt")

    def deal_pg(self):
        # 打开数据库连接
        db = psycopg2.connect(database="mydb", user="mydb", password="test123", host="127.0.0.1", port="5555")
        print("Opened database successfully")
        # 使用cursor()方法获取操作游标
        cursor = db.cursor()
        # SQL 插入语句
        for val in self.data_total:
            sql = "insert into customer(name,job,company,phone_num,email,address) values ('%s','%s','%s','%s','%s','%s')" % (
                val[0], val[1], val[2], val[3], val[4], val[5])
            try:
                # 执行sql语句
                cursor.execute(sql)
                # 执行sql语句
                db.commit()
                print("insert ok")
            except(Exception, psycopg2.DatabaseError) as error:
                print(error)
                # 发生错误时回滚
                db.rollback()

        # 关闭数据库连接
        db.close()

    def deal_pg_direct(self):
        fake = Faker('zh_CN')
        # 打开数据库连接
        db = psycopg2.connect(database="mydb", user="mydb", password="test123", host="127.0.0.1", port="5555")
        print("Opened database successfully")
        # 使用cursor()方法获取操作游标
        cursor = db.cursor()
        # SQL 插入语句
        for x in range(1000):
            sql = "insert into customer(name,job,company,phone_num,email,address) values ('%s','%s','%s','%s','%s','%s')" % (
                fake.name(), fake.job(), fake.company(), fake.phone_number(), fake.company_email(), fake.address())
            try:
                # 执行sql语句
                cursor.execute(sql)
                # 执行sql语句
                db.commit()
                print("insert ok")
            except(Exception, psycopg2.DatabaseError) as error:
                print(error)
                # 发生错误时回滚
                db.rollback()
        # 关闭数据库连接
        db.close()

if __name__ == '__main__':
    data = DataGenerator()
    data.deal_pg()
我们先使用粗糙的deal_pg()方法,从内存的100条取出依次插入。你可以很顺利的看到100条插入到数据库当中。
优化一下,可以直接边fake数据边插入,那样内存开销极小。
当然,我们还可以进一步优化,就是每次插入绑定多条,那样性能还会好一些。本文的目的不在于此,在于快速生成数据的方法。
总结
Faker这个工具库,应该是一个通用的工具。对于某些DBMS缺乏必要的生成函数,我们可以用Faker快速生成较大规模的数据文件,然后一次性导入,也不失为一种方法。或者直接往库表里头灌入。
PostgreSQL又多了一种快速生成数据的方法,而且是对人友好可读的。
相关文档参考:
1、https://faker.readthedocs.io/en/master/
2、https://www.cnblogs.com/felixwang2/p/9246279.html (具体函数运用)
我是【Sean】, 欢迎大家长按关注公众号:数据库杂记。
相关文章导读:
1. PostgreSQL - 大规模随机数据生成方法
原文作者:数据库杂记;如有侵权,请联系管理员删除。

最新文章
- PostgreSQL Internals之路 Part-II 第10章 WAL日志
- 从Oracle过渡到PostgreSQL: 理解模式的概念
- PostgreSQL是Oracle的一个可行的替代方案——原因如下
- PostgreSQL Internals之路Part II: Buffer Cache和WAL第9章 Buffer Cache
- 天纵奇才 - "林诗栋"
- 没有PostgreSQL样例数据库,不用担心, 帮你搞定!
- 推荐几本数据库技术图书
- 由浅入深高可用:HAProxy + PostgreSQL配置逐步详解(二)
- PostgreSQL Internals之路 Part-I 第7,8章 冻结、重建表和索引
- 乒坛最新消息引发巨震 - 世界第一王楚钦惨败林诗栋,王曼昱0-4遭横扫,还有孙颖莎4-2稳胜张本美和
