Gemini 4 Argon 标志着物理理解、代码生成和视觉语义推理能力的跨越式提升——解锁了机器人技术栈中的全新工作流,并加速了迈向物理 AGI 的进程。
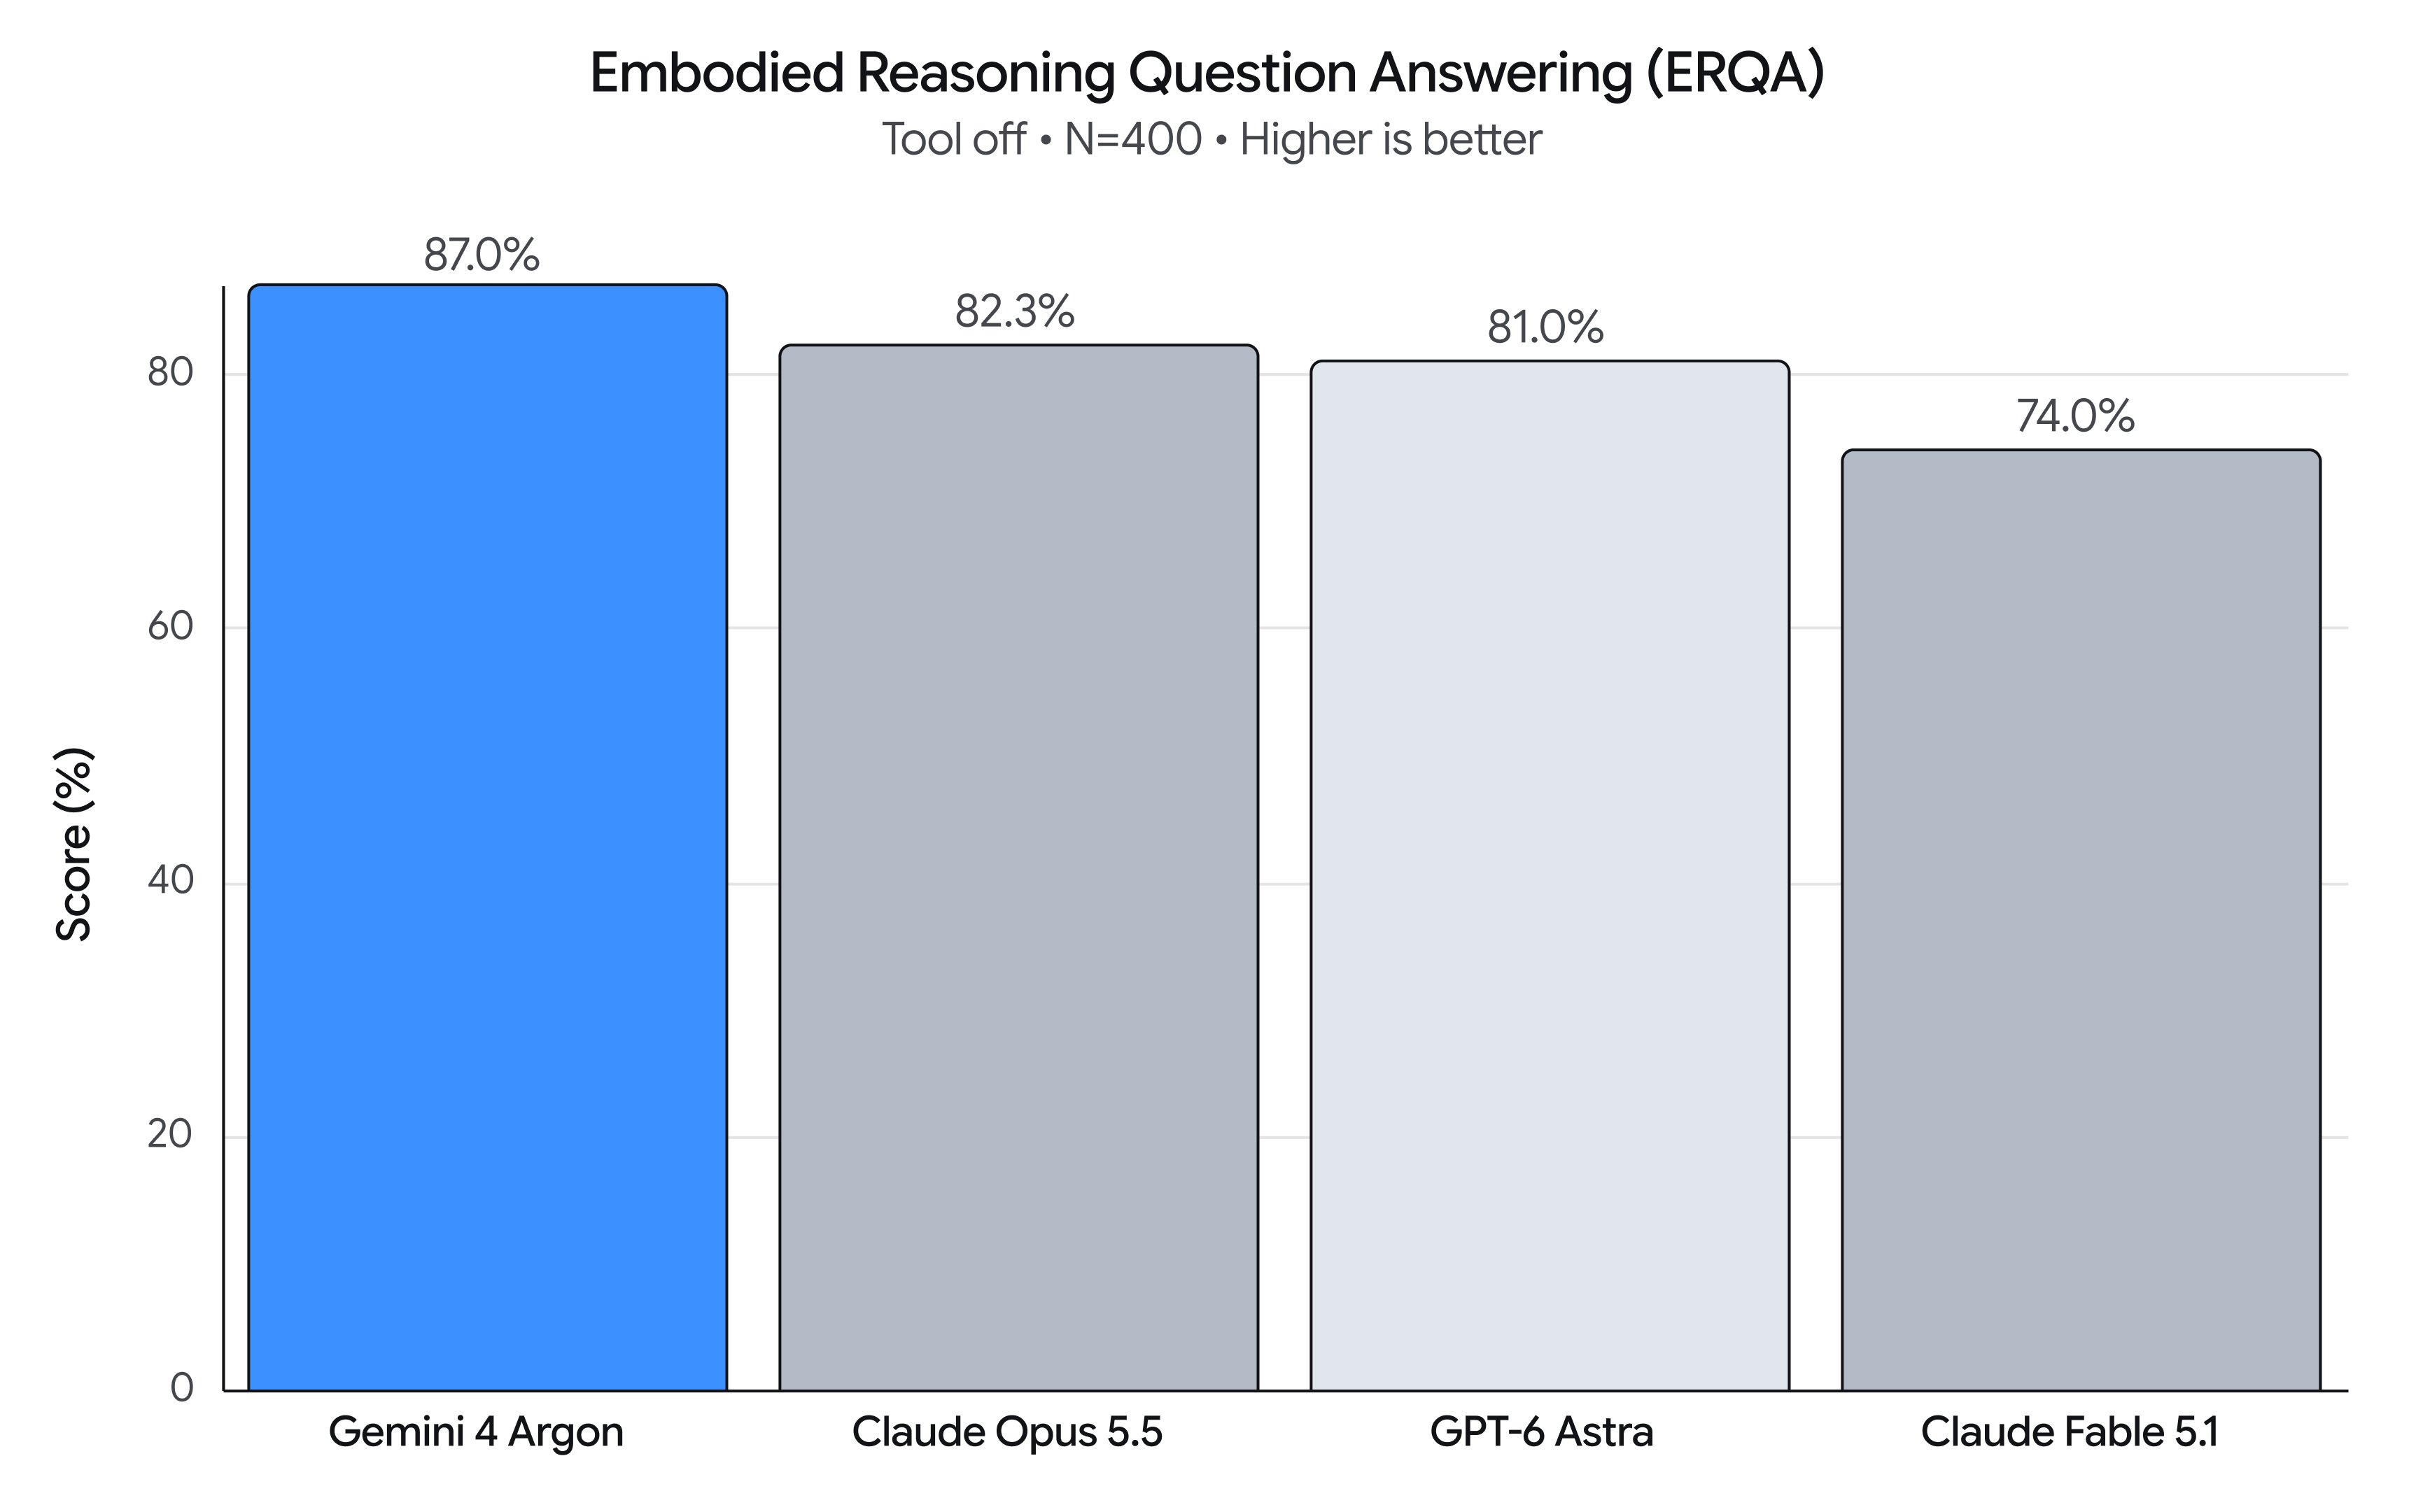
这一能力飞跃在 Embodied Reasoning (ERQA) 基准测试中得到了体现,该基准测试评估模型在 3D 环境中理解和解决物理、空间问题的能力。仅使用纯推理,Argon 就取得了 87% 的成绩,超越了所有其他前沿模型。
作为一个通用物理推理模型,Argon 可应用于整个机器人生命周期。在本文中,我们分享 Argon 在四个关键领域的代表性提示词:
机器人控制 → 通过 MuJoCo 练习进行移动操作、零样本机器人控制,以及视频世界模型的闭环引导。
Real2Sim → 从机器人摄像头画面、第一人称人类视频或手绘纸质草图中重建经过物理校准的仿真孪生体。
物理理解 → 智能体多模态事后标注,包括对灵巧性的详细理解、密集价值函数和进度估计。
研究与自我改进 → 通过仿真进行动作改进,以及在硬件上进行迭代式自我改进。
用 Argon 解锁机器人控制
1. Spot 移动操作:通过 MuJoCo 练习将垃圾投入垃圾桶
Argon 控制一台 Boston Dynamics Spot® 四足机器人(12 自由度腿部 + 6 自由度机械臂)学习一项新技能:踩下脚踏式垃圾桶的踏板,将易拉罐扔进垃圾桶。Argon 创建了一个脚踏式垃圾桶的铰接式 MuJoCo 数字孪生体,在踩下物理踏板并将易拉罐投入打开的垃圾桶之前先练习其动作。
There's a Diet Coke can behind you and another on the black table on your left.
Use the spot-mobile-manipulation skill to pick them up and trash them in the black foot-pedal bin.
Before stepping down on the pedal, verify in the front cameras that your front-right foot target is centered on the pedal, and use a 2-agent verification swarm (foot-verifier and hand-verifier) to verify both the foot-pedal step and the 3D hand-in-bin alignment before releasing.
2. 零样本控制
Argon 控制一个简单的机械臂,将一个倒下的杯子扶正,并将揉皱的餐巾纸放入其中。Argon 利用视觉坐标约束和动作原语进行推理,在多个回合中完成此任务。
[Attached: wrist_cam.png, obs.json]

Task: Get the robot arm to reorient the mug upright and put the napkin inside the mug.

## Execution Discipline
- Simply output 1 sentence observation followed immediately by your `curl` command (with `# Plan:` on Turn 1 and `# Thought:` on every turn). Everything needed is in `obs.json` and the calibrated reticle/grid drawn on `wrist_cam.png`.

## Visual Coordinate Reference (Annotated on wrist_cam.png)
- `+X` (UP in image): Away from robot base | `-X` (DOWN): Towards robot base
- `+Y` (LEFT in image): World left         | `-Y` (RIGHT): World right
- `+Z`: Height above table                | `Yellow numbers`: World (X, Y) in centimetres (2 cm grid at `grid_z`)
- `Cyan + crosshair`: Current 3D pinch center
- `Cyan [ + ] brackets`: Current jaw opening and closing line
- `Green line`: Current object long-axis orientation (`yaw_deg`: 0° = vertical along +X, 90° = horizontal along +Y)
- `pitch_deg = 90°`: Straight down (-Z) top-down grasp/place; `pitch_deg < 60°`: Tilted coaxial approach along finger axis

## Closed-Loop Turn Workflow
1. Inspect current state & view `wrist_cam.png`:
   `curl -s http://127.0.0.1:8081/obs` (returns `ee_pos`, `holding`, `status`, `workspace`, `wrist_cam_path`).
2. Select VLM call granularity upfront on Turn 1:
   - Coarse (2–4 calls): `look_at` -> `grasp` -> `place` -> `done`
   - Pre-Grasp Hover Verify (4–7 calls): `look_at` -> `goto(z=0.04)` (verify cyan `[ + ]` brackets straddle target) -> `grasp` -> `place_until_contact` -> `done`
   - Fine Visual Servoing (8–20 calls): `look_at` -> `grasp` -> pre-pose `goto` -> closed-loop `move_by` / `move_until_contact` -> `done`
3. Send motion primitives (`POST /plan`) and verify visually after every turn in the updated `wrist_cam.png`. If `status == "grasp_failed"`, call `robot.look_at(...)` to re-observe and recover closed-loop.

## Code-as-Policies Primitives (`POST http://127.0.0.1:8081/plan`)
robot.look_at(x=0.35, y=0.13, z=0.14, grid_z=0.015)
x, y = robot.deproject(u=0.52, v=0.48, z_plane=0.015)
robot.grasp(x=x, y=y, z=0.015, yaw_deg=-35, pitch_deg=90)
robot.place(x=0.24, y=0.06, z=0.075)
robot.place_until_contact(x=0.24, y=0.06, z=0.015, max_lag=0.012, relief=0.002)
robot.goto(x=0.28, y=0.05, z=0.04, arc_z=0.14, pitch_deg=25, azimuth_deg=90, roll_deg=0, speed=0.10)
robot.move_by(forward=0.025, dz=-0.002, dpitch_deg=-3, droll_deg=5, speed=0.04)
robot.move_until_contact(dz=-0.06, speed=0.03, max_lag=0.012, relief=0.002)
robot.open_gripper() / robot.close_gripper() / robot.home() / robot.done()
3. 全能控制
Argon 在 Gemini Omni World Model 中引导机器人将五个散落的拼字游戏 tiles(G、R、A、N、O)重新排列成一行,拼出 A - R - G - O - N。Argon 不是指定一个静态提示词,而是在闭环视觉回路中进行引导。它编写带时间戳的动作提示词,检查中间 rollout 关键帧,并优化其提示词。
Goal: {task_goal}

You are steering a video world model (Gemini Omni) in an iterative visual feedback loop. Inspect the attached frames from the latest rollout and write the next timestamped action prompt for the video world model:
- Break complex motions into one simple, single-direction action at a time.
- Keep inactive hands retracted and avoid blocking the camera's view of objects in the workspace.
- Explicitly state which areas of the workspace become empty after an object moves.
- Use [MM:SS.mmm] timestamps for each action beat and wrap your output intags.

Example format (sample timestamps only, not the full prompt):[00:00.000] Character A's left hand rests at the side while the right hand reaches toward the target object.
[00:02.500] Character A's right fingertips push the object smoothly into the center of the table, leaving its starting area empty.
[00:05.000] Character A's right hand opens and retracts to the side so all placed objects remain in clear view of the camera.
用 Argon 解锁 Real2Sim
1. 机器人视角到仿真
Argon 观察真实机器人的遥操作片段并构建数字孪生;它获取或创建仿真资产,使其在与灵巧手接触时的外观和行为与真实物体一致。Argon 在迭代式视觉推理循环中调整资产和场景,使仿真视觉效果和接触事件与真实录制数据中的一致。
[Attached: robot_rollout_episode]

Build a MuJoCo scene of the robot and reconstructed task objects. When each episode is replayed frame by frame, by driving the robot joints toward the logged observation.state with joint-space PD.

Iterate using two verification objectives:
(1) Visual match: MuJoCo renders from the head_left, left_wrist, and right_wrist cameras line up with, and look like, those real observations.
(2) Physical match: the simulated contact force/torque on each Sharpa fingertip, in the sensor frame, matches the logged tactile_force in timing, magnitude and direction.

What you can tune happens before simulation starts:
(1) Static object assets: realistic geometry, collision shapes, mass, inertia, friction and joints, with appearance close to the real objects, plus the initial object poses at t = 0.
(2) Offline-planned robot commands, changed only in frames where the real fingertips are near an object. Each command must stay within 0.55 rad (arm joints) and 0.65 rad (hand joints) of the logged teleop trajectory. Everywhere else, replay the logged trajectory unchanged.

No sim cheating: task objects may move only through real MuJoCo contact with the robot hands and the environment (mj_step).
Not allowed after t = 0: changing MjModel parameters; applying external forces or torques to objects; welds or equality constraints; feedforward torques beyond joint-space PD; setting or rolling back object qpos/qvel; disabling or excluding collisions; reporting contact forces that don't come from the MuJoCo solver (for example, copying the logged tactile readings).

Immediately present the reconstructed scene and rollout results as an interactive HTML session viewer with one page per episode, showing:
- At the bottom: A synced timeline (play, scrub, speed control) that drives every panel.
- On the left panel: An interactive 3D Blender scene showing the simulated robot and objects, showing contact points and force arrows as replay progresses.
- On the right panel: Real vs. sim camera views side by side for all 3 cameras. Real vs. sim finger force visualizations.
2. 人类视角到仿真
给定一段操作任务的自我中心人类视频,Argon 识别任务相关物体,将粗糙的边界框替换为针对凹形容器的复合凸分解网格,并在 MuJoCo 接触物理中将人类手部轨迹重定向到具有 22 自由度五指手的 76 自由度双臂人形机器人上。
[Attached: egocentric_human_video.mp4, candidate_sim_views.png, hand_3d_keypoints.json]

You are building a physically solvable 500 Hz MuJoCo manipulation environment (`scene.xml`) and studio Blender render that faithfully reproduces the tabletop task shown in `egocentric_human_video.mp4` on a bimanual humanoid robot with 22-DoF dexterous five-fingered hands:

1. Scene Reconstruction & Camera Calibration:
   - Identify only the manipulation-relevant objects (the grasped target object and the receiving container or landmark) and triangulate their 3D tabletop coordinates from the egocentric camera intrinsics/extrinsics.
   - Replace crude bounding boxes with compound convex-decomposed 3D meshes so concave containers (nested bowls, recessed wooden trays, open bins) support physical interior placement.

2. 500 Hz Dexterous Motion-Fitting Stress Test:
   - Retarget the 3D human wrist and finger keypoints to the humanoid's 7-DoF arm and 22-DoF hand joints, and step the trajectory in MuJoCo at 500 Hz (dt = 0.002s) with zero kinematic weld constraints.
   - Verify opposing thumb-and-finger force closure, clean object lift (> 2 cm), and stable final placement inside or beside the target landmark.
3. 草图到仿真
借助 Argon,开发者可以拍摄一张粗略的纸笔草图照片——图中展示 Apollo 2 人形机器人沿抛物线弧扔球,以推倒桌上 3-2-1 堆叠的箱子——并让 Argon 自动构建 GPU 加速的 mujoco_warp 场景,合成平衡的 76 自由度全身与五指投掷轨迹,在闭环物理中验证 6/6 目标击倒,并导出 Blender 4.5 Cycles 渲染。
[Attached: hand_drawn_throw_sketch.jpg]

Translate this hand-drawn sketch into a physically verified humanoid simulation in `mujoco_warp` and a raytraced Blender Cycles video:

1. Scene & Kinematic Setup from Sketch:
   - Parse the spatial layout from `hand_drawn_throw_sketch.jpg`: place the 76-DoF humanoid (32-DoF body equipped with two 22-DoF five-finger dexterous hands) at the origin facing a table holding a 3-2-1 pyramid of 6 rigid target boxes, with a projectile sphere grasped in the right five-finger hand.

2. Whole-Body Balance & Dexterous Throw Synthesis:
   - Synthesize a 50 Hz whole-body throwing trajectory (140 steps, 2.80 s) across four phases: (1) stable stance & 5-finger power grasp closure, (2) torso/shoulder wind-up with ankle-hip Center-of-Mass compensation, (3) forward whipping acceleration, and (4) synchronized 22-DoF five-finger opening at peak hand velocity so the ball launches on a ballistic arc into the pyramid's second-tier center of mass.
   - Verify in `mujoco_warp` contact physics that the humanoid maintains upright balance (< 3 cm pelvis drift) and knocks down all 6 target boxes.
用 Argon 解锁物理理解
1. 事后标注与数据质量
Argon 对灵巧操作具有精确的物理理解,并能从视频中提供详细的分割和文本标注。Argon 能够识别不良操作片段,如停顿、不稳定抓取和失误。给定一段俯视视频,内容为双臂 ALOHA 2 机器人在 136 秒内将一张方形纸折成折纸狐狸,Argon 生成时间对齐的 4 级事后标注层级:Episode Goal (G1)、6 个连续 Semantic Subtasks (G2)、17 个接触级 Atomic Primitives (G3),以及自动 Quality Control (QC) 重加权,在失误和重试期间保持任务进度不变。
[Attached: Aloha2_Origami_20250309.mp4]

Produce a time-aligned multi-granularity hindsight annotation JSON with four levels:
1. G1_episode_instruction: Concise imperative sentence describing the overall manipulation goal.
2. G2_subtasks: Contiguous semantic subtask phases specifying which arm(s) anchor vs. fold/rotate the object.
3. G3_atomic_primitives: Fine-grained contact-level primitives (3–15s) aligned with grasp closure, crease sweeps, release, or retry attempts.
4. quality_control_and_reweighting: Hold task_progress_pct flat during non-progressing slip/delamination retry loops and downweight them (0.15x–0.25x) for Behavior Cloning.
2. 找出异常球
为了用机器人重现经典的 12 球天平谜题,Argon 构建了一个双臂 Franka FR3 MuJoCo 环境,包含 12 个视觉上相同的台球(其中一个秘密地更重或更轻)以及一个铰接式 Roberval 双盘天平。随后它编写了一个仅视觉的闭环求解器,通过立体 RGB 相机对球进行三角测量,在每次称重后视觉读取天平倾斜,并在 3 次称重内将异常球隔离到 Heavy (Red) 或 Light (Blue) 托盘中。
# Prompt 1 — Physics-Accurate MuJoCo Environment & Benchmark Generation
Make a MuJoCo environment where a dual-arm robot (two 7-DoF Franka FR3 arms with parallel-jaw grippers on a shared tabletop) is tasked to solve the classic 12-ball balance scale weight puzzle from https://www.mathsisfun.com/pool_balls_solution.html.
1. Create 12 visually indistinguishable pool balls in a 2x6 starting rack (11 standard 150 g, 1 odd ball either 270 g or 30 g).
2. Build a functional two-pan Roberval balance scale at the center of the table with parallelogram equality constraints (`mjEQ_JOINT`) so the Left (Gold) and Right (Teal) pans stay horizontal, plus Red (Heavy) and Blue (Light) submission trays.
3. Track distinct settled weighings (`weighing_count`) and reward `1.00` for isolating the true odd ball in the correct Heavy/Light tray within <= 3 weighings.

# Prompt 2 — Closed-Loop Vision-Only Solver
Implement an independent closed-loop policy relying strictly on stereo RGB camera inputs (`head_camera_left_rgb_image`, `head_camera_right_rgb_image`) and robot proprioception (`add_privileged_task_observations=False`):
1. Segment the 12 balls, Gold/Teal pans, and Red/Blue trays in both stereo views and triangulate their 3D coordinates.
2. Visually read the balance scale tilt after each weighing from stereo vertical pixel disparity (+1 = left heavier, -1 = right heavier, 0 = balanced).
3. Rotate the gripper wrist yaw by 90 degrees when grasping/placing inside the narrow scale pans to clear the raised rims, and isolate the odd ball into the Red or Blue tray within <= 3 weighings.
3. 价值函数
Argon 是机器人任务的通用价值函数。在来自人类 UMI 数据集的 60 秒双臂环形分拣回合上进行评估时,Argon 围绕接触转换迭代检查同步的头部、左夹爪和右夹爪摄像头画面,以生成密集的价值函数/任务进度预测,并将轨迹分解为 28 个片段,这些片段具有正向、中性和负向的进度斜率。
[Attached: umi_head.mp4, umi_left_gripper.mp4, umi_right_gripper.mp4]

Look at 3 videos of human wearing a gripper performing activities from head, left, right gripper views. Look at the videos thoroughly and give a detailed plot of progress at the task (with positive, neutral, negative slope), identifying important segments in the video and labeling the activities. Look at individual frames or subsegments of the video if necessary to get a better understanding.
用 Argon 解锁研究与自我改进
1. 通过仿真进行动作改进
Argon 可以在仿真中生成新数据,以提升通用视觉-语言-动作(VLA)模型的性能。从真实桌面的单张 RGB 照片开始,Argon 自主构建一个经过校准的 MuJoCo 仿真孪生体,定义新任务,并合成一个闭环运动生成器,在仿真中收集 4,500+ 个域随机化回合——将真实世界物理机器人的成功率从 56% 提升至 75%,并将完成时间从 35s 缩短至 24s。
[Attached: real_tabletop_photo.jpg]

You are given a single overhead RGB camera photo (`real_tabletop_photo.jpg`) of a bimanual robot workspace (two 7-DoF Franka FR3 arms with parallel-jaw grippers and 4 RGB cameras) facing a table arranged with photobooth party props.
1. Reconstruct procedural 3D meshes and compound MuJoCo collision primitives for all 9 party props matching their real-world dimensions, colors, and resting poses, including spring-hinged deformable crown panels for the soft plush cap.
2. Define a 77-task single-arm and bimanual curriculum (pick-and-place, uprighting, directional pushing, mid-air handovers, bimanual scoop-and-push, and pipelined table clearing).
3. Synthesize a closed-loop IK trajectory generator across ±10 cm pose randomization, verify `reward == 1.0` in MuJoCo physics, and export 4,500+ episodes for VLA fine-tuning.
2. 视觉抓取放置的自我改进
在一个简单的 6-DoF 机械臂上,Argon 通过试错和自我反思,在抓取放置任务中迭代地自我改进执行速度和放置精度。
# Stage 1 — Measure Objects & Dry-Run Plan (No Hardware Motion)
Stage 1: measure objects — find the objects and plan the whole motion. The arm does not move in this stage.

A. I put a LEGO brick and a box on the table in front of the arm, and the wooden box to one side. Find the brick and the wooden box in the image. And also in the real world. Show this in an annotated image.

B. A dry-run plan (no hardware). Write the planner to pick and place the lego block. Print the plan table, draw all poses onto the overhead image, and stop. Do not move the robot.
Report with evidence.

# Stage 2 — Pre-Pick Hover & Wrist-Camera Verification
Stage 2: Put the gripper above the brick without touching it, and verify with the wrist camera that the arm and the vision agree. Please record executions with both cameras (compressed video is OK).

# Stage 3 (Autonomous Pick-and-Place → Self-Improvement → Optimization):
1. Execute autonomously: Turn the Stage 1 dry run into a real grasp, lift, and place into the wooden box. Run it yourself subject to safety rules from AGENTS.md.

2. Self-improve: When an attempt fails, diagnose it yourself. Review your own logs and wrist/overhead footage, find the root cause, check the fix in a dry run, and retry.

3. Optimize on feedback: Once it succeeds, make it at least 2× faster within safety limits (rule R5) unless I authorize more, or give feedback.
3. 在 MuJoCo WebAssembly 中一键复现机器人学论文
每篇论文只需一个提示,Argon 即可阅读机器人控制手稿及任何已发布的检查点,将物理模型和闭环控制器(从 DeepLoco 中的 7 网络分层运动控制和 HUSKY 中的 50 Hz PPO actor,到 Whole-Body MPC 中的 Web Worker iLQR)移植到自包含的 MuJoCo WebAssembly 浏览器实验室中,并在无头 Chromium 中验证它们。
[Attached: paper.pdf, optional author_checkpoints/ or urdf_assets/]

Reproduce the paper "" from scratch in MuJoCo WebAssembly and deploy a self-contained browser lab + visual essay:
1. Match the paper's exact physics timestep, actuator gains (kp/kv), torque limits, and kinematic constraints in MuJoCo XML, and run real neural inference or Web Worker iLQR in JavaScript at the paper's exact control rates.
2. Build `index.html` (Spatial UI simulator with camera presets, live telemetry plots, and disturbance injection) and `scrollytelling.html` (interactive visual essay).
3. Run a headless Chromium (Playwright) verification loop asserting 0 console errors and non-zero task progress over 300+ frames.
用 Argon 推进具身智能
Argon 连接了编码、视觉感知、物理仿真和具身机器人控制。通过原生地对多视角视频、3D 几何、接触力学和本体感知遥测进行推理,Argon 不仅理解场景中有哪些物体,还理解它们如何与智能体进行物理交互,以完成全身灵巧任务。Gemini 4 Argon 是一个重要的里程碑,加速了通往物理 AGI 的道路。通过构建这一核心智能,我们的目标是使机器人能够与人类并肩工作,解决复杂挑战。
开始使用
你今天就可以在 Google 的开发者平台上开始使用 Gemini 4 Argon 进行构建:
Google AI Studio:面向 Google AI Ultra 订阅用户开放。
Gemini API:在 AI Studio 中通过 Gemini API 的付费层级提供。在 Interactions API 中使用 gemini-4-argon,google-genai SDK 系列从第一天起即提供支持。
Google Antigravity:面向 Google AI Ultra 订阅用户开放。要开始构建,请在 Google Antigravity 中选择 Gemini 4 Argon( gemini-4-argon )作为你的活动模型,用于复杂规划、/goal 运行和多智能体编排。
转载声明:本文为转载整理,原文版权归原作者及原站点所有。
原文来源:Google DeepMind Blog
原创地址:https://deepmind.google/blog/gemini-4-argon-for-robotics/
原文作者:Kanishka Rao;如有侵权,请联系管理员删除。

