timescaledb 和 原生postgresql 常见场景查询效率对比
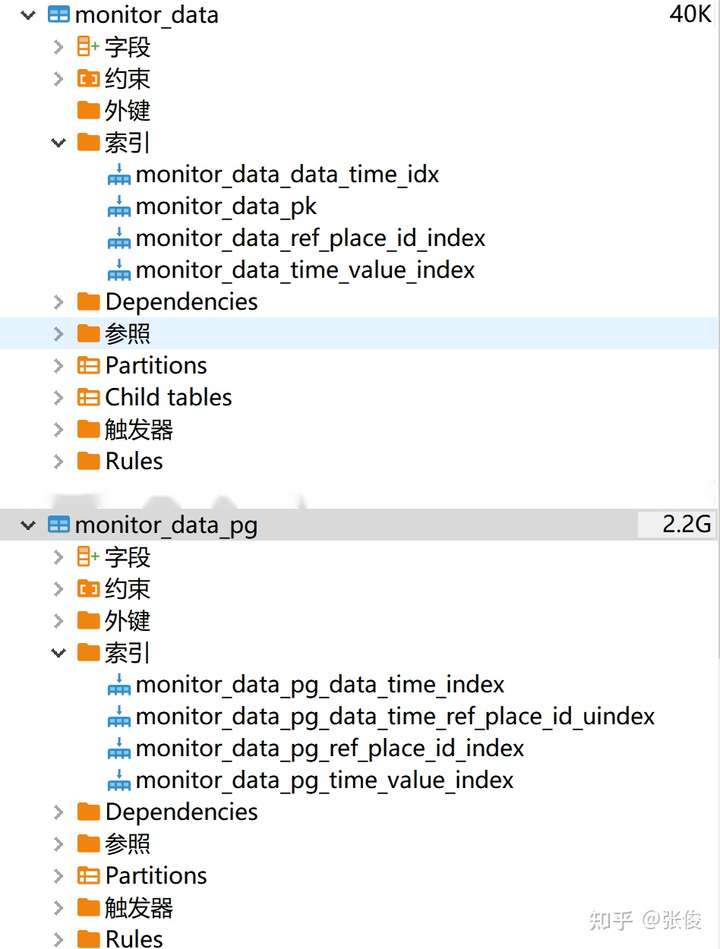
1000w数据记录的表(这个小数量级的,性能差距可能不明显。但从执行计划中能看出timescaledb随数据量增大,性能稳定的原因),两张表均也添加所需要的索引。monitor_data(通过上篇文章可知,实际数据都存储在分区表中,所以只有40k) 是 timescaledb 创建的 hypertable,monitor_data_pg 是 pg 原生的表。
1、pg 原生函数,timescaledb 做了优化
移动平均查询
| 实际执行时间(ms) | |
|---|---|
| timescaledb hypertable | 8057 |
| pg 原生表 | 7793 |
-- timescaledb hypertable
SELECT data_time, AVG(level) OVER(ORDER BY data_time
      ROWS BETWEEN 9 PRECEDING AND CURRENT ROW)
    AS smooth_temp,
       level
  FROM monitor_data
  where data_time > '2021-01-01' and data_time < '2021-07-01'
  ORDER BY data_time DESC;
-- pg 原生表
SELECT data_time, AVG(level) OVER(ORDER BY data_time
      ROWS BETWEEN 9 PRECEDING AND CURRENT ROW)
    AS smooth_temp,
       level
  FROM monitor_data_pg
  where data_time > '2021-01-01' and data_time < '2021-07-01'
  ORDER BY data_time DESC;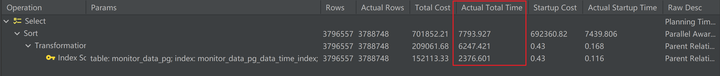
数据变化查询(比如闸门开关的信号量,可查询闸门开、闭的时间点)
| 实际执行时间(ms) | |
|---|---|
| timescaledb hypertable | 5584 |
| pg 原生表 | 4773 |
-- timescaledb hypertable
SELECT data_time, level FROM (
  SELECT data_time,
    level,
    monitor_data.level - LAG(level) OVER (ORDER BY data_time) AS diff
  FROM monitor_data where data_time > '2021-01-01' and data_time < '2021-07-01') ht
WHERE diff IS NULL OR diff != 0;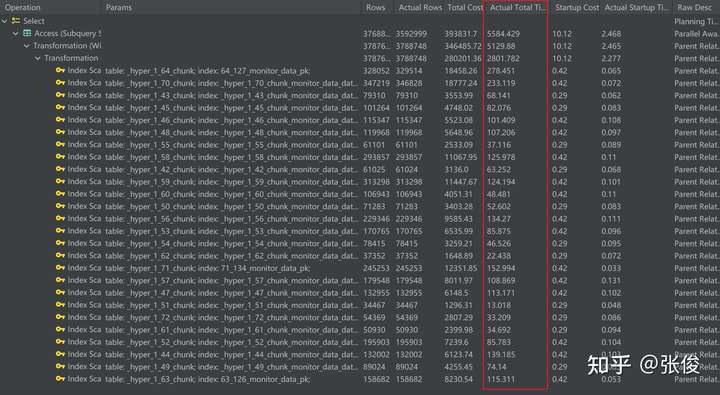
-- pg 原生表
SELECT data_time, level FROM (
  SELECT data_time,
    level,
    monitor_data_pg.level - LAG(level) OVER (ORDER BY data_time) AS diff
  FROM monitor_data_pg where data_time > '2021-01-01' and data_time < '2021-07-01') ht
WHERE diff IS NULL OR diff != 0;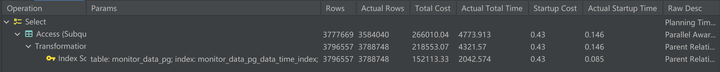
2、timescaledb 特有函数,pg 原生容易变相实现
time_bucket 时间间隔查询
time_bucket 是 pg date_trunc 的优化,支持任意时间间隔查询。
| 实际执行时间(ms) | |
|---|---|
| timescaledb hypertable | 1311 |
| pg 原生表 (使用 date_trunc) | 2411 |
| pg 原生表(不使用 date_trunc,任意间隔) | 2344 |
-- timescaledb hypertable
SELECT public.time_bucket('1 hours', data_time) AS one_hour, avg(level)
FROM monitor_data
where data_time > '2021-01-01'
  and data_time < '2021-07-01'
GROUP BY one_hour;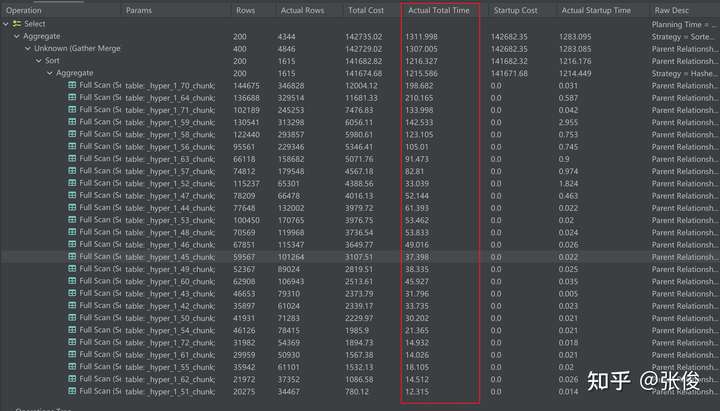
-- pg 原生表 (使用 date_trunc)
SELECT date_trunc('hours', data_time) one_hour, avg(level)
FROM monitor_data_pg
where data_time > '2021-01-01'
  and data_time < '2021-07-01'
GROUP BY one_hour;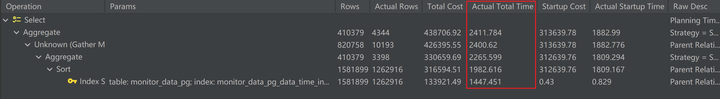
-- pg 原生表 (不使用 date_trunc,任意时间间隔)
SELECT time_value / 60 one_hour_span, min(data_time) one_hour, avg(level)
FROM monitor_data_pg
where data_time > '2021-01-01'
  and data_time < '2021-07-01'
GROUP BY one_hour_span;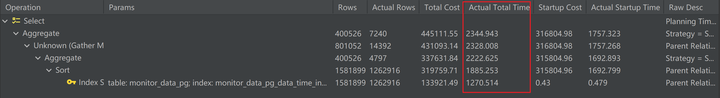
first、last 最开始、最新数据查询
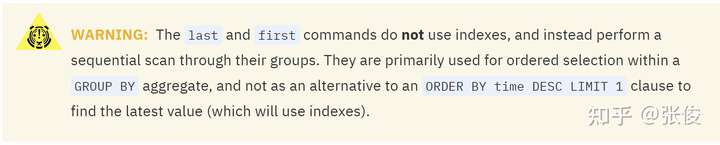
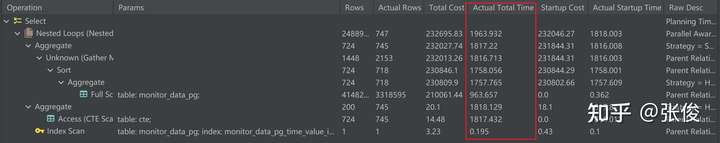
官网关于两个,有个warning提示。就是SQL写起来方便,效率确实不咋地。
| 实际执行时间(ms) | |
|---|---|
| timescaledb hypertable | 3714 |
| pg 原生表 | 1963 |
-- timescaledb hypertable
SELECT ref_place_id, public.first(level, data_time)
FROM monitor_data
GROUP BY ref_place_id;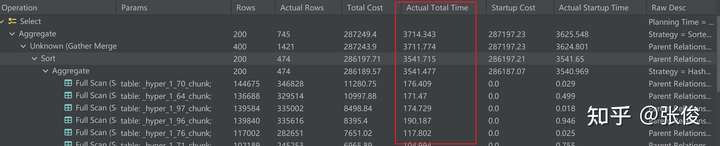
-- pg 原生表
with cte as (
    select ref_place_id, min(time_value) min_time_value
    from monitor_data_pg
    group by ref_place_id
)
select ref_place_id, level
from monitor_data_pg md
where exists(
              select 1 from cte where cte.min_time_value = md.time_value and cte.ref_place_id = md.ref_place_id
          );
3、timescaledb 特有函数,pg 原生不易变相实现
插值类型 time_bucket_gapfill 相关的函数,pg 原生不易变相实现。
来源 https://zhuanlan.zhihu.com/p/475811110
来自 “ ITPUB博客 ” ,链接:https://blog.itpub.net/69999831/viewspace-3128332/ ,如需转载,请注明出处,否则将追究法律责任。
上一篇:
Palo介绍
下一篇:
DolphinDB数据导入教程

请登录后发表评论
登录
全部评论
