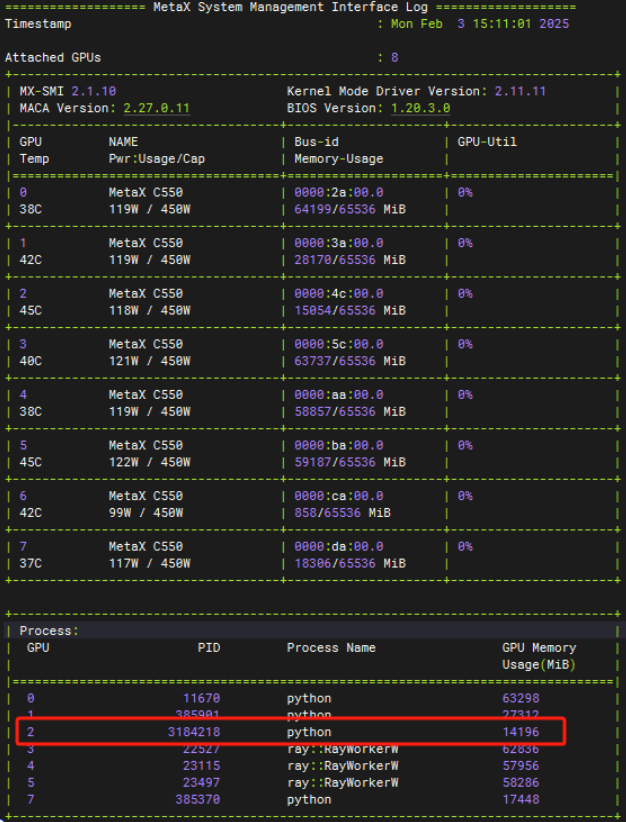
2月3日,DeepSeek 刚刚上线了DeepSeek-Janus-Pro-7B模型,天云数据率先完成基于沐曦GPU服务器的DeepSeek模型适配,完成国产模型 + 国产GPU + 国产训练平台全兼容服务,实现AI全流程国产化流水线时代。
天云数据打造全国产AI 端到端生态链
天云数据训练平台+DeepSeek多模态模型+国产沐曦GPU适配结果如下,由此可见,天云数据训练平台完全实现了国产化。国产AI技术可以加速全球竞争,并将加速AI工具的应用。
效果对比综述
-
所有参数均使用默认取值。
-
测试数据来源
-
文生图,
-
多模态理解
1,2:中美对比 ,
3,4:和大厂效果对比
1,2: 中美对比 ,
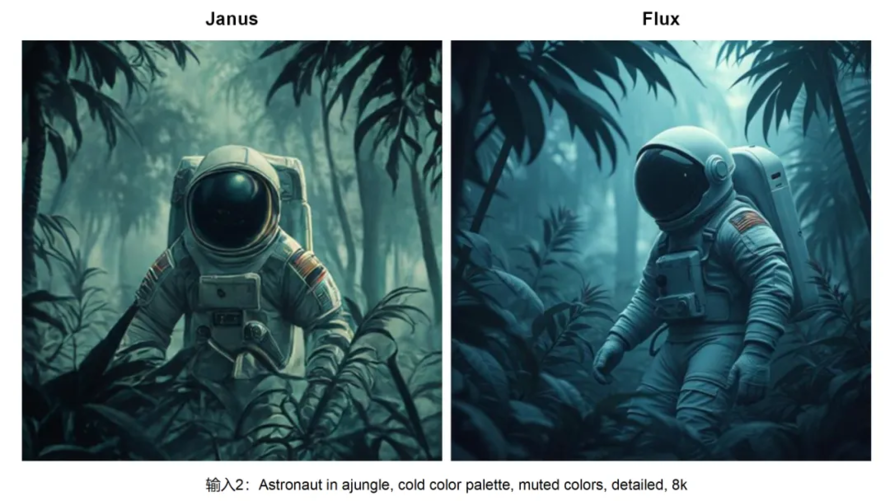
文生图 VS Flux
-
Janus Pro 7B访问地址: http://xx xx xx xx:42101/janus/
-
Flux访问地址: https://www.blinkshot.io/



多模态理解 VS Qwen2.5 VL 7B
输入1:Convert the formula into latex code.
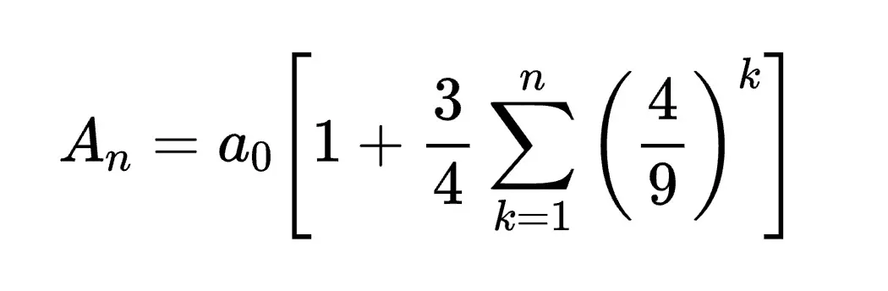
Janus
Here is the formula converted into LaTeX code:
\[ A_n = a_0 \left[ 1 + \frac{3}{4} \sum_{k=1}^{n} \left( \frac{4}{9} \right)^k \right] \]
Qwen2.5 VL 7B
The given formula can be converted into LaTeX code as follows:
A_n = a_0 \left[ 1 + \frac{3}{4} \sum_{k=1}^{n} \left( \frac{4}{9} \right)^k \right]
This LaTeX code will render the mathematical expression in a clear and professional format.
输入2:图上的文字是什么

Janus
图上的文字是:- 左边的文字是:“Decoupling Visual Encoding”- 右边的文字是:“Single Visual Encoder”
Qwen2.5 VL 7B
图上的文字是:
左边:Decoupling Visual Encoding
右边:Single Visual Encoder
输入3:Who are these in this picture? Please give their names in Chinese and English.

Janus
The image features four individuals. Here are their names in both Chinese and English:1. 左上角: 迈克尔·杰克逊 (Michael Jackson)2. 右上角: 科比·布莱恩特 (Kobe Bryant)3. 左下角: 周星驰 (Jackie Chan)4. 右下角: 唐纳德·特朗普 (Donald Trump)
Qwen2.5 VL 7B
The individuals in the picture are:
迈克尔·杰克逊 (Michael Jackson)
迈克尔·乔丹 (Michael Jordan)
成龙 (Jackie Chan)
唐纳德·特朗普 (Donald Trump)
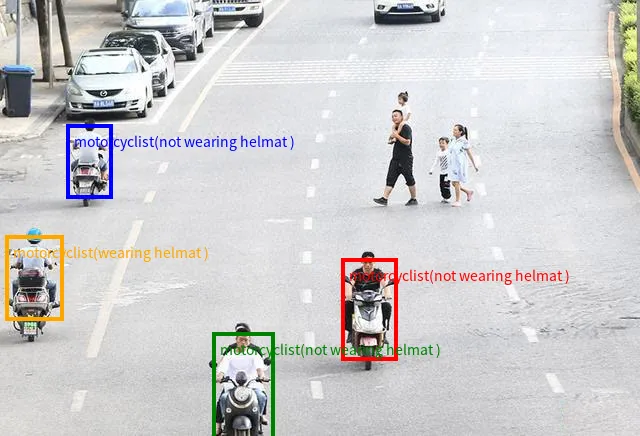
输入4:Detect all motorcyclists in the image and return their locations in the form of coordinates. The format of output should be like {“bbox_2d”: [x1, y1, x2, y2], “label”: “motorcyclist”, “sub_label”: “wearing helmat” # or “not wearing helmat”}.
Janus
To detect all motorcyclists in the image and return their locations in the specified format, I will analyze the image and identify the motorcyclists based on their bounding boxes.1. **Locate motorcyclists**: Identify motorcyclists in the image.2. **Extract bounding box coordinates**: Extract the coordinates of the bounding boxes.3. **Label and sub-label**: Label the motorcyclists as "wearing helmet" or "not wearing helmet".Here's the output based on the analysis:```json[{"bbox_2d": [100, 100, 200, 200],"label": "motorcyclist","sub_label": "wearing helmat"},{"bbox_2d": [300, 100, 400, 200],"label": "motorcyclist","sub_label": "wearing helmat"},{"bbox_2d": [100, 300, 200, 400],"label": "motorcyclist","sub_label": "not wearing helmat"},{"bbox_2d": [300, 300, 400, 400],"label": "motorcyclist","sub_label": "not wearing helmat"}]```This output includes the bounding box coordinates, the label of the motorcyclist, and whether they are wearing a helmet or not.
Qwen2.5 VL 7B
[ {"bbox_2d": [345, 257, 406, 381], "label": "motorcyclist", "sub_label": "not wearing helmat"}, {"bbox_2d": [219, 331, 269, 447], "label": "motorcyclist", "sub_label": "not wearing helmat"}, {"bbox_2d": [20, 235, 63, 350], "label": "motorcyclist", "sub_label": "wearing helmat"}, {"bbox_2d": [69, 158, 114, 208], "label": "motorcyclist", "sub_label": "not wearing helmat"}]输入5:Extract following information from the receipt:[‘发票代码’,‘发票号码’,‘到站’,‘燃油费’,‘票价’,‘乘车日期’,‘开车时间’,‘车次’,‘座号’],output in JSON。
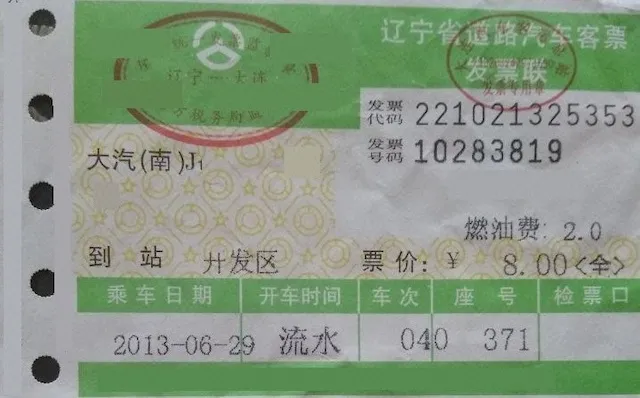
Janus
{ "发票代码": "221021325353", "发票号码": "10283819", "到站": "北京西", "燃油费": "2.0", "票价": "8.00元", "乘车日期": "2013-08-29", "开车时间": "04:0", "车次": "371", "座号": "无"}Qwen2.5 VL 7B
{ "发票代码": "221021325353", "发票号码": "10283819", "到站": "开发区", "燃油费": "2.0", "票价": "8.00<全>", "乘车日期": "2013-06-29", "开车时间": "流水", "车次": "040", "座号": "371"}总结
仅从上述测试数据来讲,将多模态理解和生成任务统一在一个模型中,对视觉任务大一统做出一定的贡献。
Deepseek R1标志着后训练时代启动
基于多头注意力MoE专家模型,DeepSeek刷榜了大模型性能指标。对标OpenAI o1,更擅长复杂推理的DeepSeek R1是依靠思维链的拆解完成更复杂任务推理,同时R1 zero使用强化学习框架和微调训练框架,把单纯依托基础大模型的技术路线,升级到LXMops的平台任务逻辑。
OpenAI前首席科学家Ilya指出,当前 AI 模型预训练方式将不可避免地走向终结,预训练时代将终结,未来AI或将不可预测。
成熟度达到L5级水平
天云数据提供从“数据工程”到“云原生机器学习平台”到“云原生大模型平台”再到“模型推理服务发布平台”的端到端AI生产流水线服务,支撑多个国产模型的异构部署,助力AI服务成熟度达到国际L5级水平。随着大模型后训练市场兴起,开始服务千行百业。
来自 “ ITPUB博客 ” ,链接:https://blog.itpub.net/69982626/viewspace-3071511/ ,如需转载,请注明出处,否则将追究法律责任。

最新文章
- “AI+安全生产落地实践”线上研讨会报名启动,限量席位,先到先得
- 算法霸权:看 Palantir 的“本体”革命
- 算法霸权:从现实人物降维为概率对象,看 Palantir 的“本体”革命
- 算法霸权:从现实人物降维为概率对象,看 Palantir 的“本体”革命
- “首都科技人”雷涛:解码AI时代的“算力密码”
- 官宣!京能集团携手天云数据发布基于DeepSeek全栈国产大模型服务
- DeepSeek用CoT让英伟达市值暴跌,天云数据训练平台推动AI推理全民化
- 两度霸占热搜榜单|天云数据如何用量子随机技术如何加持AI原生数据库?
- 重磅!天云数据Elpis智能体应用开发工具平台荣获智能体应用优秀案例
- 天云数据参编指南《上海全球资产管理中心建设 资产管理大模型应用实践与指南》发布
