再聊聊 snapshot too old 的利弊
前言
昨天一位同事找到我,说有个实例采用了逻辑复制同步数据,但是发现订阅端的数据越来越大,甚至比发布端的表还大(发布端才 330GB,订阅端却有 600GB,并且还在不断增大)并且更加离谱的是,订阅端的表查询出来却全是空的!
让我们一起分析下这个有趣的案例 ~
现象
经过短暂的分析,我已经成功复现出来了。首先发布端创建一个大表
postgres=# select pg_size_pretty(pg_relation_size('test_big'));
 pg_size_pretty
----------------
 4381 MB
(1 row)

postgres=# create publication pub1 for table test_big ;
CREATE PUBLICATION
在订阅端进行订阅
postgres=# create subscription sub1 connection 'host=localhost port=5432' publication pub1 with ( enabled = off);
NOTICE:  created replication slot "sub1" on publisher
CREATE SUBSCRIPTION
由于还未显式开启订阅,因此发布端仅能看到一条 active 为 false 的逻辑复制槽
postgres=# select slot_name,temporary,active,active_pid,xmin,catalog_xmin,restart_lsn,confirmed_flush_lsn from pg_replication_slots ;
 slot_name | temporary | active | active_pid | xmin | catalog_xmin | restart_lsn | confirmed_flush_lsn
-----------+-----------+--------+------------+------+--------------+-------------+---------------------
 sub1      | f         | f      |            |      |        19047 | 8/C24155C8  | 8/C2415600
(1 row)
现在开启订阅,观察一下差异
postgres=# select pid,application_name,backend_xmin,state from pg_stat_replication;
 pid  |            application_name             | backend_xmin |   state
------+-----------------------------------------+--------------+-----------
 2710 | sub1                                    |              | streaming
 2712 | pg_16473_sync_16384_7161719926551277207 |        19047 | startup
(2 rows)

postgres=# select slot_name,temporary,active,active_pid,xmin,catalog_xmin,restart_lsn,confirmed_flush_lsn from pg_replication_slots ;
                slot_name                | temporary | active | active_pid | xmin | catalog_xmin | restart_lsn | confirmed_
flush_lsn
-----------------------------------------+-----------+--------+------------+------+--------------+-------------+-----------
----------
 sub1                                    | f         | t      |       2710 |      |        19047 | 8/C2415688  | 8/C24156C0
 pg_16473_sync_16384_7161719926551277207 | f         | f      |            |      |        19047 | 8/C2415600  | 8/C2415638
(2 rows)
可以看到新增了一个复制槽,同时状态是 startup,说明 walsender 还在启动中
“
startup: This WAL sender is starting up.
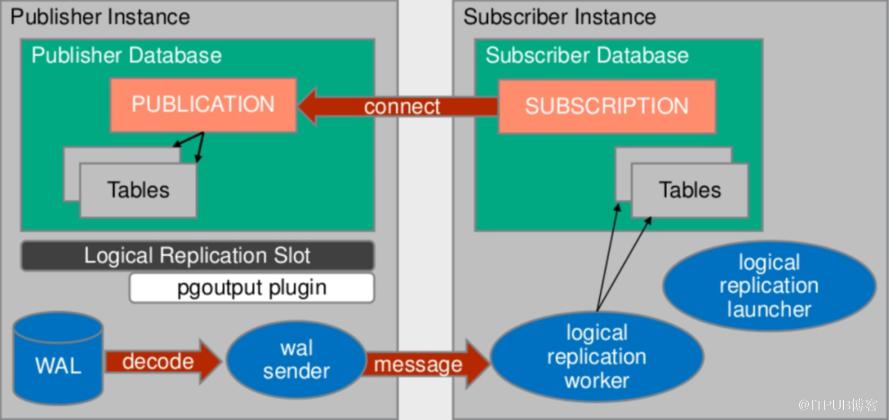
新增的一个复制槽是高版本引入的增强,用于解决在初始同步数据期间一系列可能的问题
We have to perform the entire copy operation again if there is any error (network breakdown, error in the database operation, etc.) while we synchronize the WAL position between tablesync worker and apply worker; this will be onerous especially for large copies, Using a single transaction in the synchronization-phase (where we can receive WAL from multiple transactions) will have the risk of exceeding the CID limit, The slot will hold the WAL till the entire sync is complete because we never commit till the end.
每个 Tablesync Worker 都有一个关联的复制槽。以前是临时的复制槽,仅在每个 Tablesync Worker 的生命周期内存在。如果 Tablesync Worker 意外崩溃,则槽位丢失,当重新启动的 Tablesync Worker 启动时,它会从新创建的复制槽开始,然后再次重复所有内容。Tablesync Worker 改成使用永久的复制槽而不是临时复制槽,这样复制源信息会保存,用于跟踪已经复制的数据,这意味着在崩溃/重新启动后,可以从最近记录的检查点再次继续复制。
另外还需要注意的是,新增的 slot 含有 backend_xmin,因此这个 xmin 会在 vacuum 工作过程中正常计入到 oldestxmin 计算逻辑中,并且在未完成数据同步之前,根据可见性规则,在订阅端是无法查看到这些数据的(否则就脏读了)。
看个例子,订阅端 👇🏻
postgres=# select pg_size_pretty(pg_relation_size('test_big'));  ———表在同步过程中,不断增大
 pg_size_pretty
----------------
 406 MB
(1 row)

postgres=# select * from test_big limit 5;       ---查询数据是空的
 id | info | t_time
----+------+--------
(0 rows)

postgres=# select lp, t_xmin, t_xmax, t_ctid,    ---查看数据的插入事务ID
       infomask(t_infomask, 1) as infomask,
       infomask(t_infomask2, 2) as infomask2
from heap_page_items(get_raw_page('test_big', 0)) limit 5;
 lp | t_xmin | t_xmax | t_ctid |         infomask         | infomask2
----+--------+--------+--------+--------------------------+-----------
  1 |    852 |      0 | (0,1)  | XMAX_INVALID|HASVARWIDTH |
  2 |    852 |      0 | (0,2)  | XMAX_INVALID|HASVARWIDTH |
  3 |    852 |      0 | (0,3)  | XMAX_INVALID|HASVARWIDTH |
  4 |    852 |      0 | (0,4)  | XMAX_INVALID|HASVARWIDTH |
  5 |    852 |      0 | (0,5)  | XMAX_INVALID|HASVARWIDTH |
(5 rows)

postgres=# select * from pg_current_snapshot();
 pg_current_snapshot
---------------------
 852:852:
(1 row)

postgres=# select txid_status('852');
 txid_status
-------------
 in progress
(1 row)
根据可见性规则
xmin:最早的状态仍为active的事务txid,所有比它更早的事务(txid xmax:获取快照时第一个尚未分配的xid,所有txid>=xmax的事务在获取快照时尚未启动,因此其结果对当前事务不可见。 xip_list:获取快照时,所有active事务的txid列表,该列表仅包含[xmin,xmax)范围内的活跃事务txid
表里目前所有的元组都是 852 这个事务插入的(同步阶段),852 事务大于等于 xmax,因此满足第二条规则,不可见,所以满足我们的现象:查询出来是空的。
那么目前还剩下另外一个问题,为什么到了后面订阅侧的大小比发布端的大小还大?没错,又双叒叕是 old_snapshot_threshold 参数搞的鬼!old_snapshot_threshold 会强制删除会较老事务保留的事务快照,在初始同步数据的期间,业务对于表还有增删改,由于配置了 old_snapshot_threshold ,那么一旦触发了 autovacuum,autovacuum 会强制清除这些元组,这样的话对于订阅端来说,假如还未同步完成还在同步中,那么此时的数据就不是最开始同步时候所看到的数据了,这也是为什么会在 pg_stat_replication 中看到有 backend_xmin 的原因,就是为了确保是一致的。于是,当发布端报了 snapshot too old 的报错之后,说明数据已经被强制清除了,那么这个时候为了一致性,订阅端会再次启动一个 Tablesync Worker ,重新全量拉一次数据。
让我们验证一下
postgres=# drop subscription sub1 ;
NOTICE:  dropped replication slot "pg_16487_sync_16384_7161719926551277207" on publisher
NOTICE:  dropped replication slot "sub1" on publisher
DROP SUBSCRIPTION
postgres=# truncate table test_big ;
TRUNCATE TABLE
postgres=# create subscription sub1 connection 'host=localhost port=5432' publication pub1 with ( enabled = off);
NOTICE:  created replication slot "sub1" on publisher
CREATE SUBSCRIPTION
postgres=# alter subscription sub1 enable ;
ALTER SUBSCRIPTION
backend_xmin 是 19047
postgres=# select pid,application_name,backend_xmin,state from pg_stat_replication;
 pid  |            application_name             | backend_xmin |   state
------+-----------------------------------------+--------------+-----------
 6406 | sub1                                    |              | streaming
 6408 | pg_16491_sync_16384_7161719926551277207 |        19047 | startup
(2 rows)
现在在正常同步数据
postgres=# select pg_size_pretty(pg_relation_size('test_big'));
 pg_size_pretty
----------------
 1584 MB
(1 row)

postgres=# select lp, t_xmin, t_xmax, t_ctid,
       infomask(t_infomask, 1) as infomask,
       infomask(t_infomask2, 2) as infomask2
from heap_page_items(get_raw_page('test_big', 0)) limit 5;
 lp | t_xmin | t_xmax | t_ctid |         infomask         | infomask2
----+--------+--------+--------+--------------------------+-----------
  1 |    859 |      0 | (0,1)  | XMAX_INVALID|HASVARWIDTH |
  2 |    859 |      0 | (0,2)  | XMAX_INVALID|HASVARWIDTH |
  3 |    859 |      0 | (0,3)  | XMAX_INVALID|HASVARWIDTH |
  4 |    859 |      0 | (0,4)  | XMAX_INVALID|HASVARWIDTH |
  5 |    859 |      0 | (0,5)  | XMAX_INVALID|HASVARWIDTH |
(5 rows)
在发布端随便更新点数据并执行vacuum
postgres=# begin;
BEGIN
postgres=*# select txid_current();
 txid_current
--------------
        19047
(1 row)

postgres=*# update test_big set id = 10086 where id < 1000;
UPDATE 1998
postgres=*# commit ;
COMMIT
postgres=# vacuum VERBOSE test_big ;\watch 5
INFO:  vacuuming "public.test_big"
INFO:  table "test_big": found 0 removable, 30003157 nonremovable row versions in 280404 out of 560767 pages
DETAIL:  1998 dead row versions cannot be removed yet, oldest xmin: 19047
Skipped 0 pages due to buffer pins, 0 frozen pages.
CPU: user: 3.89 s, system: 1.47 s, elapsed: 33.16 s.
INFO:  vacuuming "pg_toast.pg_toast_41964"
INFO:  table "pg_toast_41964": found 0 removable, 0 nonremovable row versions in 0 out of 0 pages
DETAIL:  0 dead row versions cannot be removed yet, oldest xmin: 19047
Skipped 0 pages due to buffer pins, 0 frozen pages.
CPU: user: 0.00 s, system: 0.00 s, elapsed: 0.01 s.
VACUUM

...
...

INFO:  vacuuming "public.test_big"
INFO:  table "test_big": index scan bypassed: 21 pages from table (0.00% of total) have 1998 dead item identifiers
INFO:  table "test_big": found 1998 removable, 2318 nonremovable row versions in 41 out of 560767 pages
DETAIL:  0 dead row versions cannot be removed yet, oldest xmin: 19048
Skipped 0 pages due to buffer pins, 0 frozen pages.
CPU: user: 0.02 s, system: 0.00 s, elapsed: 0.02 s.
INFO:  vacuuming "pg_toast.pg_toast_41964"
INFO:  table "pg_toast_41964": found 0 removable, 0 nonremovable row versions in 0 out of 0 pages
DETAIL:  0 dead row versions cannot be removed yet, oldest xmin: 19048
Skipped 0 pages due to buffer pins, 0 frozen pages.
CPU: user: 0.00 s, system: 0.00 s, elapsed: 0.00 s.
Mon 07 Nov 2022 04:39:03 PM CST (every 5s)

VACUUM
大约过了1分钟,可以看到 1998 条死元祖被强制清除了,
“
DETAIL: 1998 dead row versions cannot be removed yet, oldest xmin: 19047Skipped 0 pages due to buffer pins, 0 frozen pages.
超过了 old_snapshot_threshold 时间之后
“
DETAIL: 0 dead row versions cannot be removed yet, oldest xmin: 19048Skipped 0 pages due to buffer pins, 0 frozen pages.
订阅端日志也有所反馈
2022-11-07 16:35:03.410 CST [6405] LOG:  logical replication apply worker for subscription "sub1" has started
2022-11-07 16:35:03.416 CST [6407] LOG:  logical replication table synchronization worker for subscription "sub1", table "test_big" has started
2022-11-07 16:39:26.831 CST [6407] ERROR:  could not receive data from WAL stream: ERROR:  snapshot too old
2022-11-07 16:39:26.831 CST [6407] CONTEXT:  COPY test_big, line 58252584
2022-11-07 16:39:26.890 CST [1787] LOG:  background worker "logical replication worker" (PID 6407) exited with exit code 1
2022-11-07 16:39:26.903 CST [6677] LOG:  logical replication table synchronization worker for subscription "sub1", table "test_big" has started
在拷贝了 58252584 行之后,由于 snapshot too old 错误,订阅端重新 fork 了一个 worker 进程,重新拉取全量。因此不难理解,为什么订阅端的数据会比发布端的数据还大,并且大几百GB的表查询还全是空的 👇🏻
订阅端同步数据中 发布端正常对表增删改查 autovacuum 达到阈值对表进行清理,同时由于发布端配置了 old_snapshot_threshold,所以到了时间会强制清除数据 订阅端还在同步数据中,由于报错,为了确保一致性,重新 fork worker 进程重新拉取全量数据 报错前已经拉取的全量数据,由于报错,事务回滚,数据不可见 正在拉取的数据由于还未完成,事务处于 in progress,数据依旧不可见
因此不断恶性循环,导致订阅端的数据不断膨胀,发布端只有300GB,订阅端却达到了600GB,并且还在膨胀中...
知晓了原因之后,解决办法也很简单,在同步数据的过程中在发布端临时将 old_snapshot_threshold 设为 -1即可。
小结
old_snapshot_threshold 参数主要是为了解决表膨胀的问题,防止由于较老事务的存在,无线膨胀下去,经过这个案例,old_snapshot_threshold 的危害加 1,当配置了 old_snapshot_threshold 参数之后
vacuum 无法截断位于表末尾的空文件 在创建索引之前存在长事务,该索引需要等待长事务结束才可使用 在逻辑订阅过程中,假如表很大并且一直在写入,可能会导致初始数据同步这个过程一直结束不了,不断膨胀下去
所以,谨记 old_snapshot_threshold 的利弊。
另外出一个发散题,各位读者不妨思考一下🤔:物理备库配置了 old_snapshot_threshold 之后,与主库的表现有何异同?
原文作者:PostgreSQL学徒;如有侵权,请联系管理员删除。

