本文原创作者:鲲之鹏(http://www.site-digger.com)
本文原始链接:http://www.site-digger.com/html/articles/20180716/652.html
xpath和正则表达式是数据提取时最常用的两种方法,究竟用哪个好呢?相信看过本文后你会有一个果断的选择。
测试代码如下所示,实验目标是同一HTML文档,分别使用webscrpaing库中的xpath,lxml库中的xpath以及正则表达式提取100次,统计各方法的用时:
view plain copy to clipboard print ?
-
# coding: utf-8
-
# xpath_speed_test.py
-
-
import re
-
import time
-
from lxml import etree
-
from webscraping import common, download, xpath
-
-
TEST_TIMES = 100
-
-
def test():
-
url = 'http://hotels.ctrip.com/international/washington26363'
-
html = download.Download().get(url)
-
html = common.to_unicode(html)
-
-
# 测试webscraping库的xpath提取速度
-
start_time = time.time()
-
for i in range(TEST_TIMES):
-
for hid, hprice in zip(xpath.search(html, '//div[@class="hlist_item"]/@id' ), xpath.search(html, '//div[@class="hlist_item_price"]/span' )):
-
#print hid, hprice
-
pass
-
end_time = time.time()
-
webscraping_xpath_time_used = end_time - start_time
-
print '"webscraping.xpath" time used: {} seconds.' .format(webscraping_xpath_time_used)
-
-
-
# 测试lxml库xpath提取速度
-
start_time = time.time()
-
for i in range(TEST_TIMES):
-
root = etree.HTML(html)
-
for hlist_div in root.xpath( '//div[@class="hlist_item"]' ):
-
hid = hlist_div.get( 'id' )
-
hprice = hlist_div.xpath( './/div[@class="hlist_item_price"]/span' )[ ].text
-
#print hid, hprice
-
pass
-
end_time = time.time()
-
lxml_time_used = end_time - start_time
-
print '"lxml" time used: {} seconds.' .format(lxml_time_used)
-
-
# 测试正则表达式的速度
-
start_time = time.time()
-
for i in range(TEST_TIMES):
-
for hid, hprice in zip(re.compile(r 'class="hlist_item" id="(\d+)"' ).findall(html), re.compile(r '<div class="hlist_item_price"><dfn>¥</dfn><span>([\d\.]+)</span>' ).findall(html)):
-
#print hid, hprice
-
pass
-
end_time = time.time()
-
re_time_used = end_time - start_time
-
print '"re" time used: {} seconds.' .format(re_time_used)
-
-
-
if __name__ == '__main__' :
-
test()
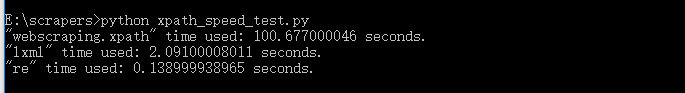
运行结果如下:
view plain copy to clipboard print ?
-
"webscraping.xpath" time used: 100.677000046 seconds.
-
"lxml" time used: 2.09100008011 seconds.
-
"re" time used: 0.138999938965 seconds.
结果很震撼:
-
正则表达式只用了0.14秒;
-
lxml的xpath用了2.1秒;
-
webscraping的xpath用了101秒!
由于xpath简单而且灵活,我们在爬虫开发的时候一般都会首选,但是通过这个实验发现它的效率远低于正则表达式,尤其是webscrpaing库中的xpath速度更是慢得恐怖。
因此,在我们的爬虫开发过程中,应该首选正则表达式,如果用正则表达式实在难于实现,再考虑xpath,另外,在使用xpath的时候一定要选用高效的库,比如lxml。特别是在数据量特别大的时候,效率显得尤为重要。
说明:该文章为鲲之鹏(http://www.site-digger.com)原创文章 ,您除了可以发表评论外,还可以转载到别的网站,但是请保留源地址,谢谢!!(尊重他人劳动,我们共同努力)
来自 “ ITPUB博客 ” ,链接:https://blog.itpub.net/30303165/viewspace-2168525/ ,如需转载,请注明出处,否则将追究法律责任。

