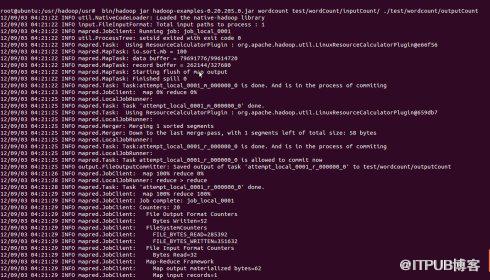
我们这次来运行Hadoop,首先来个简单的分词程序。
<!-- 正文结束 -->
主要目的是来实践一下,Hadoop本身含有一些实例代码,分词就是其中之一。
首先,我们在hadoop目录下创建我们的文件夹
mkdir test
mkdir
test/wordcount
mkdir
test/wordcount/input
然后创建作为输入的文本文件
touch test/wordcount/input/f1
echo hello world hello hadoop> ./test/wordcount/input /f1
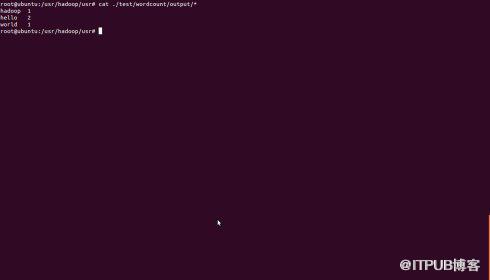
现在,查看结果
cat ./test/wordcount/outputCount/*
下面,我们修改wordcount的代码来实现我们需要的功能
来自 “ ITPUB博客 ” ,链接:https://blog.itpub.net/26155572/viewspace-1119903/ ,如需转载,请注明出处,否则将追究法律责任。
上一篇:
没有了~
下一篇:
没有了~

请登录后发表评论
登录
全部评论
