MapReduce 重要组件——Partitioner组件
(1)Partitioner组件可以让Map对Key进行分区,从而可以根据不同的key来分发到不同的reduce中去处理;
if(key.toString().equals("shoes"))
//转发给4个不同的reducer
return 0;
if(key.toString().equals("hat"))
return 1;
if(key.toString().equals("stockings"))
return 2;
public static void
main(String[] args) throws IOException, ClassNotFoundException,
InterruptedException{
Configuration conf = new
Configuration();
String[] otherArgs = new
GenericOptionsParser(conf, args).getRemainingArgs();
if (otherArgs.length !=
2) {
System.err.println("Usage: wordcount ");
System.exit(2);
}
Job job = new Job(conf,
"word count");
job.setJarByClass(TestPartitioner.class);
job.setMapperClass(MyMapper.class);
job.setReducerClass(MyReduer.class);
job.setPartitionerClass(MyPartitioner.class);
job.setNumReduceTasks(4);
//设置4个reducer
job.setOutputKeyClass(Text.class);
job.setOutputValueClass(IntWritable.class);
FileInputFormat.addInputPath(job, new
Path(otherArgs[0]));
FileOutputFormat.setOutputPath(job, new
Path(otherArgs[1]));
System.exit(job.waitForCompletion(true) ? 0 :
1);
}
<!-- 正文结束 -->
(2)你可以自定义key的一个分发股则,如数据文件包含不同的省份,而输出的要求是每个省份输出一个文件;
(3)提供了一个默认的HashPartitioner。
自定义Partitioner:
(1)继承抽象类Partitioner,实现自定义的getPartition()方法;
(2)通过job.setPartitionerClass()来设置自定义的Partitioner;
Partitioner类见org.apache.hadoop.mapreduce.Partitioner类。
Partitioner应用场景:
需求:分别统计每种商品的周销售情况
site1的周销售清单(a.txt):
shoes 20
hat
10
stockings 30
clothes 40
......
site2的周销售清单(b.txt):
shoes
15
hat
1
stockings 90
clothes 80
......
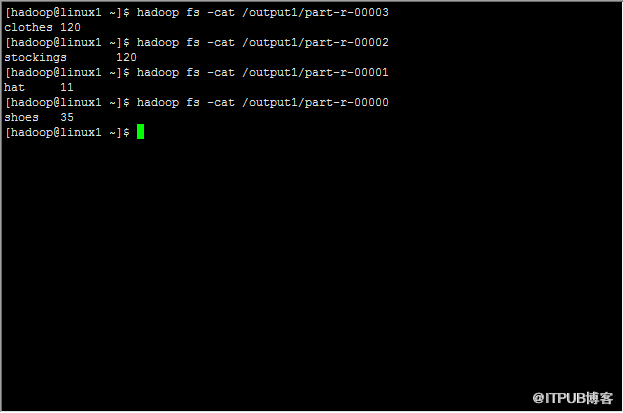
汇总结果:
shoes
35
hat
11
stockings 120
clothes
120
新建项目TestPartitioner,包com.Partitioner,
源代码MyMapper.java:
package com.partitioner;
import java.io.IOException;
import org.apache.hadoop.io.IntWritable;
import org.apache.hadoop.io.LongWritable;
import org.apache.hadoop.io.Text;
import org.apache.hadoop.mapreduce.Mapper;
public class MyMapper extends Mapper {
@Override
protected void map(LongWritable key, Text value,Context
context)
throws IOException, InterruptedException {
String[] s = value.toString().split("\s+");
context.write(new Text(s[0]), new
IntWritable(Integer.parseInt(s[1])));
}
}
源代码MyReduer.java:
package com.partitioner;
import java.io.IOException;
import org.apache.hadoop.io.IntWritable;
import org.apache.hadoop.io.Text;
import org.apache.hadoop.mapreduce.Reducer;
public class MyReduer extends Reducer {
@Override
protected void reduce(Text key, Iterable value,Context
context)
throws IOException, InterruptedException {
int sum = 0;
for(IntWritable val:value){
sum += val.get();
}
context.write(key, new IntWritable(sum));
}
}
源代码MyPartitioner.java:
package com.partitioner;
import org.apache.hadoop.io.IntWritable;
import org.apache.hadoop.io.Text;
import org.apache.hadoop.mapreduce.Partitioner;
public class MyPartitioner extends Partitioner {
@Override
public int getPartition(Text key, IntWritable value, int
numPartitons) {
return 3;
}
}
源代码TestPartitioner.java:
package com.partitioner;
import java.io.IOException;
import org.apache.hadoop.conf.Configuration;
import org.apache.hadoop.fs.Path;
import org.apache.hadoop.io.IntWritable;
import org.apache.hadoop.io.Text;
import org.apache.hadoop.mapreduce.Job;
import
org.apache.hadoop.mapreduce.lib.input.FileInputFormat;
import
org.apache.hadoop.mapreduce.lib.output.FileOutputFormat;
import org.apache.hadoop.util.GenericOptionsParser;
public class TestPartitioner {
}
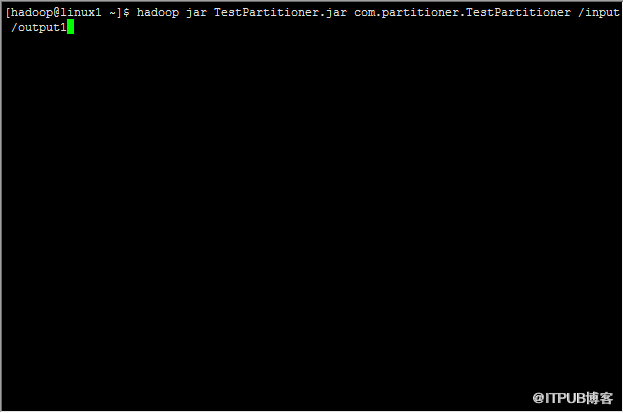
将此项目打包为TestPartitioner.jar,并将上面提到的a.txt和b.txt上传到hdfs上的/input文件夹下,
运行TestPartitioner.jar:
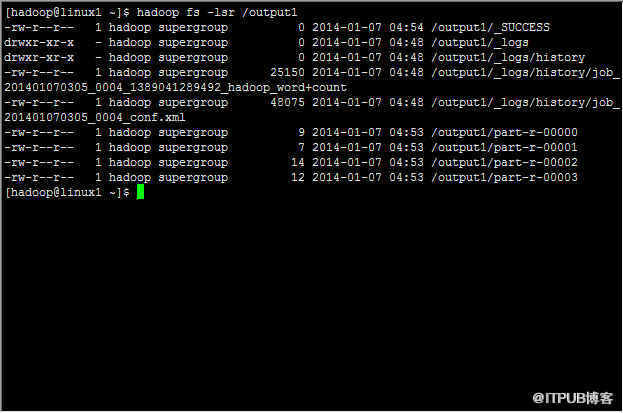
可以看到四个reducer产生的文件:
其中内容,可见统计结果分开了:
先到这里吧。。

来自 “ ITPUB博客 ” ,链接:https://blog.itpub.net/15444227/viewspace-1120581/ ,如需转载,请注明出处,否则将追究法律责任。
上一篇:
没有了~
下一篇:
没有了~

请登录后发表评论
登录
全部评论
